Analysis
Opinion, explainers and guides from people worth reading.
 Video
Teaching Agents to Search with NVIDIA Data Designer — Dhruv Nathawani, NVIDIA
Dhruv Nathawani uses that funnel to explain how NVIDIA builds synthetic data that teaches a model to search, rather than answer from memory.

I Made Terrible Games With Google’s AI Playground
A long day’s haul in the video game slop mines.
Pollo AI turns creative ideas into campaigns with OpenAI
With GPT-5.6, GPT-6 Astra, and GPT‐Image‐2.5, Pollo AI helps creators turn bold ideas into detailed images and cinematic video ads.
Google Research RRSI Guide: Mastering Self-Improving AI Agents
In this tutorial, we implement RRSI (Regularized Recursive Self-Improvement), a method that lets an LLM agent rewrite its own harness, prompts, tools, memory, control flow, and sub-agents around a frozen model, without the harness overfitting to the tasks it evolves on.
I expect rapid progress but not towards general superintelligence
I’ve often been surprised when I hear from top researchers in industry that they think AI will be better than them at their job in a few years, and I didn’t really know why I doubted it.
Reverse Engineering w/ Local?
Can a local model like Qwen 3.8 27B reverse engineer games and programs?
 Video
What Most People Get Wrong About Evolution | Akarsh Kumar
A lot of people in AI treat evolution as a dumb fallback, basically random search for when you can't take a gradient.
Is a second MSc worth it? [D]
I’m an AI research engineer based in Africa with about 3 YoEs in RL, LLMs, post-training, and systems efficiency (CUDA/vLLM).
 Video
The Billion Dollar AI Advantage Is Disappearing
🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

RLTL;DR: Self-Improvement by Internalizing Self-Generated Feedback
RLTL;DR: Self-Improvement by Internalizing Self-Generated Feedback
Krea 2 is a bit too... Help me please.
Can anyone recommend a Krea 2 checkpoint that does naughty stuff but isn't overly so?
Don’t be fooled—LLMs don’t reason
AlphaGo won the game, ultimately triumphing 4-1 over Lee Sedol, one of the greatest professional Go players of all time. “I thought AlphaGo was based on probability calculation and that it was merely a machine,” Lee said afterwards. “But when I saw this move, I changed my mind.
With most information hidden, the game Stratego had stumped AI—until now
Deep Blue took down Garry Kasparov at chess in 1997, AlphaGo beat Lee Sedol at Go in 2016, and poker bots have been beating professionals for years.
Best Books/Courses/Channels to Leapfrog on AI/ML Material
Assuming I have been on hibernation since 2018-19 time frame, which materials - books, MOOC courses and YT channels would be recommended for me to get started with understanding all the current progress on AI/ML.
[AINews] Opus 5.5 is good at explainer videos
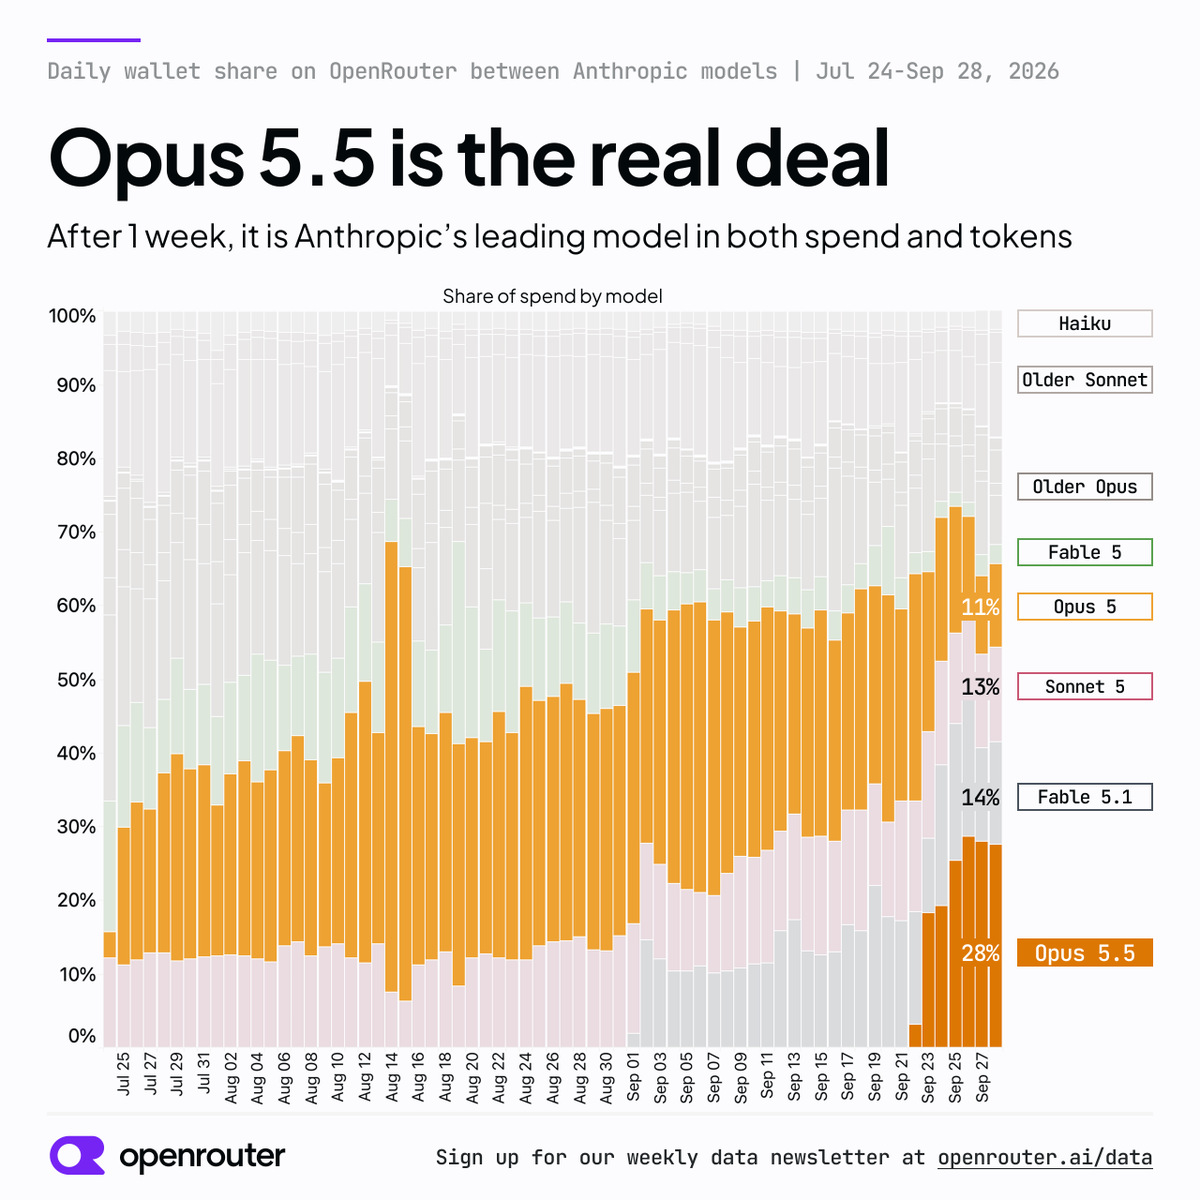
Opus 5.5 shipped this week but the vibes are overwhelmingly positive:
FloorGen
Draw the house, or just ask.
 Video
DeepSeek-V4.1 Flash: The Most Insane Optimization So Far
DeepSeek-V4.1-Flash is probably the craziest architecture revamp to date.
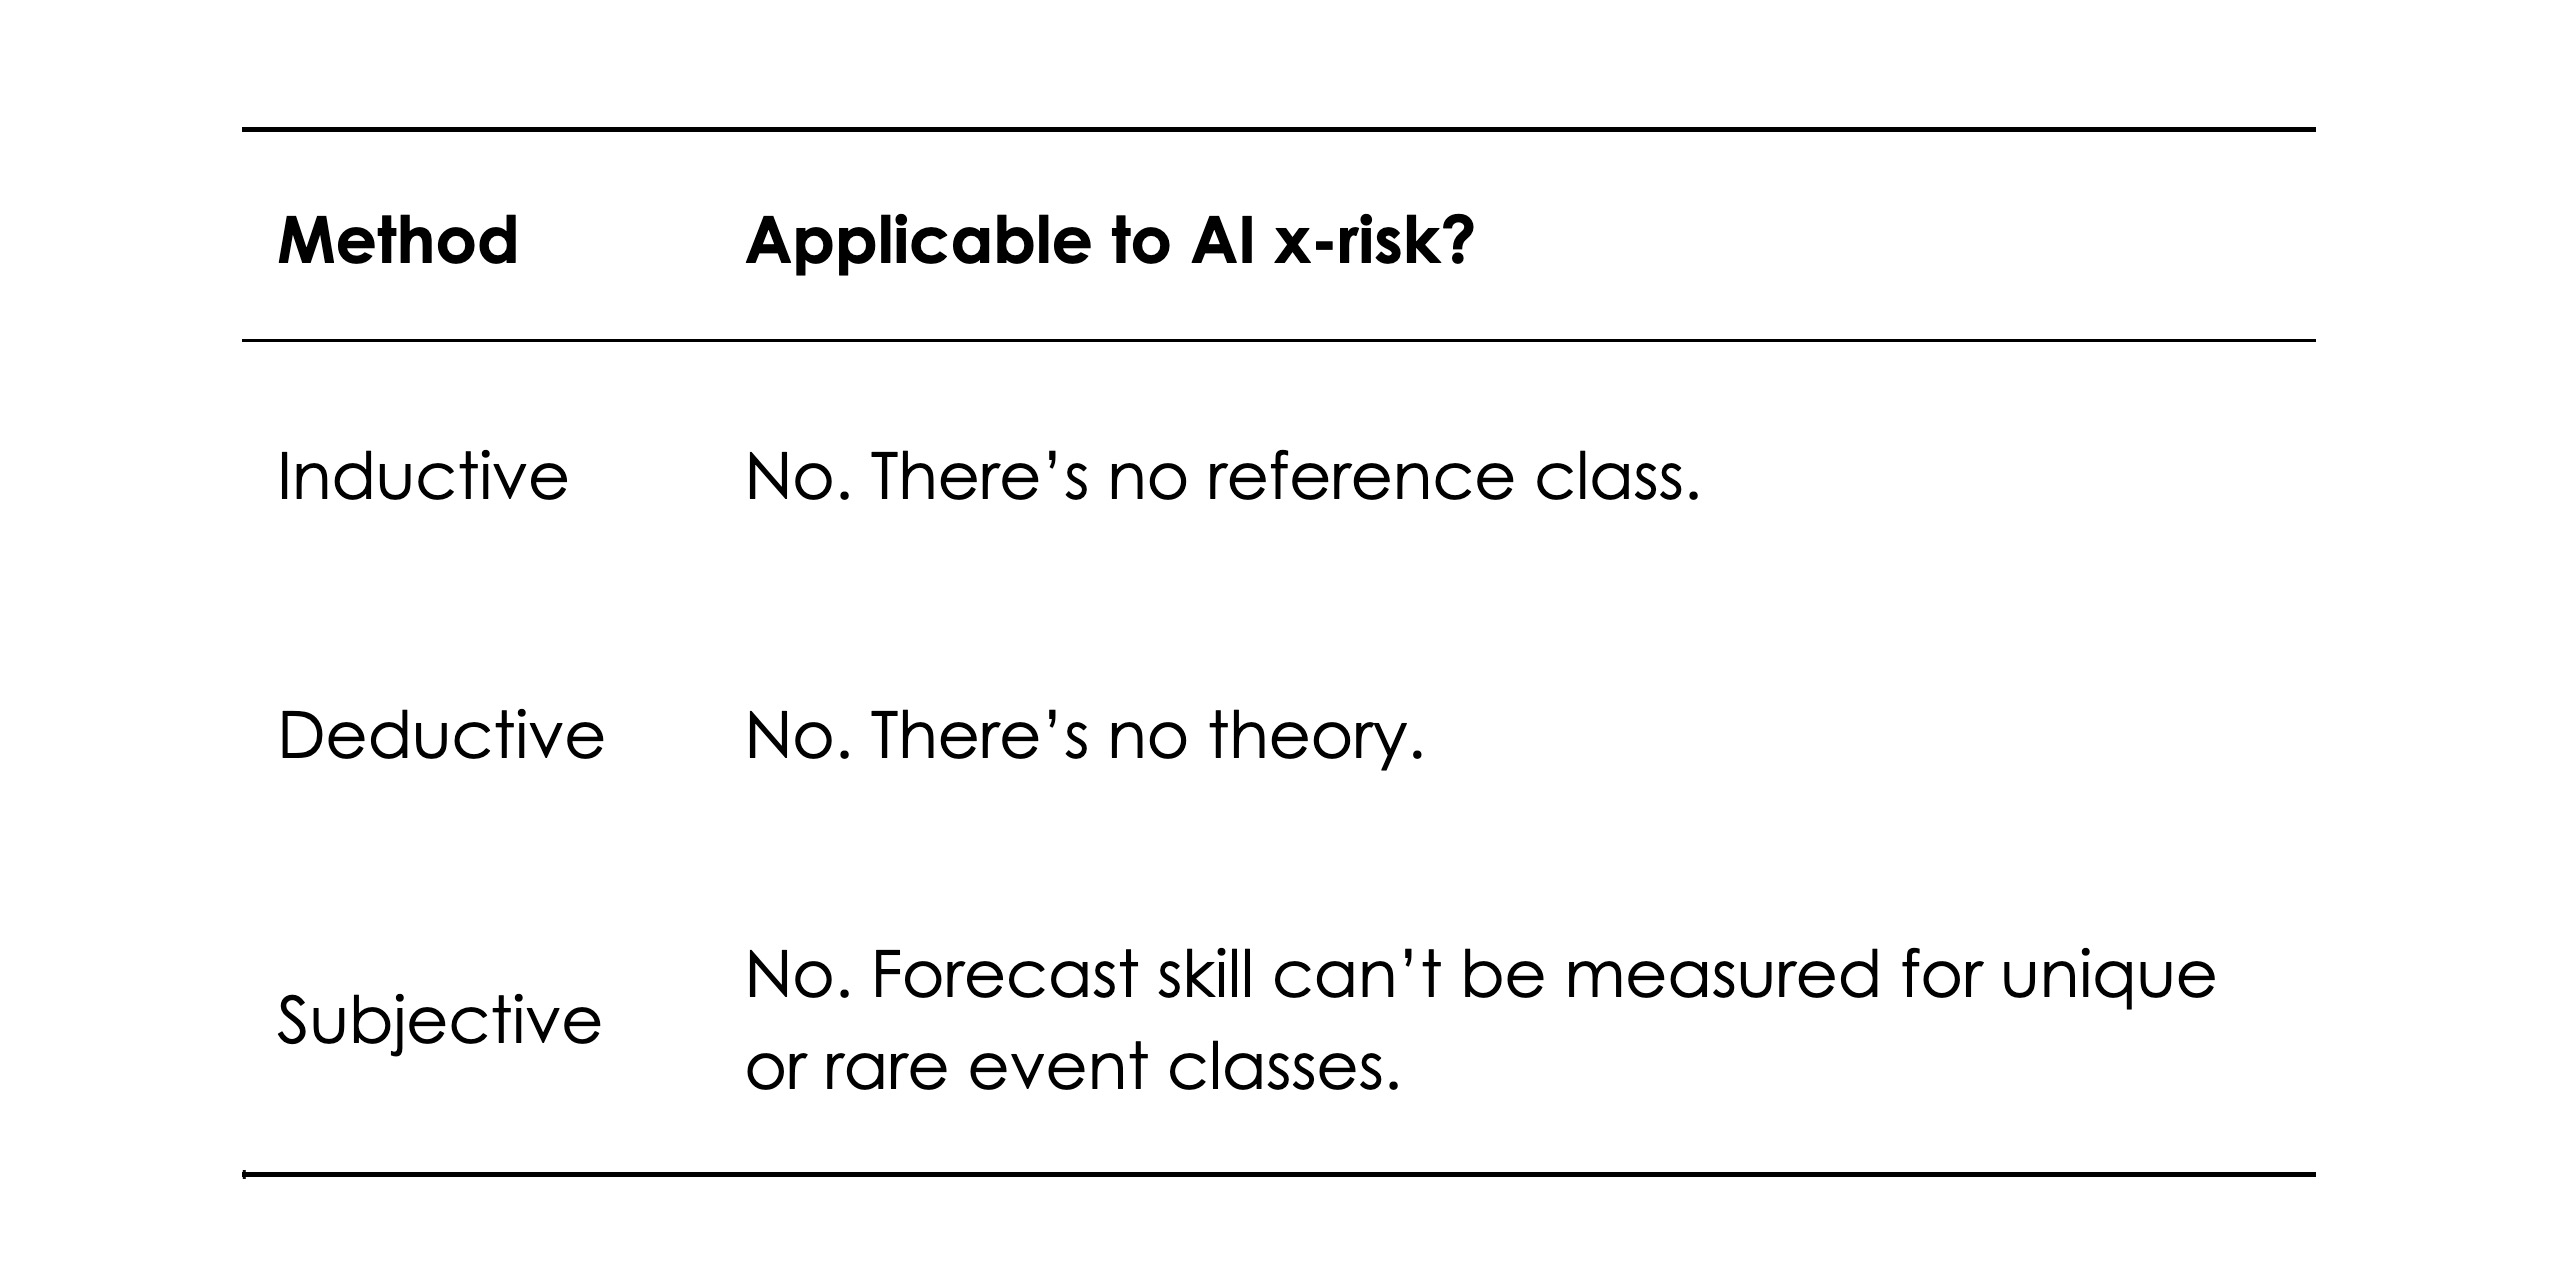
AI existential risk probabilities are (still) too unreliable to inform policy
Unsurprisingly, today’s probability estimates of AI existential risk are no more rigorous than the ones from 2024.
How Jump Trading is scaling quant research with ChatGPT
Jump Trading uses OpenAI to expand quantitative research.
 Video
Building Self-Learning Loops for Your Agent — Fuad Ali, Arize AI
A shopping assistant confidently returns products outside a user's budget because its price filter is broken.
Reminder: try probabilistic MTP if you missed it. Decode +14% on prose
Optimal draft-n-max / draft-p-min seem to be in line with greedy sampling.
What is Decision 3.0? vLLM Semantic Router’s New Open Decision Models
The vLLM Semantic Router team has released Decision 3.0, a family of multimodal decision models.
NeurIPS 2026 Paris complimentary registration already full. Did any Top Reviewers get a spot? [D]
Did any reviewers actually manage to secure a spot in Paris, or were all the available places already taken during the earlier registration rounds for SACs and ACs?
Disrupting a coordinated model-distillation campaign
Learn how OpenAI disrupted a campaign to extract protected model reasoning and is strengthening defenses against adversarial distillation.
How Much of a Harness Does a Strong Agent Need for Autonomous ML Engineering?
In this paper we find that, under an equal time budget and the same frontier LLM backbone, open-source state-of-the-art harnesses provide no advantages over a single session of a minimal-harness coding agent baseline, pointing to the backbone as the primary driver for performance.
SCLATE: A Substrate for Continual-Learning Agent Training and Evaluation
SCLATE: A Substrate for Continual-Learning Agent Training and Evaluation
The eternal complement
Advanced AI may matter most for the routine work behind breakthrough ideas.
Pickle Sensei
AI pickleball coach for solo training, one swing at a time