Analysis
Opinion, explainers and guides from people worth reading.
Why AlphaFold Didn't Solve Protein Folding — Pushmeet Kohli, Google DeepMind & Sal Candido, Biohub
From the Bitter Lesson of AI scaling to the unsolved mysteries of protein folding, Google DeepMind’s Pushmeet Kohli and Biohub’s Sal Candido are rethinking what it takes to build AI that truly understands biology.

I trained a 414k-parameter transformer to fly a boids flock, then tested whether the rules a probe can read are the ones it uses [P]
I wrote a small boid simulator (12 birds), recorded it flying, and trained a transformer to predict each bird's next move without it knowing about any boid rules.
Google Research RRSI Guide: Mastering Self-Improving AI Agents
In this tutorial, we implement RRSI (Regularized Recursive Self-Improvement), a method that lets an LLM agent rewrite its own harness, prompts, tools, memory, control flow, and sub-agents around a frozen model, without the harness overfitting to the tasks it evolves on.

Krea2 Turbo Distill 2 step LoRA - FINAL checkpoint released (chk51195)
Krea 2 Turbo — 2-Step Distillation LoRA (FINAL Version)
I expect rapid progress but not towards general superintelligence
I’ve often been surprised when I hear from top researchers in industry that they think AI will be better than them at their job in a few years, and I didn’t really know why I doubted it.
Fine-Tuning NVIDIA Nemotron for Saudi Arabic Dialects, with a Path to Other Languages
Automatic speech recognition must handle how people actually speak, not only the languages and styles that dominate pretraining data.
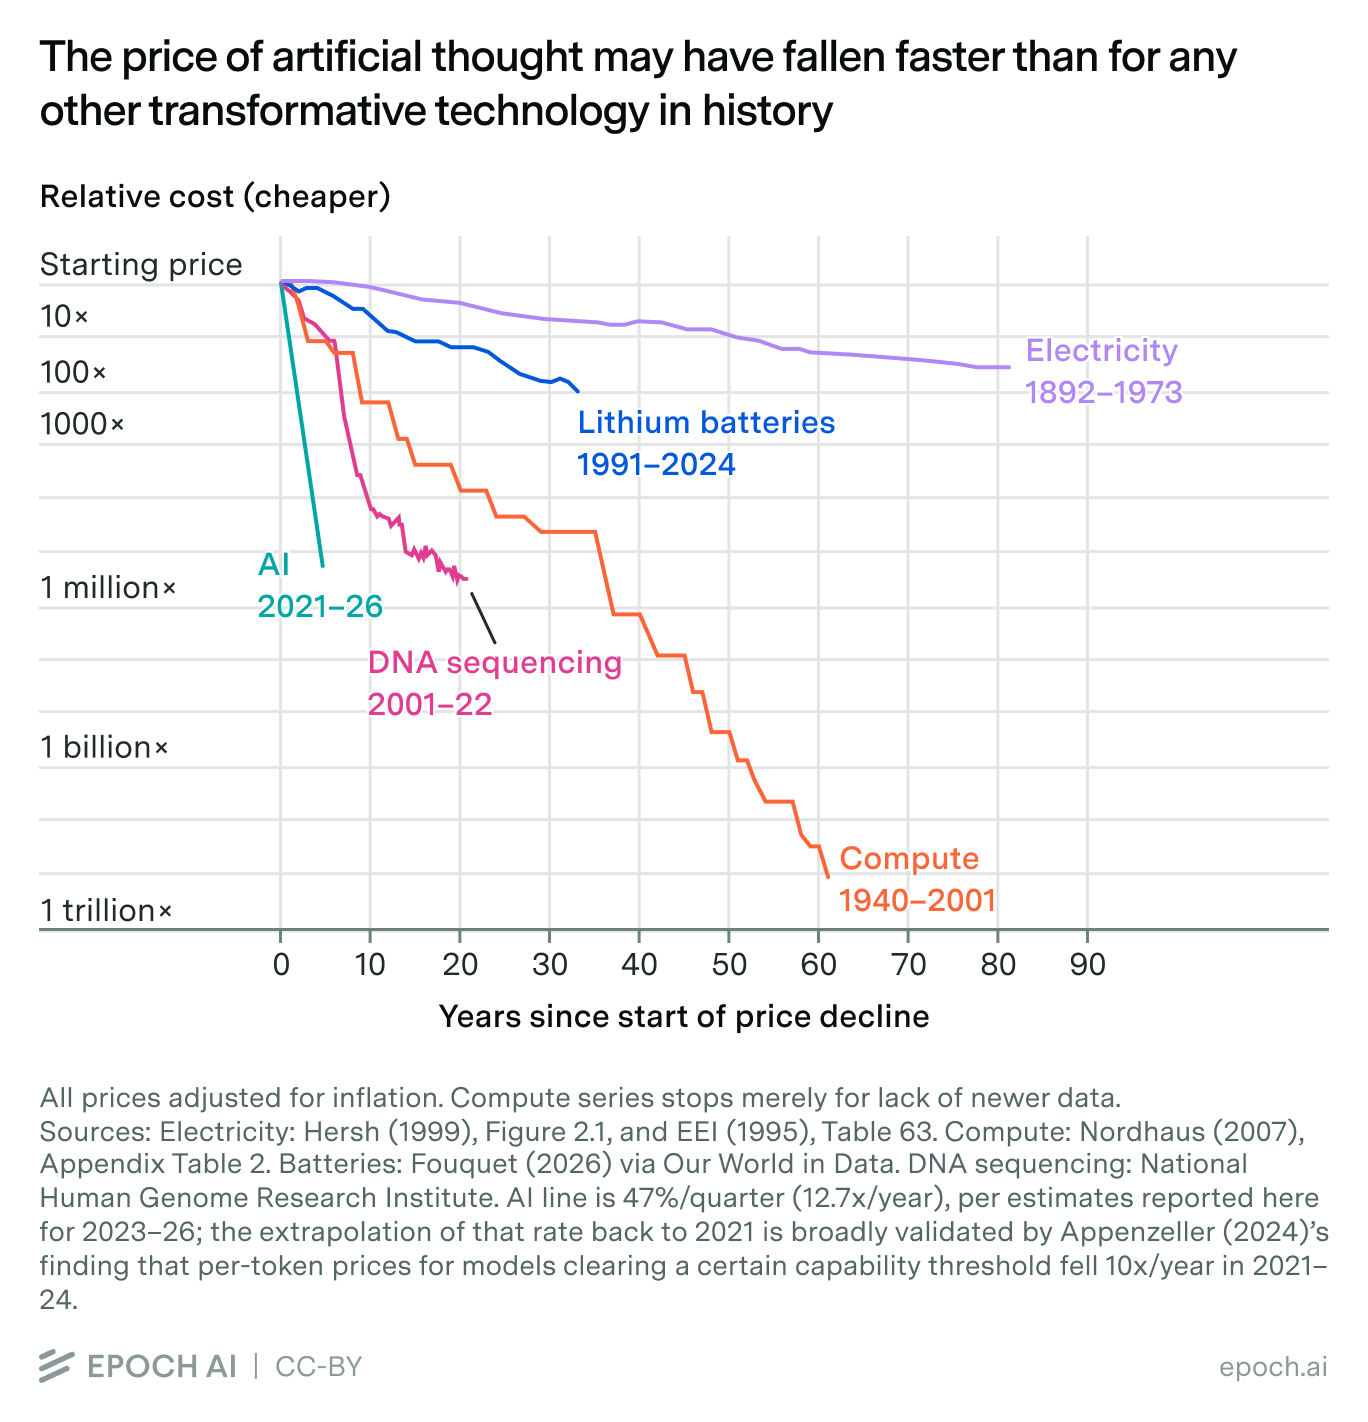
AI is getting cheaper faster than any other transformative technology
Because that’s how fast AI is getting cheaper.
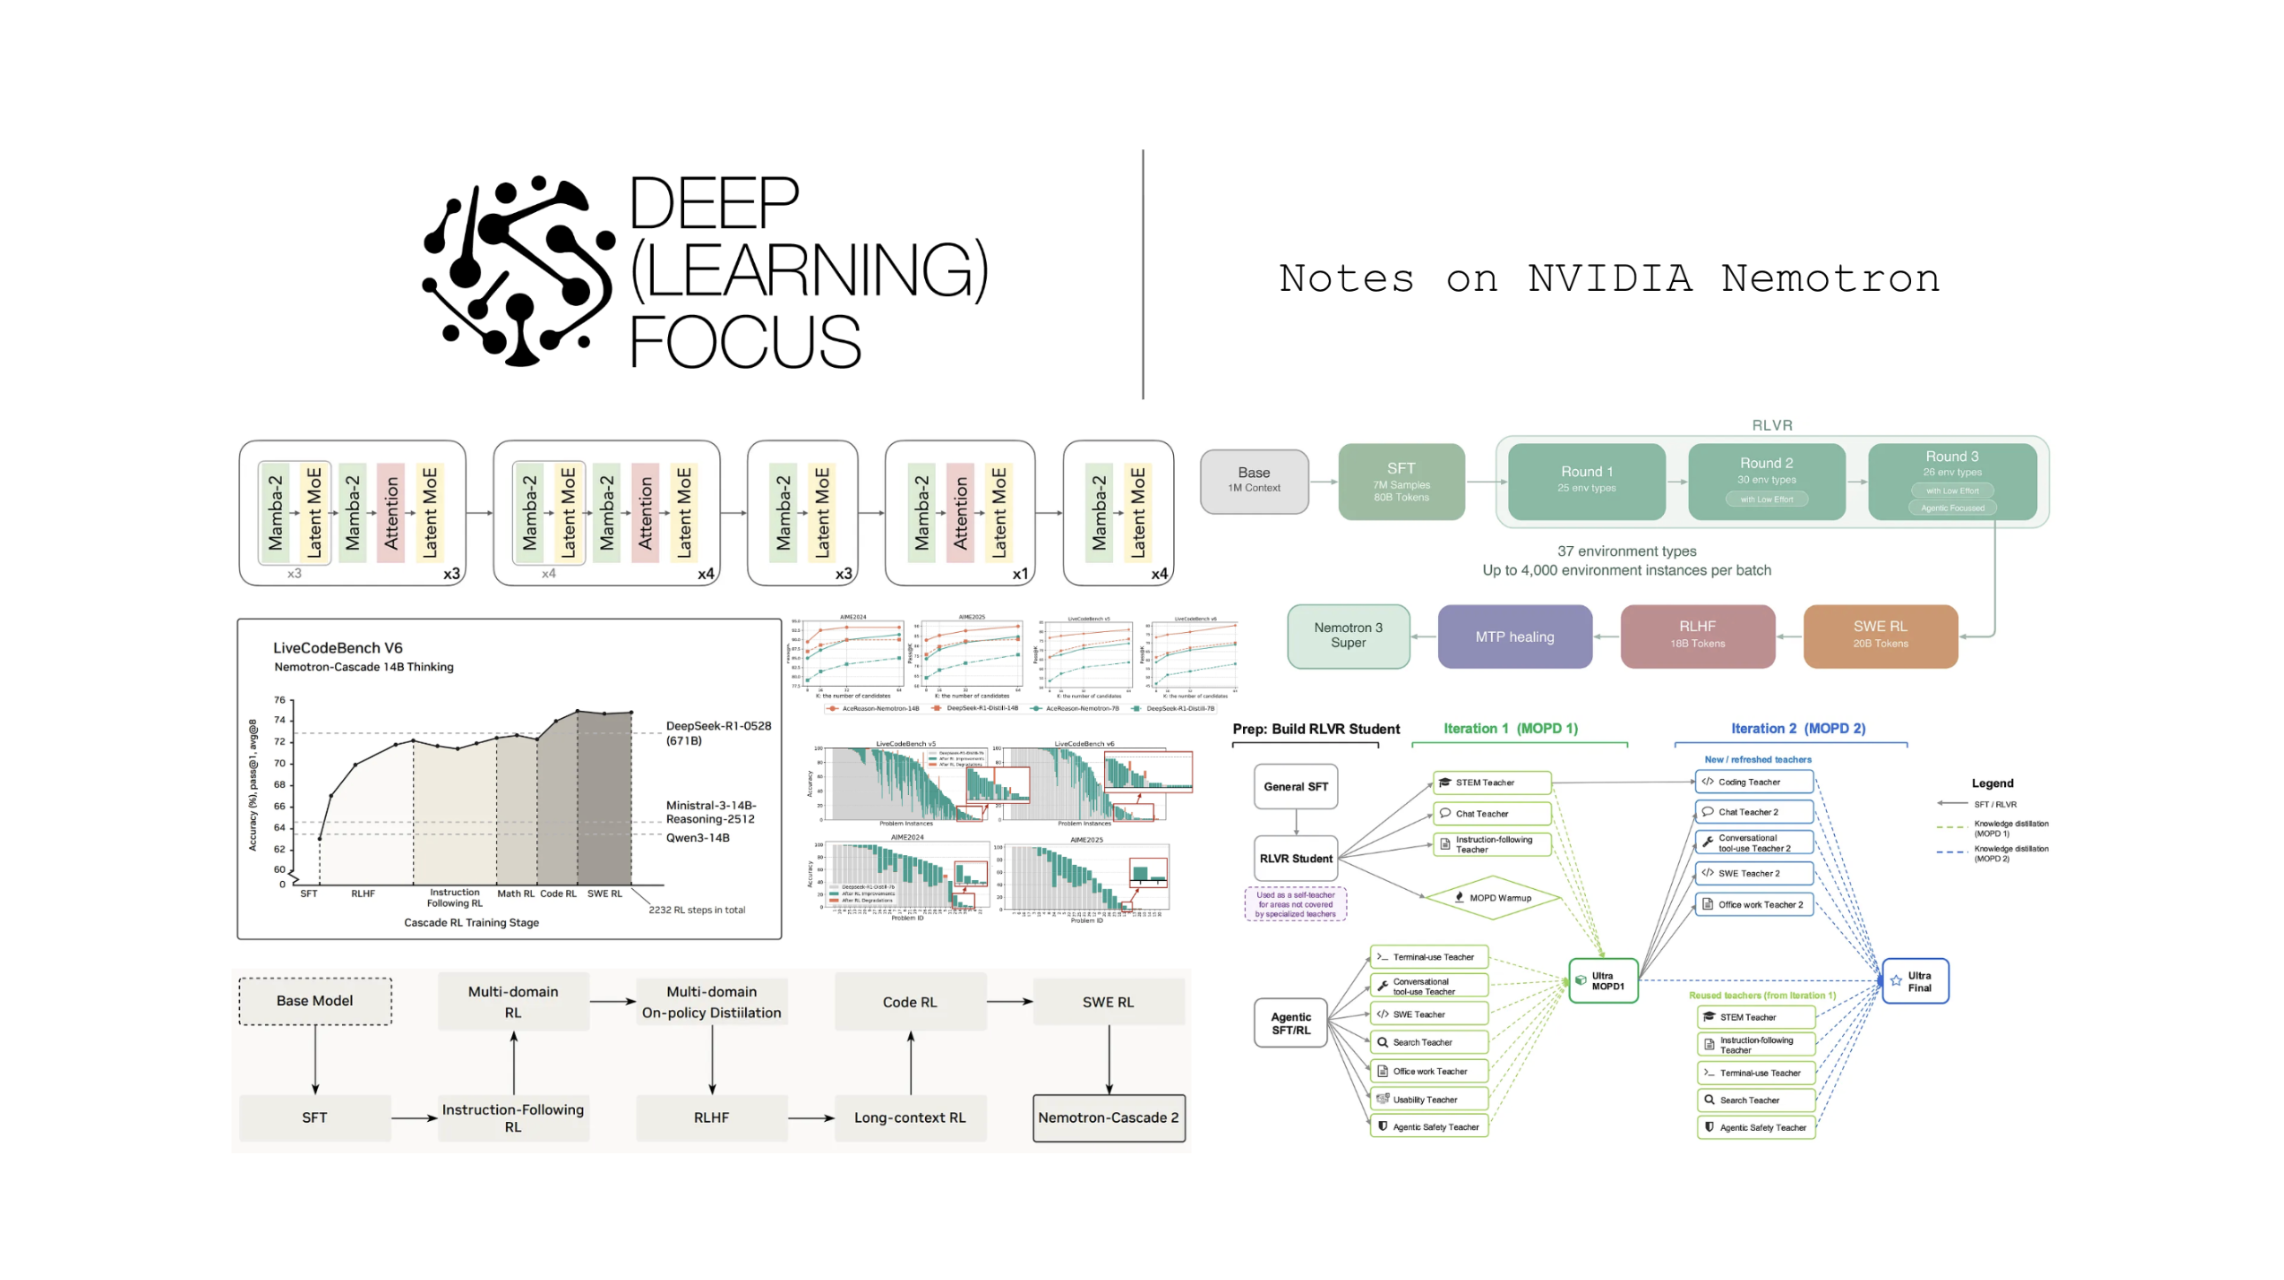
Notes on NVIDIA Nemotron
Today, many key details of frontier large language models (LLMs) remain proprietary, but open-weights model families—such as DeepSeek, Kimi, and MiMo—continue to provide a valuable window into the development process for modern LLMs. Among these resources, the NVIDIA Nemotron model series is especially useful due to its transparency.
Forecasting space weather risks on power grids
End-to-end forecasting: A machine learning pipeline uses forecast-time solar-wind information to generate location-specific risk estimates for 66,935 substations in the continental United States.

SCLATE: A Substrate for Continual-Learning Agent Training and Evaluation
SCLATE: A Substrate for Continual-Learning Agent Training and Evaluation
Show HN: TerrainSR – fast, realistic heightmap upscaling model
I wanted to have a 1:1 scale model of Europe, but my problem was that 100m data was too low-res while 10m LIDAR data was patchy, took hundreds of GBs to store and was full of manmade objects like mines, buildings and so on.
Show HN: Strata – an expressive semantic layer that can say no to your LLM
Hello HN, I'm Ajo and I built Strata.
Si Sheppard – How did a few hundred Spanish soldiers topple two empires?
New episode with military historian Si Sheppard.

Master AI Chip Principles With New IEEE Design Program
Today’s engineers face an unprecedented acceleration in AI hardware complexity, as explained in the recent research article “Revisiting Edge AI: Opportunities and Challenges.” The article examines the rapid growth of edge AI and the challenges it creates, including resource constraints, model architecture limitations, and network demands across edge-AI deployments.
Pickle Sensei
AI pickleball coach for solo training, one swing at a time

Qwen Image 2.1 Turbo - extend 'magic' 8 steps sigmas further
So, I've decided to try Qwen Image 2.1 Turbo with the following 'magic' sigmas, taken directly from their Diffusers implementation: