Models
New and updated models, and how they score.
 Video
Same Model, Different Speed: Why Your Inference Provider Matters — FriendliAI
Open-weight models are good enough now.
[AINews] not much happened today
AINews’ website lets you search all past issues.
Mistral Large 4
llm -m gpt-6.1-sol 'Generate an SVG of an armadillo in fishnet tights jaywalking on Mars'
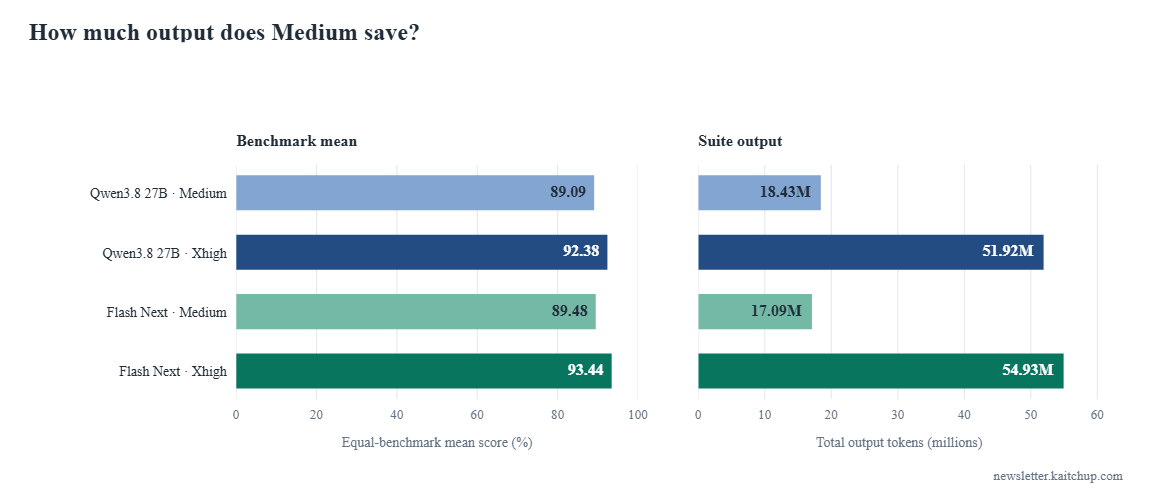
Qwen3.8 27B Xhigh or Flash Next Medium
In my Qwen3.8 27B reasoning benchmarks, Xhigh generally produced the strongest results, but it needed much longer responses than Medium.
 Video
Which is The Best Qwen3.8-27B?
Which is the best fine-tune of Qwen3.8 27B that reduces the amount of thinking and reasoning tokens but still keeps the best accuracy for your particular use case?
Nace AI Open-Sources Drex 1.5: A 9B Decision Model That Scores Options, Not Text
Nace.AI has open-sourced Drex 1.5, a 9B decision model for agents and backend workflows.
ReviewBench: An open benchmark for AI code review
Agentic code review is becoming an essential piece of how development happens.
Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning
TLDR 👉 new TTS leaderboard focused on open-source and multilingual
 Video
Why Deep Learning Failed on Tables for a Decade - Frank Hutter
Frank Hutter, co-founder of Prior Labs, on why deep learning struggled with tabular data for a decade: tables are messy and heterogeneous, hyped models like TabNet did not generalise to new datasets, and there was no ImageNet of tables.
 Video
Hill-Climbing Skills: Improve Agents Without Changing the Model — Shubhankar Srivastava, Browserbase
Shubhankar Srivastava uses that uneven progress to show how browser agents can learn a task without changing model weights.
 Video
From Zero to Leaderboard: Agent Evaluation — Wolfram Ravenwolf, Weights & Biases
An agent repairs a broken git repository and earns a perfect score, but the run stays out of the default leaderboard because it tested only one task.