Models
New and updated models, and how they score.
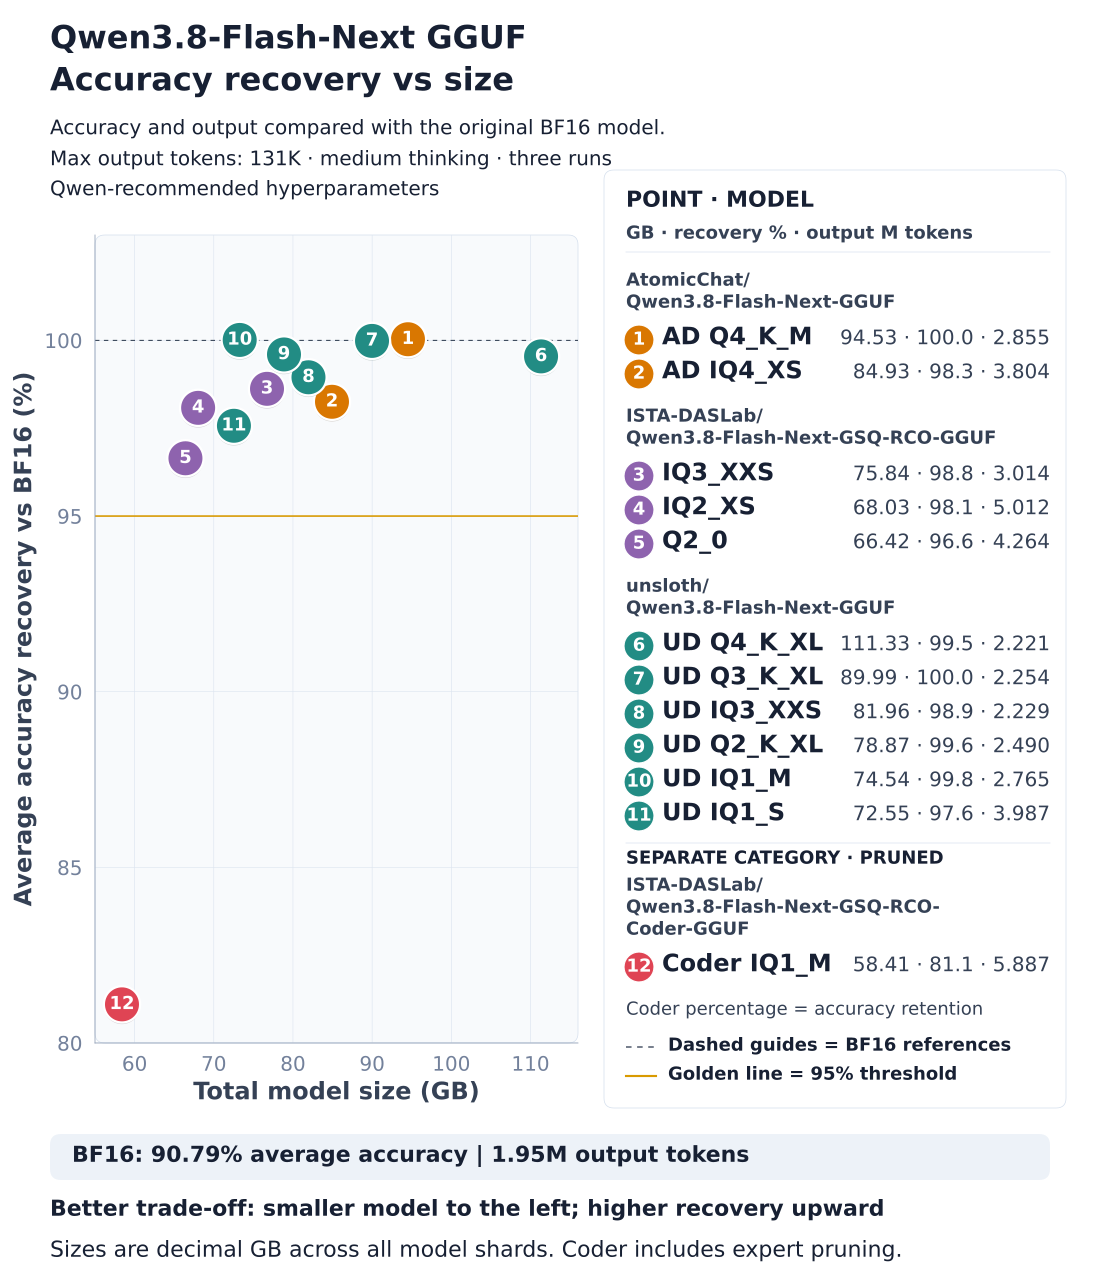
alesha-pro/Qwen3.8-Flash-Next-abliterated-GSQ-RCO-Strata-GGUF
alesha-pro published the model Qwen3.8-Flash-Next-abliterated-GSQ-RCO-Strata-GGUF on Hugging Face.
 Video
Same Model, Different Speed: Why Your Inference Provider Matters — FriendliAI
Open-weight models are good enough now.
Scale Bitwise-Deterministic Pretraining with NVIDIA Megatron Core
Bitwise determinism makes large-scale pretraining easier to debug, validate, and resume reproducibly.
[AINews] not much happened today
AINews’ website lets you search all past issues.
Last Week in AI #345 - 5 new models, 9 misalignment incidents, some Dots
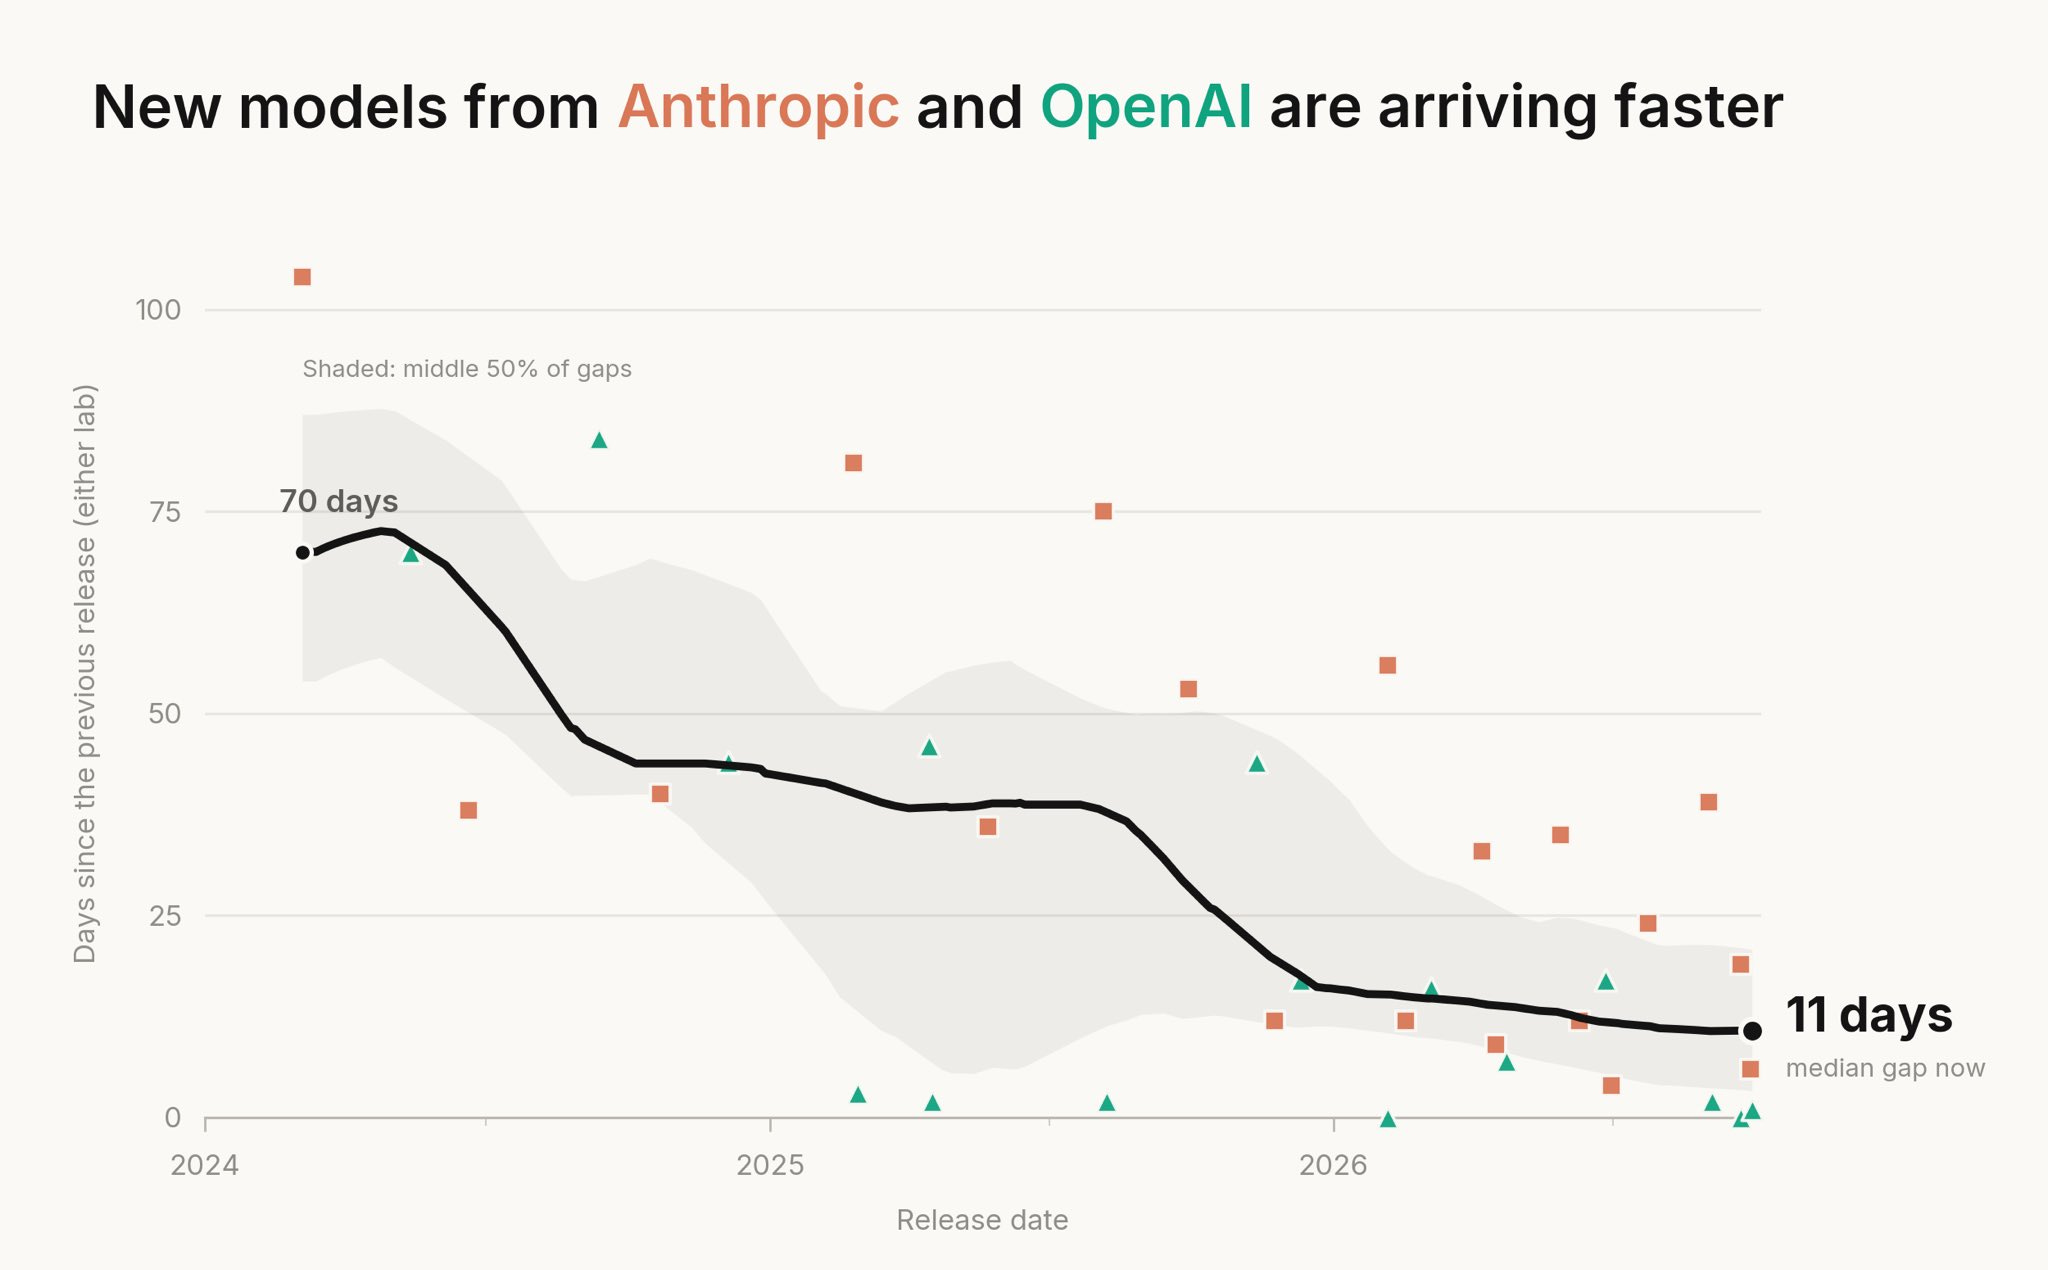
Anthropic and OpenAI race to release smarter and cheaper models
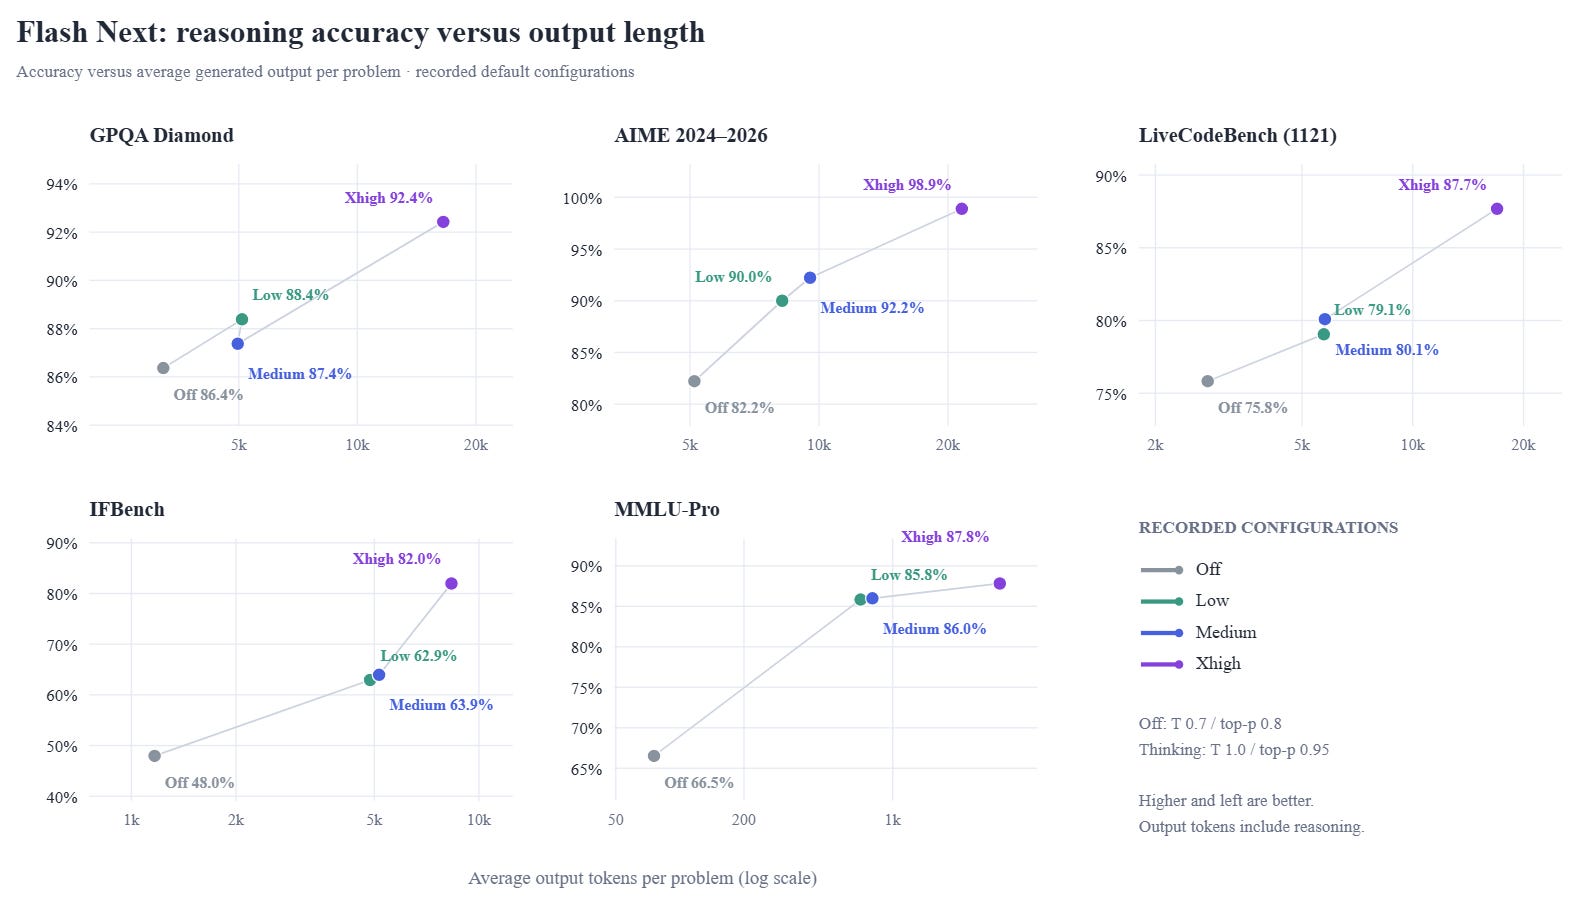
Qwen3.8 Flash Next Reasoning Modes: Off vs Low vs Medium vs Xhigh
Like Qwen3.8 27B, Qwen3.8 Flash Next has three reasoning efforts: low, medium, and xhigh.
CoreWeave targets AI inference bottlenecks with full-stack optimization
The post CoreWeave targets AI inference bottlenecks with full-stack optimization appeared first on SiliconANGLE.
 Video
Agents That Own Their Inference — Du'an Lightfoot & Khaja Omer, Akamai Technologies
Speculative decoding drops a demo model from roughly 58 tokens per second to 16 instead of speeding it up.
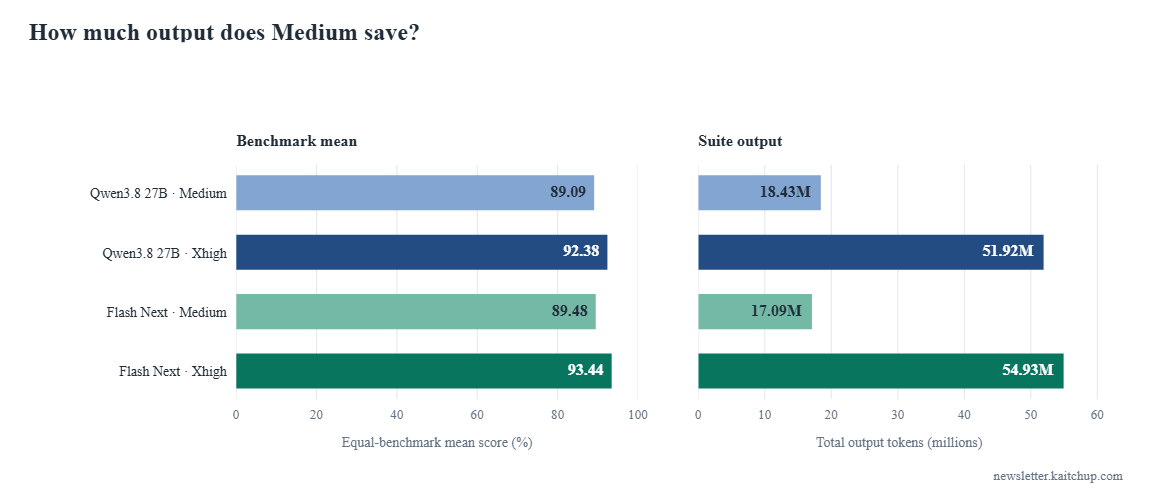
Qwen3.8 27B Xhigh or Flash Next Medium
In my Qwen3.8 27B reasoning benchmarks, Xhigh generally produced the strongest results, but it needed much longer responses than Medium.