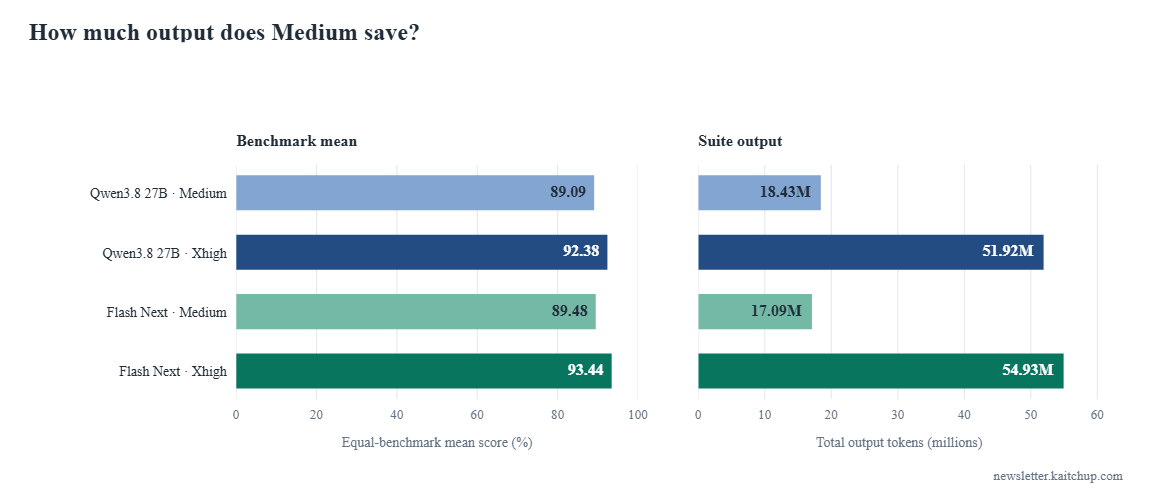
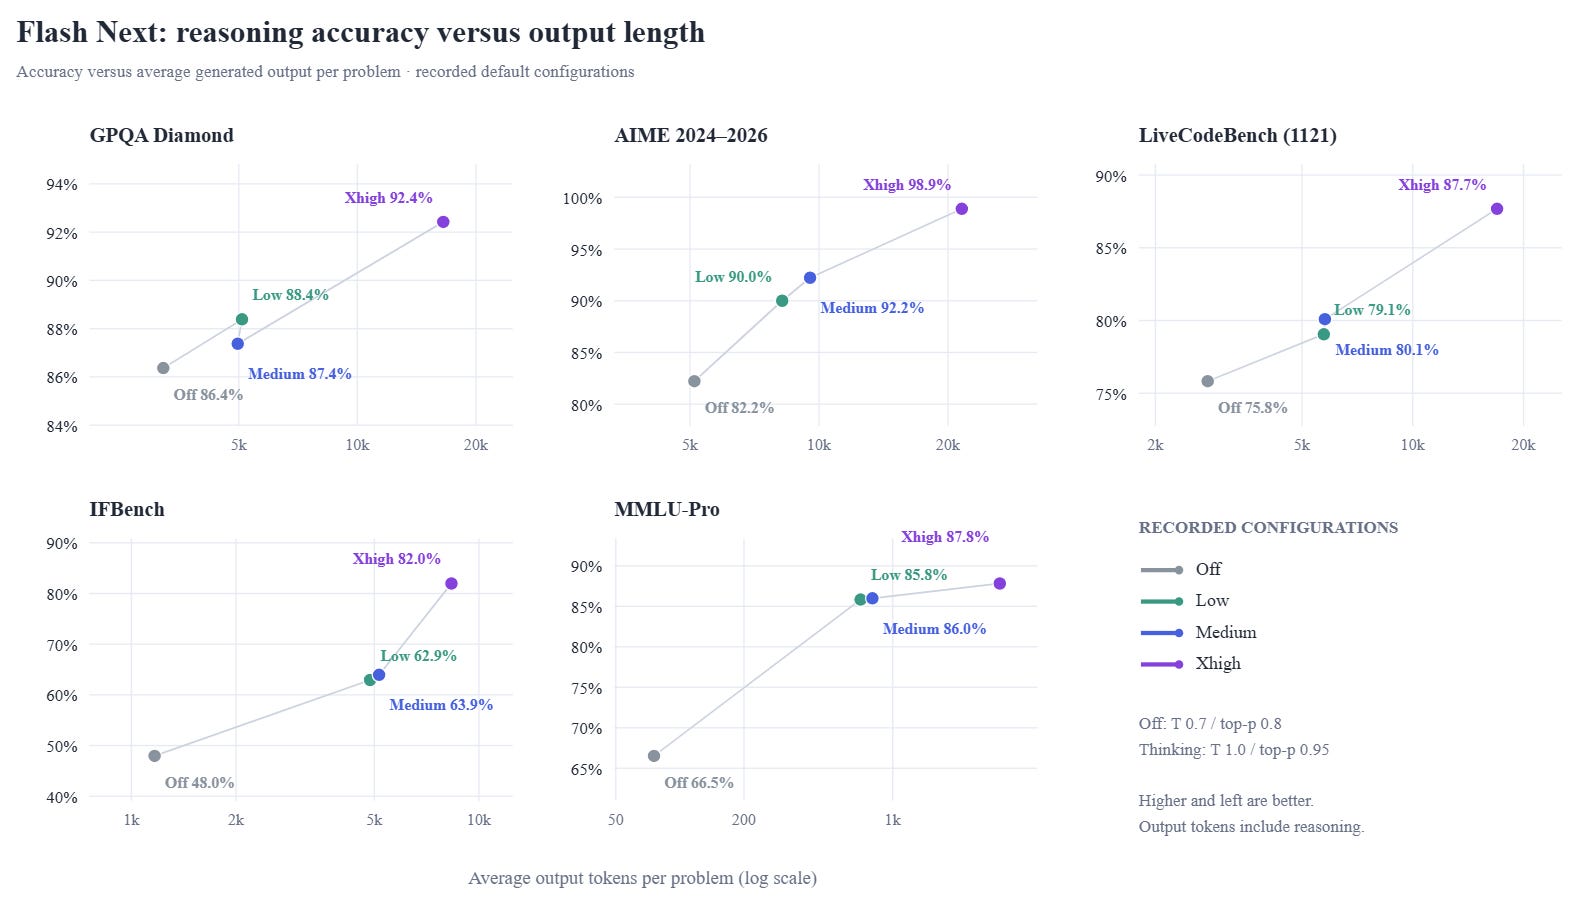
Qwen3.8 Flash Next GGUF Benchmark: Q4 to Q1 Accuracy and Token Efficiency
Quantizing Qwen3.8 Flash Next is almost unavoidable if you want to run it locally.
QuantizationUnslothQwen/Qwen3.8-Flash-NextQwen/Qwen3.8-27BISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-GGUFISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF
Proof1 independent outlet
Key points
- But after quantization, how much of the model survives?
- As we will see here, this “efficiency” evaluation is especially relevant for Qwen3.8 Flash Next.
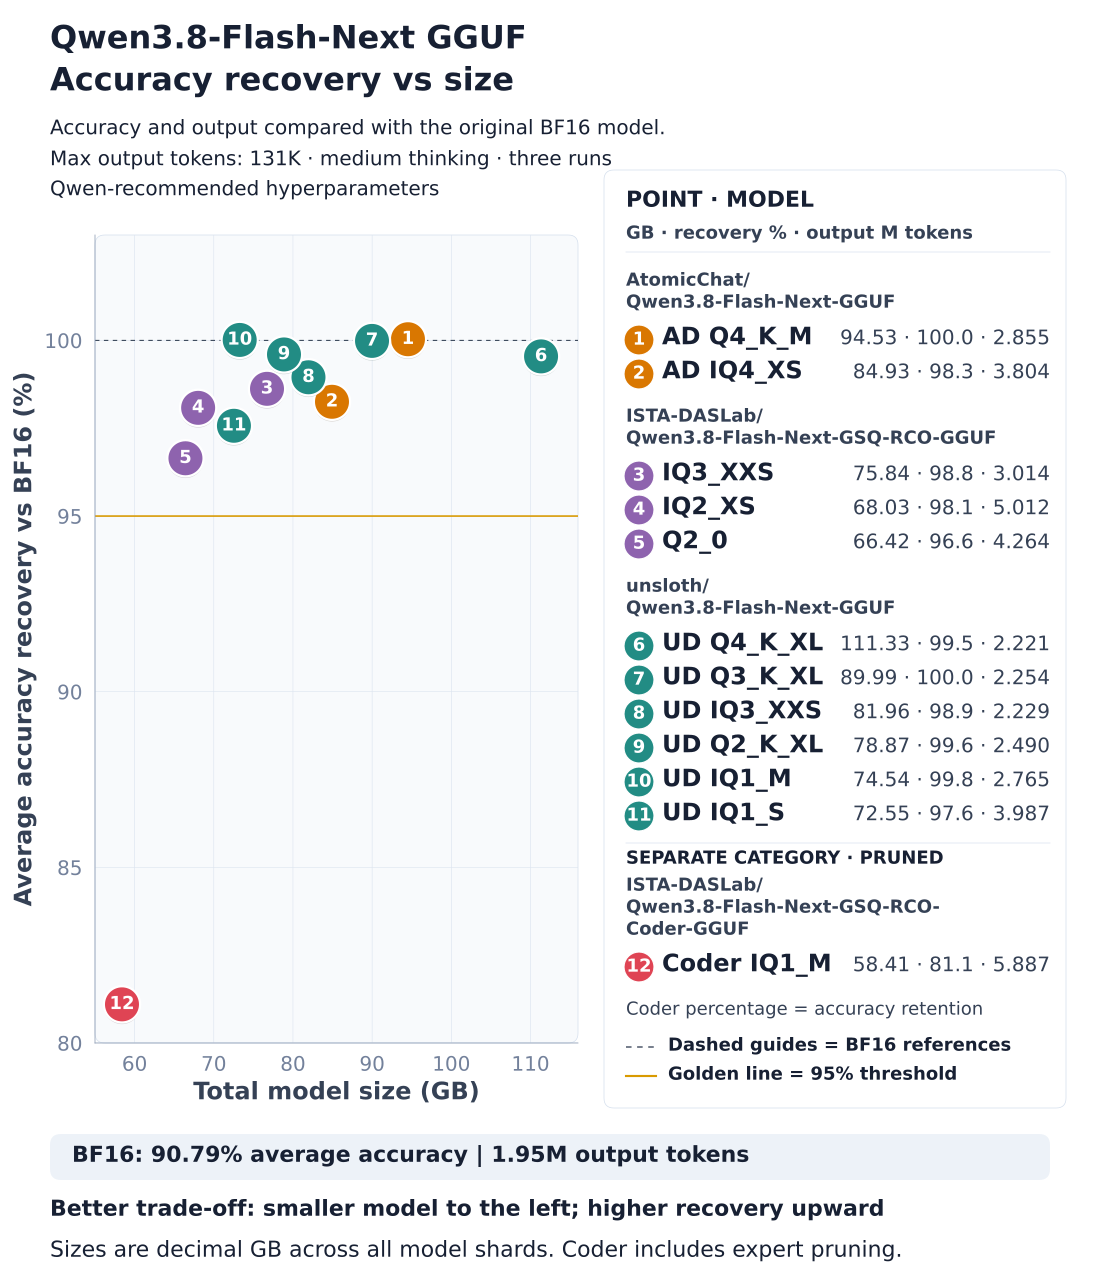
- I evaluated 11 standard quantizations, from Q4 down to Q1, plus a separate GSQ-RCO Coder release and the original BF16 reference.
- List of the evaluated Qwen3.8 Flash Next GGUF models
Sources (1)
- [1]Qwen3.8 Flash Next GGUF Benchmark: Q4 to Q1 Accuracy and Token EfficiencyThe Kaitchup (Benjamin Marie) · Sep 30, 02:40 AM
Quantizing Qwen3.8 Flash Next is almost unavoidable if you want to run it locally.
But after quantization, how much of the model survives?
Extractive summary: sentences quoted from the sources.
Before this
- Sep 29, 2026ml-explore/mlx v0.32.3
- Sep 28, 2026unslothai/unsloth v0.1.900-beta: Laya Decision Models + Library
- Sep 28, 2026Holo4: powering generalist computer-use agents
- Sep 22, 2026vllm-project/vllm v0.30.0
- Jun 10, 2026DiffusionGemma: 4x faster text generation
- Jun 9, 2026Introducing Gemma 4 12B: a unified, encoder-free multimodal model