Models
New and updated models, and how they score.
Qwen/Qwen-Image-2.1-Turbo
Qwen published the model Qwen-Image-2.1-Turbo on Hugging Face.

Microsoft's Decision-1 model enters the fast-growing AI decision model race
With Decision-1, Microsoft enters the growing decision model space.

Introducing Clef-omni with full multimodality, plus a faster Clef and a cheaper Clef-flash
Today, we’re releasing Clef-omni, which takes in audio and video input alongside text and image.
ConwayResearch/Underdog-Saluki-27B-1.0
ConwayResearch published the model Underdog-Saluki-27B-1.0 on Hugging Face.
 Video
Same Model, Different Speed: Why Your Inference Provider Matters — FriendliAI
Open-weight models are good enough now.

OrcaRouter Releases OrcaCyber Zero 1.5 Cybersecurity Model With 1M Context
OrcaRouter has released OrcaCyber Zero 1.5, a model for authorized vulnerability research.
Understanding Jev, the new model everyone is talking about
On September 15, the startup TypeSafe AI came out of stealth and released a new AI model.
mistralai/Voxtral-Mini-4B-Realtime-Arabic
mistralai published the model Voxtral-Mini-4B-Realtime-Arabic on Hugging Face.
[AINews] Reflection Beam - 501B-A23B American Open Model
It’s been over a year since Reflection launched with us with big goals on coding (and hinted about their RL approach):
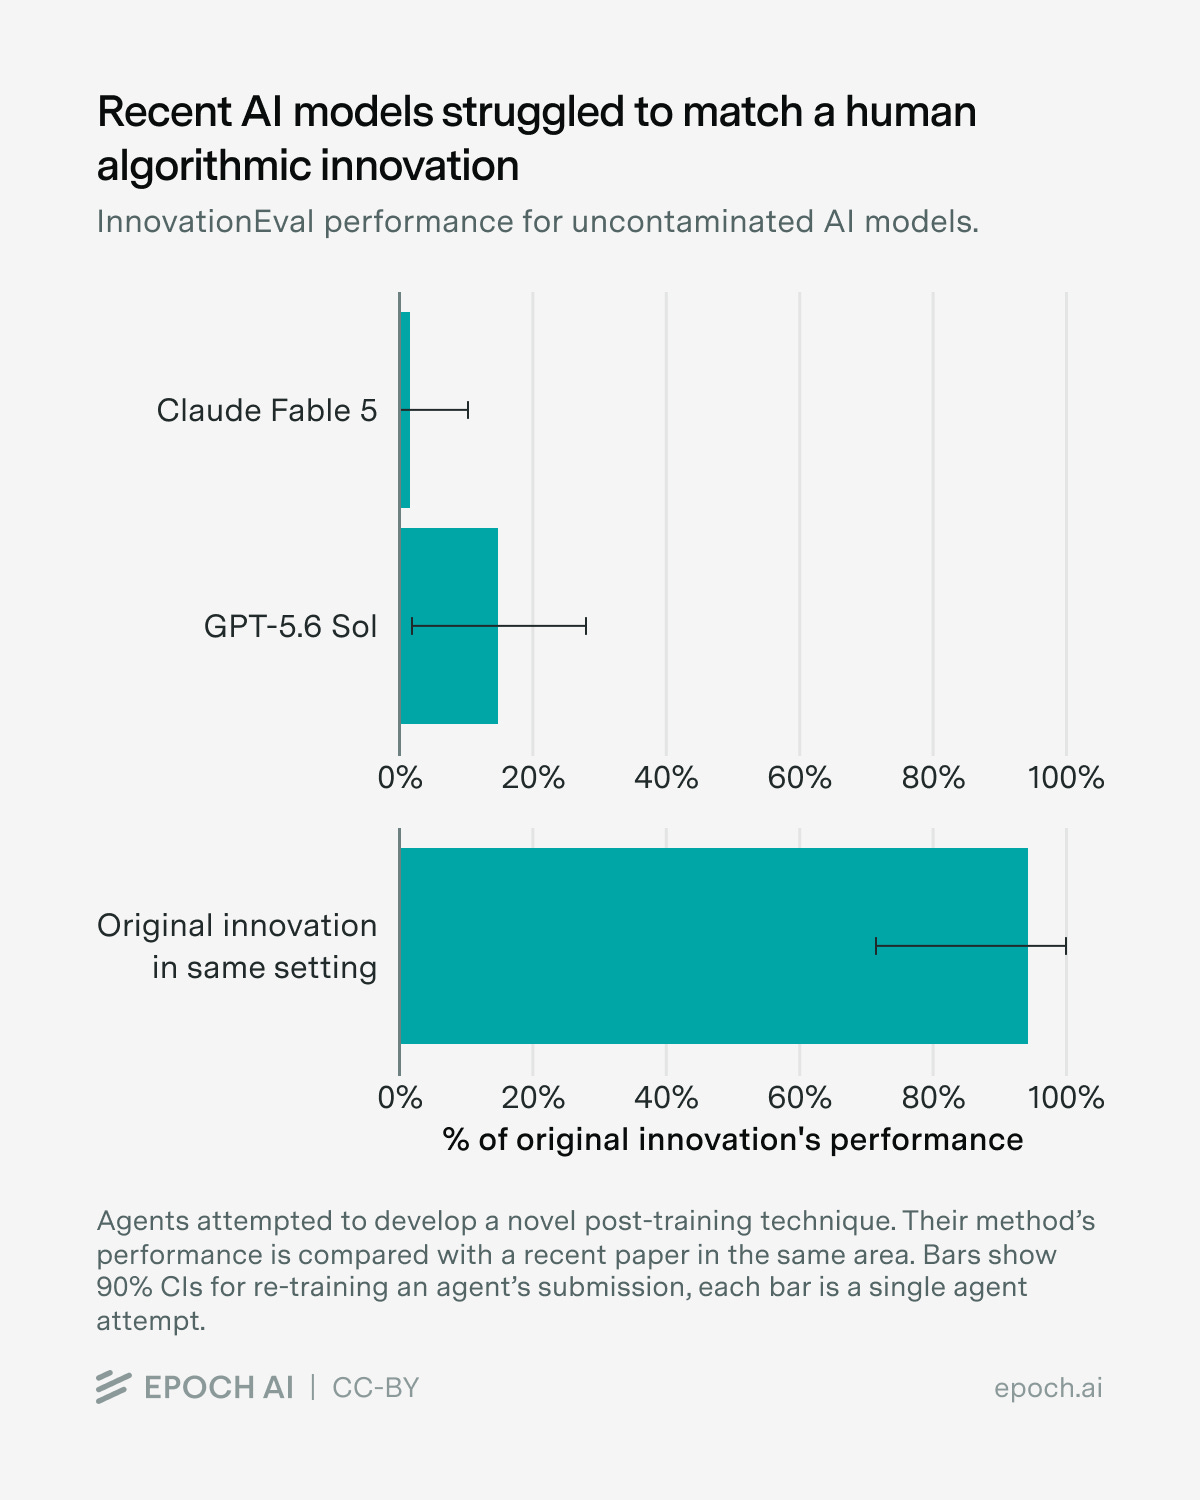
Can AI automate AI R&D yet?
Existing evidence shows that AI can perform software engineering tasks relevant to AI research, dataset creation, open-ended optimization of defined metrics (autoresearch), and more.
OpenPilot
Open-source desktop AI agent for any model you choose
Impactful scheduling for GPU clusters
On the AI Infrastructure team at Ai2, we’re responsible for providing the institute’s GPU compute capacity, specifically targeting large, distributed training workloads.
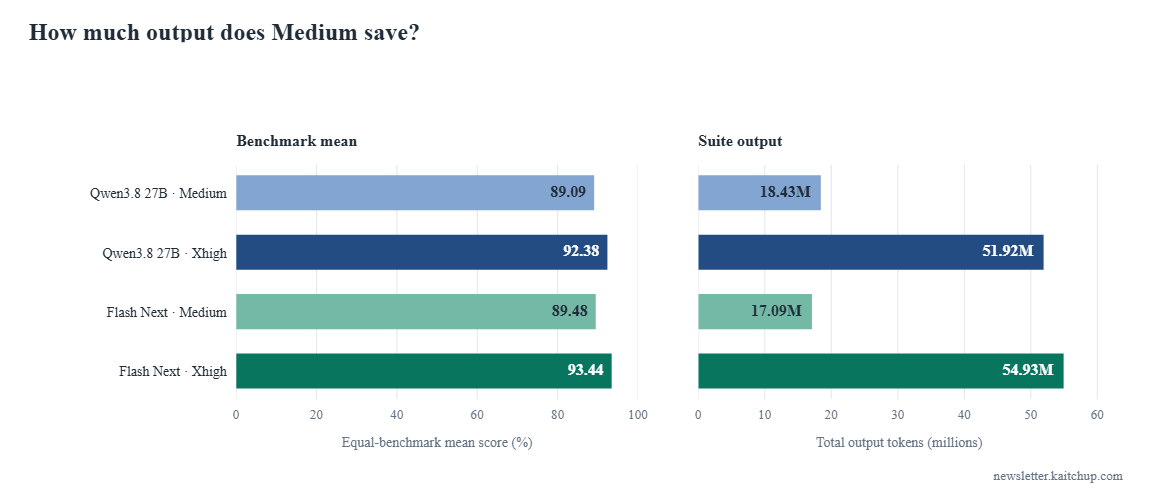
Qwen3.8 27B Xhigh or Flash Next Medium
In my Qwen3.8 27B reasoning benchmarks, Xhigh generally produced the strongest results, but it needed much longer responses than Medium.
llm-mistral 0.16
Adds support for reasoning models, such as the newly released Mistral Large 4.
Scale Bitwise-Deterministic Pretraining with NVIDIA Megatron Core
Bitwise determinism makes large-scale pretraining easier to debug, validate, and resume reproducibly.
CoreWeave Forge aims to speed up the AI improvement loop
The post CoreWeave Forge aims to speed up the AI improvement loop appeared first on SiliconANGLE.
Best practices for Amazon SageMaker HyperPod administration and governance
Amazon SageMaker HyperPod gives machine learning (ML) teams access to large pools of accelerated compute for training and fine-tuning models.
nvidia/agile_one_s_place_ssd_n17_24050
nvidia published the model agileonesplacessdn1724050 on Hugging Face.
ReviewBench: An open benchmark for AI code review
Agentic code review is becoming an essential piece of how development happens.
 Video
Agents That Own Their Inference — Du'an Lightfoot & Khaja Omer, Akamai Technologies
Speculative decoding drops a demo model from roughly 58 tokens per second to 16 instead of speeding it up.

AI agent teams waste massive tokens for barely measurable quality gains, research finds
Teams of AI agents barely outperform solo agents but cost up to 5.1x more, according to Vals AI.
 Video
From Zero to Leaderboard: Agent Evaluation — Wolfram Ravenwolf, Weights & Biases
An agent repairs a broken git repository and earns a perfect score, but the run stays out of the default leaderboard because it tested only one task.
 Video
Vector Isn't Enough: Hybrid Search & Retrieval — Jeff Vestal & James Williams, Elastic
Jeff Vestal and James Williams work backward from that agent behavior to the retrieval layer in Elasticsearch.
mistralai/LIDstral-Arabic
mistralai published the model LIDstral-Arabic on Hugging Face.
unsloth/embeddinggemma-2-GGUF
unsloth published the model embeddinggemma-2-GGUF on Hugging Face.
Nace AI Open-Sources Drex 1.5: A 9B Decision Model That Scores Options, Not Text
Nace.AI has open-sourced Drex 1.5, a 9B decision model for agents and backend workflows.
Multimodal open d1 decision models for the edge
Best decision model under 10B on the Decision Index 0.2.1: d1-3B scores 48.57, ahead of every 4B and 9B model and of Decider 35B-A3B (47.11).
LiquidAI/d1-omni-600M
LiquidAI published the model d1-omni-600M on Hugging Face.
perplexity-ai/pplx-decider-v1.1-27b
perplexity-ai published the model pplx-decider-v1.1-27b on Hugging Face.
The model that didn't exist, so you made it yourself
Last week, I wanted a small version of the prompt rewriter that ships with Qwen-Image 2.1.
One Model Family, Two Gold-Level Results: Fine-Tuning Nemotron for IOI and IMO
Starting from Nemotron 3, our teams used supervised fine-tuning (SFT), reinforcement learning (RL), and feedback-driven inference to create systems that reached gold-medal level at both IMO 2026 and IOI 2026.
Mistral Large 4
llm -m gpt-6.1-sol 'Generate an SVG of an armadillo in fishnet tights jaywalking on Mars'
EmbeddingGemma 2
My comment on EmbeddingGemma 2 — Hacker News.
ej
An 11MB local model for typed decisions in one pass
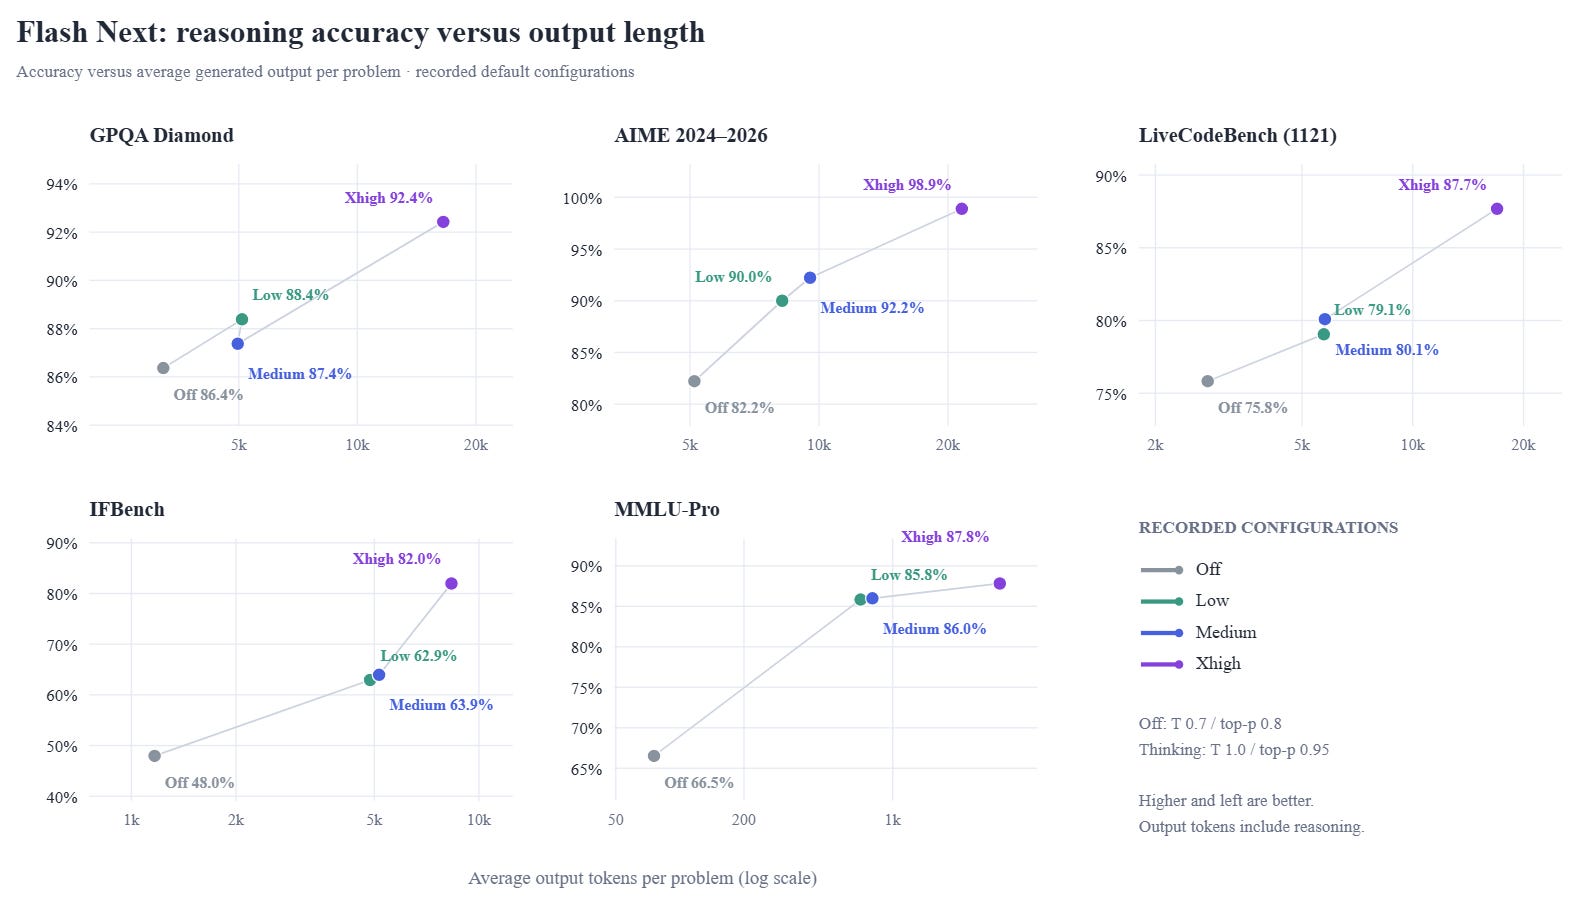
Qwen3.8 Flash Next Reasoning Modes: Off vs Low vs Medium vs Xhigh
Like Qwen3.8 27B, Qwen3.8 Flash Next has three reasoning efforts: low, medium, and xhigh.
CoreWeave targets AI inference bottlenecks with full-stack optimization
The post CoreWeave targets AI inference bottlenecks with full-stack optimization appeared first on SiliconANGLE.