Analysis
Opinion, explainers and guides from people worth reading.
 Video
Teaching Agents to Search with NVIDIA Data Designer — Dhruv Nathawani, NVIDIA
Dhruv Nathawani uses that funnel to explain how NVIDIA builds synthetic data that teaches a model to search, rather than answer from memory.
Why AlphaFold Didn't Solve Protein Folding — Pushmeet Kohli, Google DeepMind & Sal Candido, Biohub
From the Bitter Lesson of AI scaling to the unsolved mysteries of protein folding, Google DeepMind’s Pushmeet Kohli and Biohub’s Sal Candido are rethinking what it takes to build AI that truly understands biology.
ttok 1.0
I released ttok 0.4, ran uv tool upgrade ttok, piped a file into the new version... and realized that it was defaulting to the GPT-4 tokenizer when it should very clearly default to GPT-5/GPT-6 instead!
How Oracle turns days of work into minutes with ChatGPT and Codex
Across recruiting, engineering, and operations, Oracle turns specialist knowledge into fast, repeatable workflows with ChatGPT Work and Codex.

A/B Blind Taste Test - Krea2-Turbo vs. Qwen-Image 2.1 Turbo
Since Qwen 2.1 Turbo dropped suddenly right after my last taste test, figured might as well do one for it as well.

I tested different Qwen 3.8 27B quants
There is a lot of discussion which quant to use.
[P] Pecision models that score every allowed label from the logits: Jebadiah v2.1 (27B, 9B), open weights and self-run benchmark results [P]
I've been building open models that treat a decision as a closed-set scoring problem rather than text generation.
Byte Language Models: Scaling, Emergent Abstractions, and Information Allocation
The paper challenges the assumption that language models need explicit tokenizers to be efficient demonstrating that standard flat Transformers can process raw byte sequences and actually outperform traditional subword models as parameter sizes scale.
Text is so 2023
Hark (from Brett Adcock - Figure robots) launched which suggests tasks as one-tap action buttons.
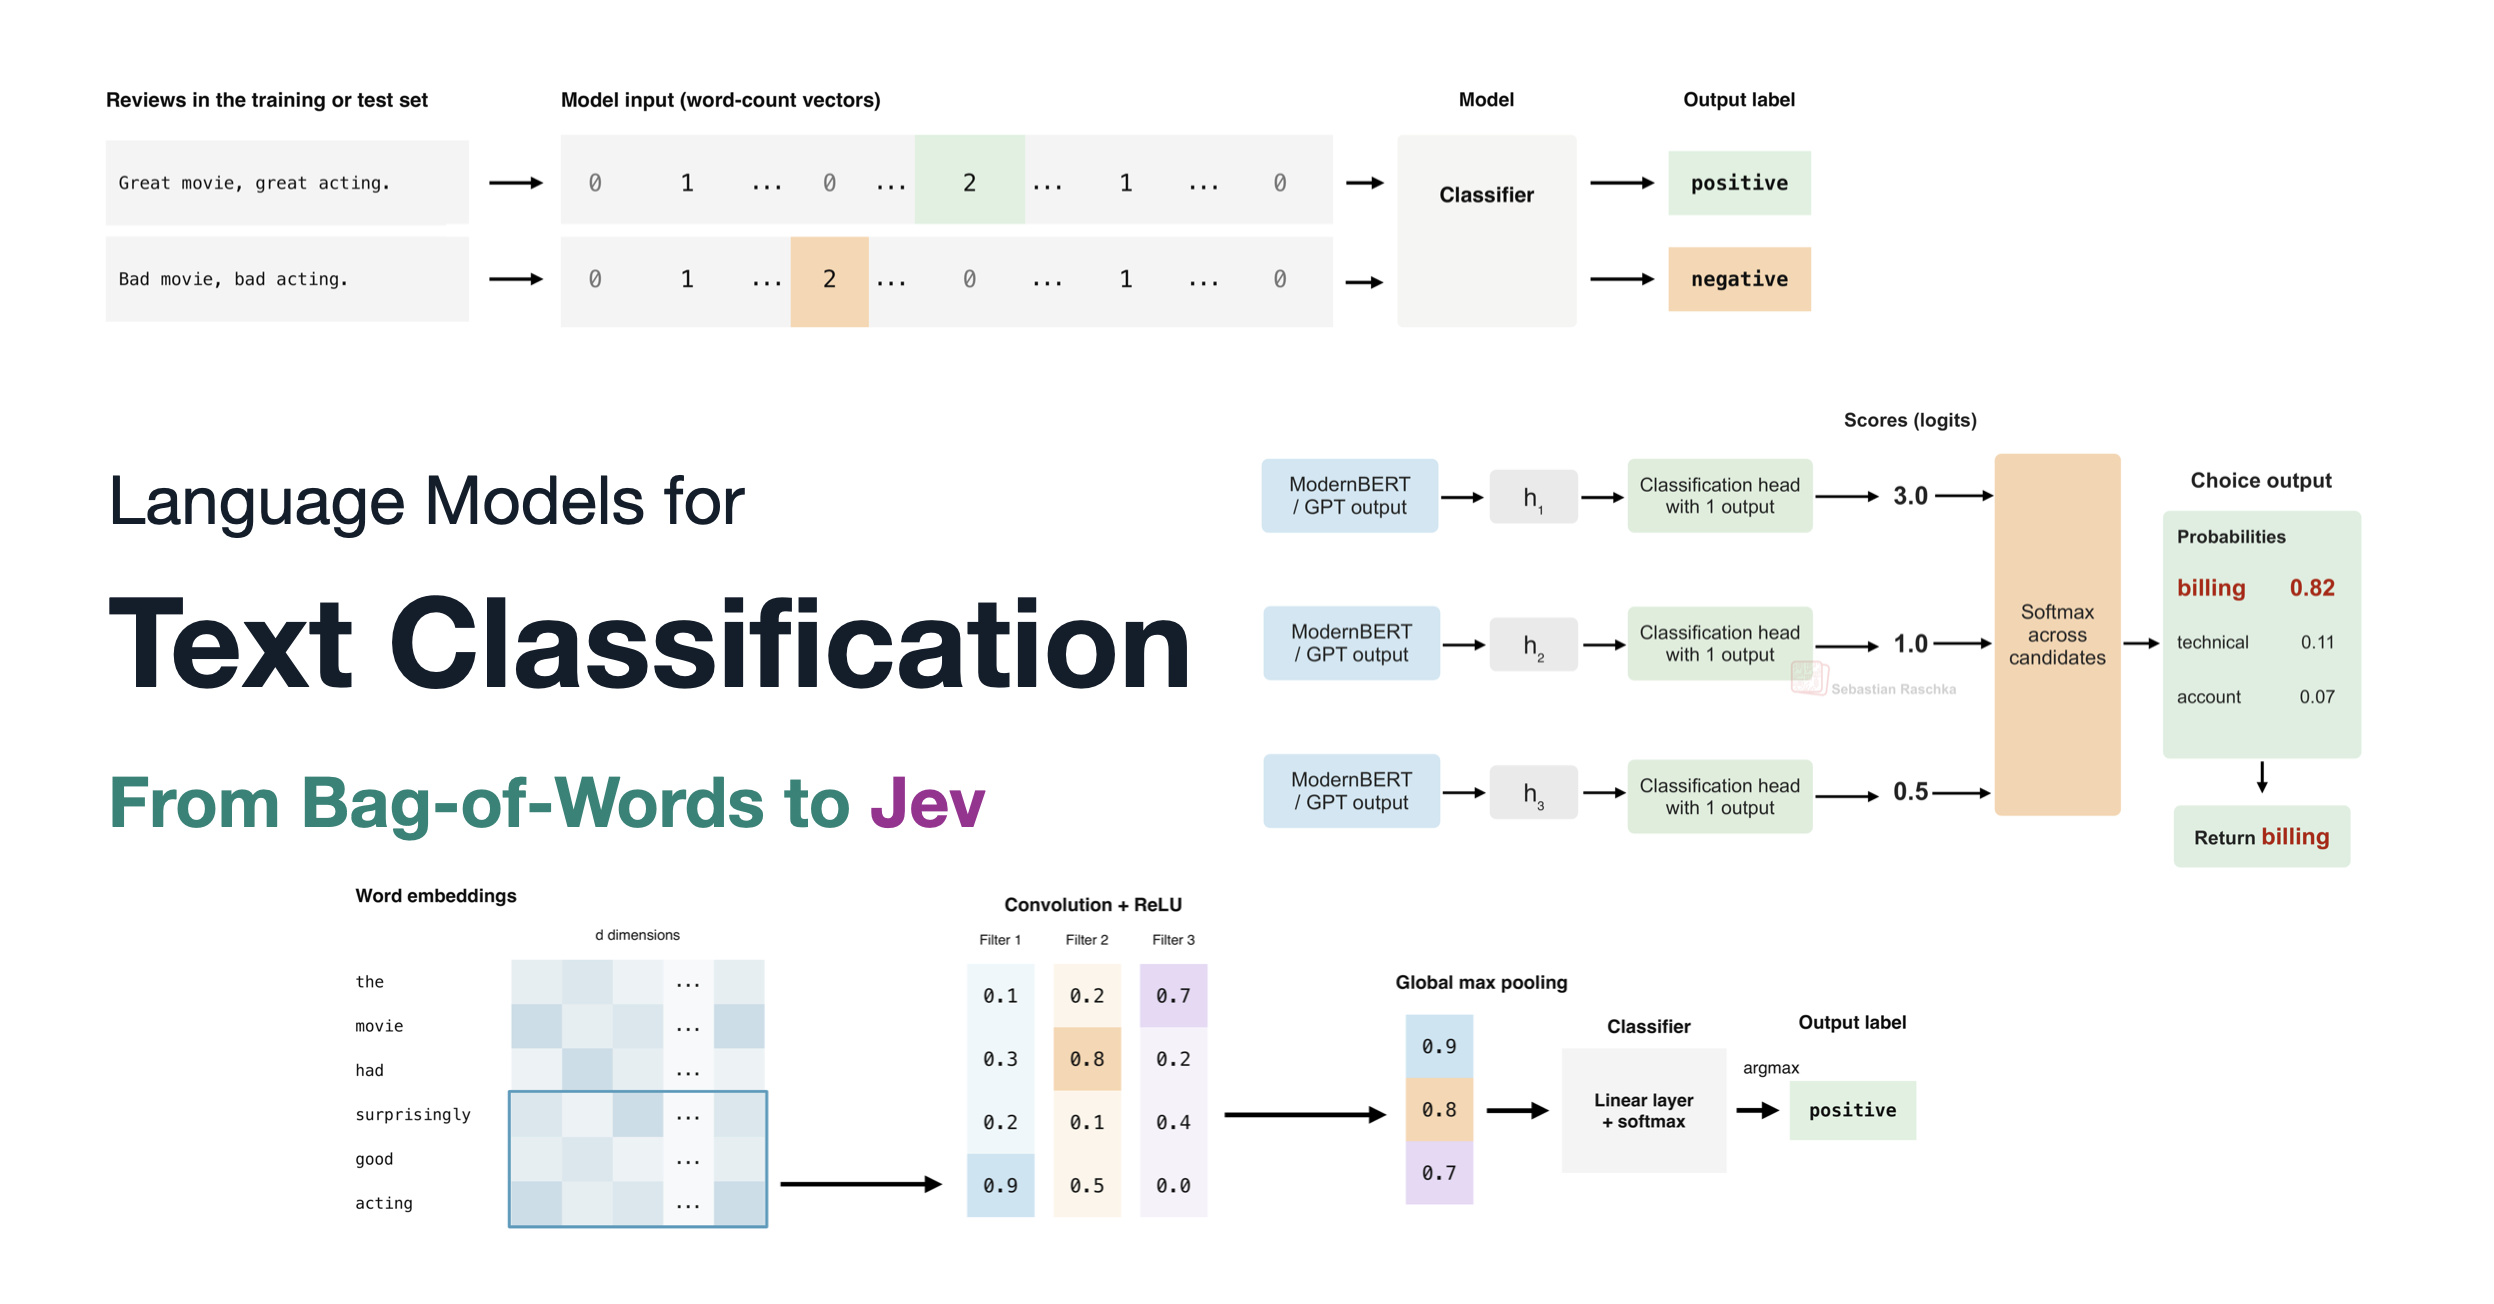
Language Models for Text Classification: From Bag-of-Words to Jev
The recently released Jev AI model has been quite a cultural phenomenon in technical communities in the past 2 weeks.

Agentic Coding with Qwen3.8 Flash Next GGUFs and Notes from COLM
Updates on Qwen3.8 Flash Next GGUF evaluations for agentic coding
What is Decision 3.0? vLLM Semantic Router’s New Open Decision Models
The vLLM Semantic Router team has released Decision 3.0, a family of multimodal decision models.
MCP for agent-to-agent comms may be the riskiest protocol you've never heard of
The adoption of AI agents in millions of organizations is creating new opportunities for attackers to make them take malicious actions, such as exfiltrating database contents and sensitive business and personal information.
LWiAI Podcast #258 - Opus 5.5, Sol and Luna, Muse, DeepSeek-V4.1-Flash, Xi
Our 258th episode with a summary and discussion of last week’s big AI news!
 Video
OpenAI Security: Controlling Models is Now ‘Hell’
A cracked cipher, an OpenAI security warning, Gemini 4 Argon, RSI paper (co-authored by a who’s who of AI), Lab White House commitments, new hacks emerging, ‘deep personas’, biology Kasparov competitions, and so much more, ending with an epic Opus outro.
Show HN: Made an open-source Lego AI generator
So, the idea I had was: if I manage for maybe ChatGPT or Claude to generate high-quality LDraw source files... then, they would actually be generating high-quality LEGO CAD models, right?

Limits of Confidence in Diffusion
Discrete diffusion, including remasking and uniform-state samplers, generate a sequence by writing multiple token positions per step, drawing each from a per-position distribution and choosing which positions to write from those same distributions.
Childhood and Education #21: Grades and Standards
First you get to college via the wrong metrics, as previously discussed in #12.
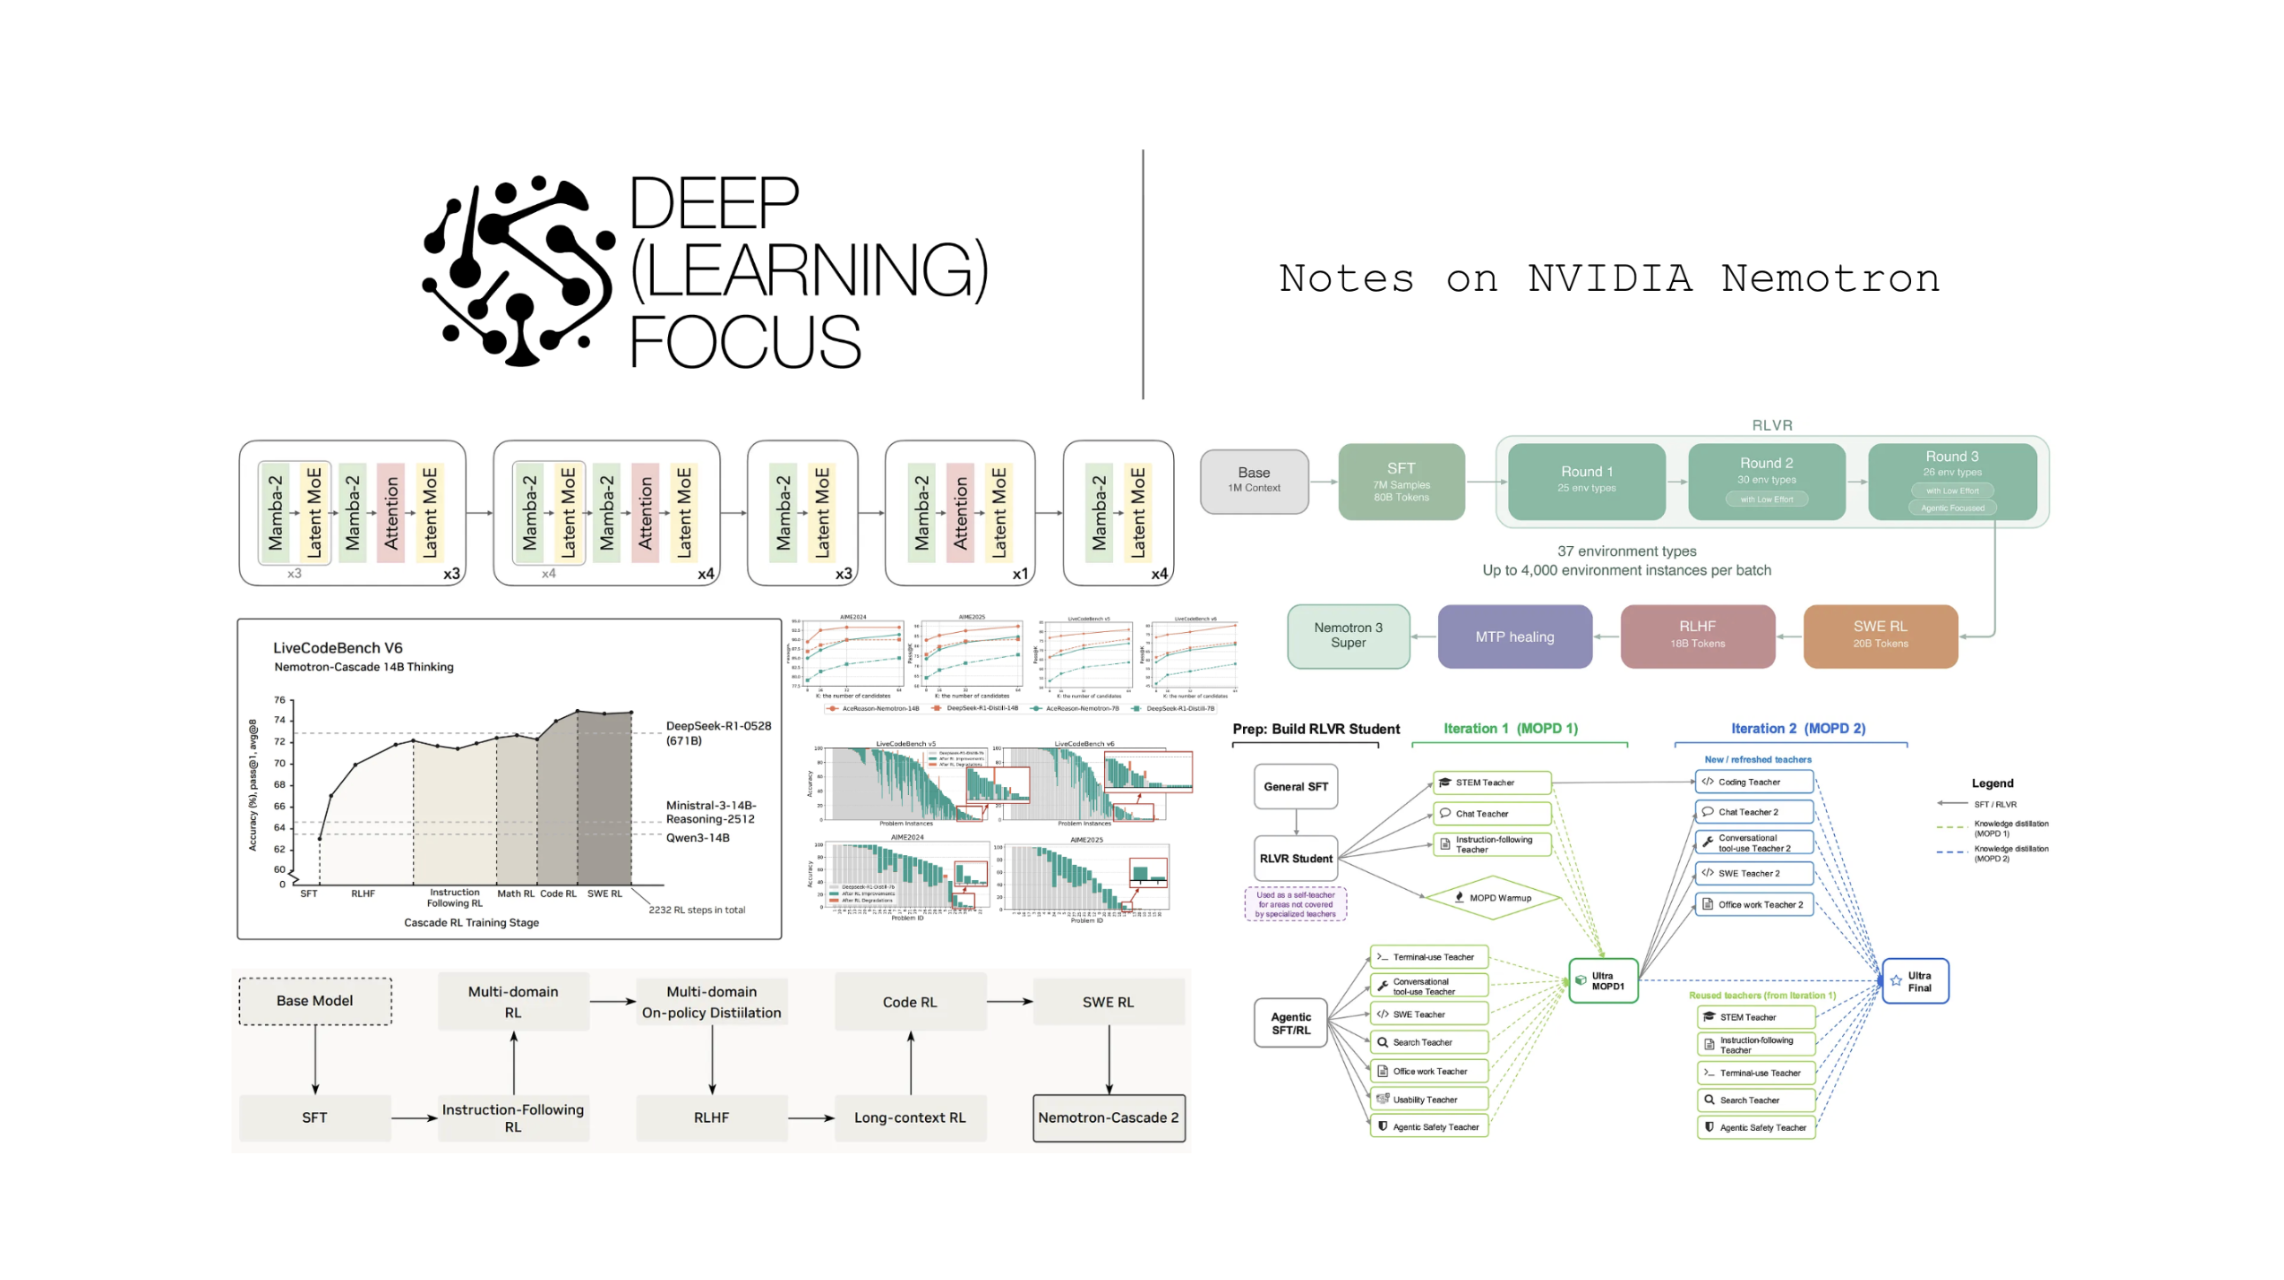
Notes on NVIDIA Nemotron
Today, many key details of frontier large language models (LLMs) remain proprietary, but open-weights model families—such as DeepSeek, Kimi, and MiMo—continue to provide a valuable window into the development process for modern LLMs. Among these resources, the NVIDIA Nemotron model series is especially useful due to its transparency.

ArXiv caps submissions at two per month as AI paper flood overwhelms the preprint server
Starting October 2026, arXiv will cap submissions at two per person per month.
Ollama now supports Jev-style decision models
Ollama now supports decision models, based on TypeSafe's Jev API for fast, typed decisions.
Show HN: TerrainSR – fast, realistic heightmap upscaling model
I wanted to have a 1:1 scale model of Europe, but my problem was that 100m data was too low-res while 10m LIDAR data was patchy, took hundreds of GBs to store and was full of manmade objects like mines, buildings and so on.
 Video
How a Voice Agent Learns the Rhythm of Conversation — Shawn Wen
Tsung-Hsien (Shawn) Wen, CTO of PolyAI, tells Tim Scarfe why voice agents are harder than text agents.
Si Sheppard – How did a few hundred Spanish soldiers topple two empires?
New episode with military historian Si Sheppard.
 Video
DeepSeek-V4.1 Flash: The Most Insane Optimization So Far
DeepSeek-V4.1-Flash is probably the craziest architecture revamp to date.
AI for everyone in every language
We’re moving beyond traditional text translation to build models that understand the world’s rich, living languages exactly as they are expressed.
Qwen 3.8 27B Q5 vs Qwen 3.8 Next Q3_S for document analysis
So far I've been using Qwen 3.8 27B Q5 with a 150K context window, but I'm wondering whether I should switch to Qwen 3.8 Next Q3S, since it has much more knowledge and could extract data much better than the 27B.
Benefits of using bigger models than Qwen 3.8 flash next?
Qwen 3.8 27b was the first model I tried on Ninfer at NVFP4 and then shifted to Flash next after seeing issues with 27b such as not willing to yield to instructions set in AGENTS.md or agent skills.
Engineer / developer observations of Gemma4-31B, Qwen3.8-27B, and 6.1-Sol for software engineering work
Models: Gemma4-31B vs Qwen3.8-27B at the same quantization (an Unsloth flavor of Q4).
Is anyone running Qwen3.8 Flash Next with a 1M context?
So, while doing a search to read the model card again, and because I didn't memorize the huggingface URL, I saw an AI "answer" at the top of the search, stating that while it natively supports a ~244k context, it could go to 1M using YaRN.
Running Next Flash IQ3_XXS at ~70 tok/s with 100k context or 2 instances of Qwen 3.6 35B A3B IQ4 at ~145 tok/s with 256k all on $500 of ex mining BC-250 boards
This will be my third update on the bc-250 cluster and for my first forray into local ai I have been having a blast.
OMG! If you have a Mac with 64GB, try Qwen3.8-Flash-Next-oQ4e-mtp with oMLX!
I was able to run Qwen3.8-Flash-Next-oQ4e-mtp on M3Max 64GB with oMLX!

I trained a 414k-parameter transformer to fly a boids flock, then tested whether the rules a probe can read are the ones it uses [P]
I wrote a small boid simulator (12 birds), recorded it flying, and trained a transformer to predict each bird's next move without it knowing about any boid rules.
I trained a 102M recursive BitNet-v2 model from scratch: 64K context, trained on less than 5B tokens
Hiya, I’m releasing Recursive BitNet N-Gram 102M, a small experiment combining ternary weights, shared transformer layers, and hashed n-gram embeddings, trained with a whooping budget of 100€
[AINews] TypeSafe/Jev at >$100M ARR, $7.5B valuation 3 weeks after launch
As you can see in the AINews X recap section below, everyone on earth has cloned the Jev API, but only one company can ever create the category.
Qwen3.8 27B addition in words
Research: Qwen3.8 27B addition in words

Krea2 Turbo Distill 2 step LoRA - FINAL checkpoint released (chk51195)
Krea 2 Turbo — 2-Step Distillation LoRA (FINAL Version)
I Built a O(NlogN) attention system that retains 97% accuracy over long context (MQAR)[P]
ALHR- Adaptive learnable Hierarchical Routing is a static binary tree based system that uses learnable functions to REDUCE the amount of keys used.
Reverse Engineering w/ Local?
Can a local model like Qwen 3.8 27B reverse engineer games and programs?
Building prompts with LLMs
I’ve been into AI image and video generation for a while, and I’ve been a bit obsessed with H3 for the past two months.
Heretic or Abliterated?
Looking for recommendations for local LLM to convert an image into a usable prompt for Krea2 with max accuracy.
Open-source Mac app that runs EmbeddingGemma 2 locally to search your files by what’s in them
DigUp is a free Mac app that runs Google DeepMind’s new EmbeddingGemma 2 locally over your own files.
Reminder: try probabilistic MTP if you missed it. Decode +14% on prose
Optimal draft-n-max / draft-p-min seem to be in line with greedy sampling.
A model guide for the GPT-6 family
Learn how startups can choose GPT-6 models, tune reasoning effort, improve prompts and skills, coordinate tools, and prepare workflows for production.
Help With Choosing Hardware [P]
I am going to fine-tune a satire model, with the base model being Qwen3.5-14B-Base.
Qwen3.8 Flash Next, Swift 1.5, and MiMo V2.6: What I’m Testing Now
The Kaitchup – AI on a Budget is a reader-supported publication.
I built a browser tool to visualize how a small LLM picks its next word and see what it's attending to [P]
You give it a prompt, it generates one token at a time, and for each step you get the next-token candidates with probabilities, plus the attention from the current token back to the earlier ones drawn as links with the weights labeled.
Anti-Patterns in Software Blogging
Some excellent writing advice from Michael Lynch.