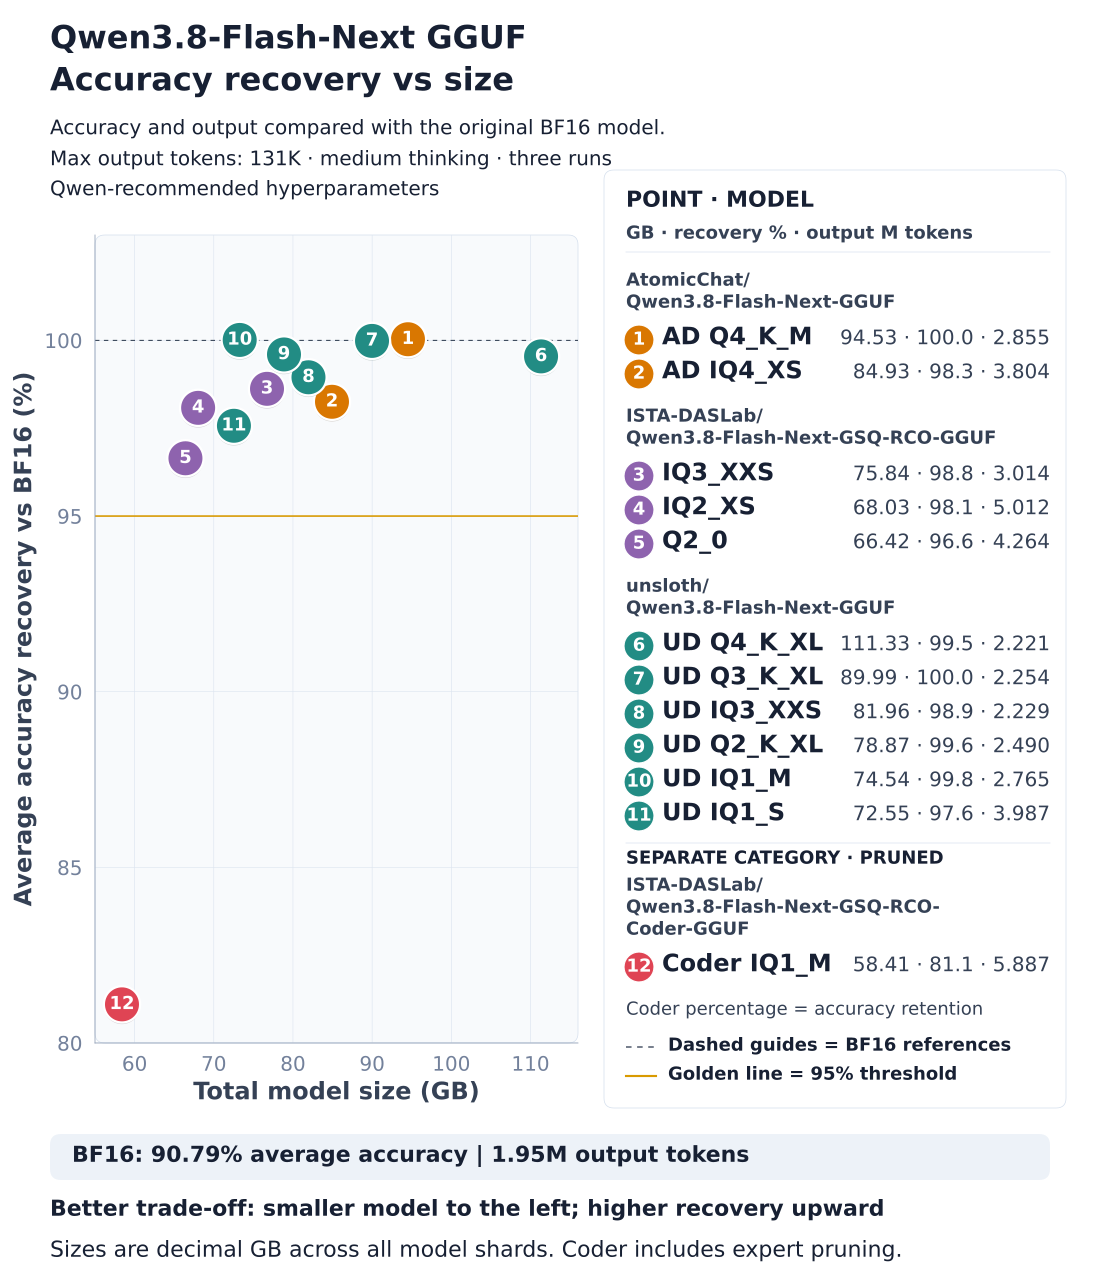
I tested different Qwen 3.8 27B quants
There is a lot of discussion which quant to use.

Proof1 community thread
Key points
- Especially a lot of post how much speed you gain with FP4, but not much about quality.
- Qwen3.8-27B-UD-Q6KL.gguf best in accuracy and slowest
- Swift-Qwen3.8-27B-Q6K.gguf second best in accuracy and speed
- I was surprised that the MXFP4 quant was the best in math
Sources (1)
- [1]I tested different Qwen 3.8 27B quantsr/LocalLLaMA (top, daily) · Oct 11, 08:24 PM
There is a lot of discussion which quant to use.
Especially a lot of post how much speed you gain with FP4, but not much about quality.
Extractive summary: sentences quoted from the sources.
Before this
- Oct 11, 2026UPDATE: Qwen 3.8 27B 140 tok/s on single RTX 3090 Megakernel: KL divergence 0.0009 vs llama.cpp
- Oct 11, 2026Now you can grow Bonsai on your potato
- Oct 10, 2026Nace AI Open-Sources Drex 1.5: A 9B Decision Model That Scores Options, Not Text
- Oct 9, 2026Qwen/Qwen-Image-2.1-Turbo
- Oct 8, 2026ConwayResearch/Underdog-Saluki-27B-1.0
- Oct 7, 2026unslothai/unsloth v0.1.904-beta: Train your own Decision model