Explore
Everything AION read, in seven sections. Pick one, a topic or a time window.
 Paper
Sharing AI progress in mathematics
OpenAI publishes new results on open problems in mathematics from an internal frontier model and shares Lean proof formalizations and research details on GitHub.
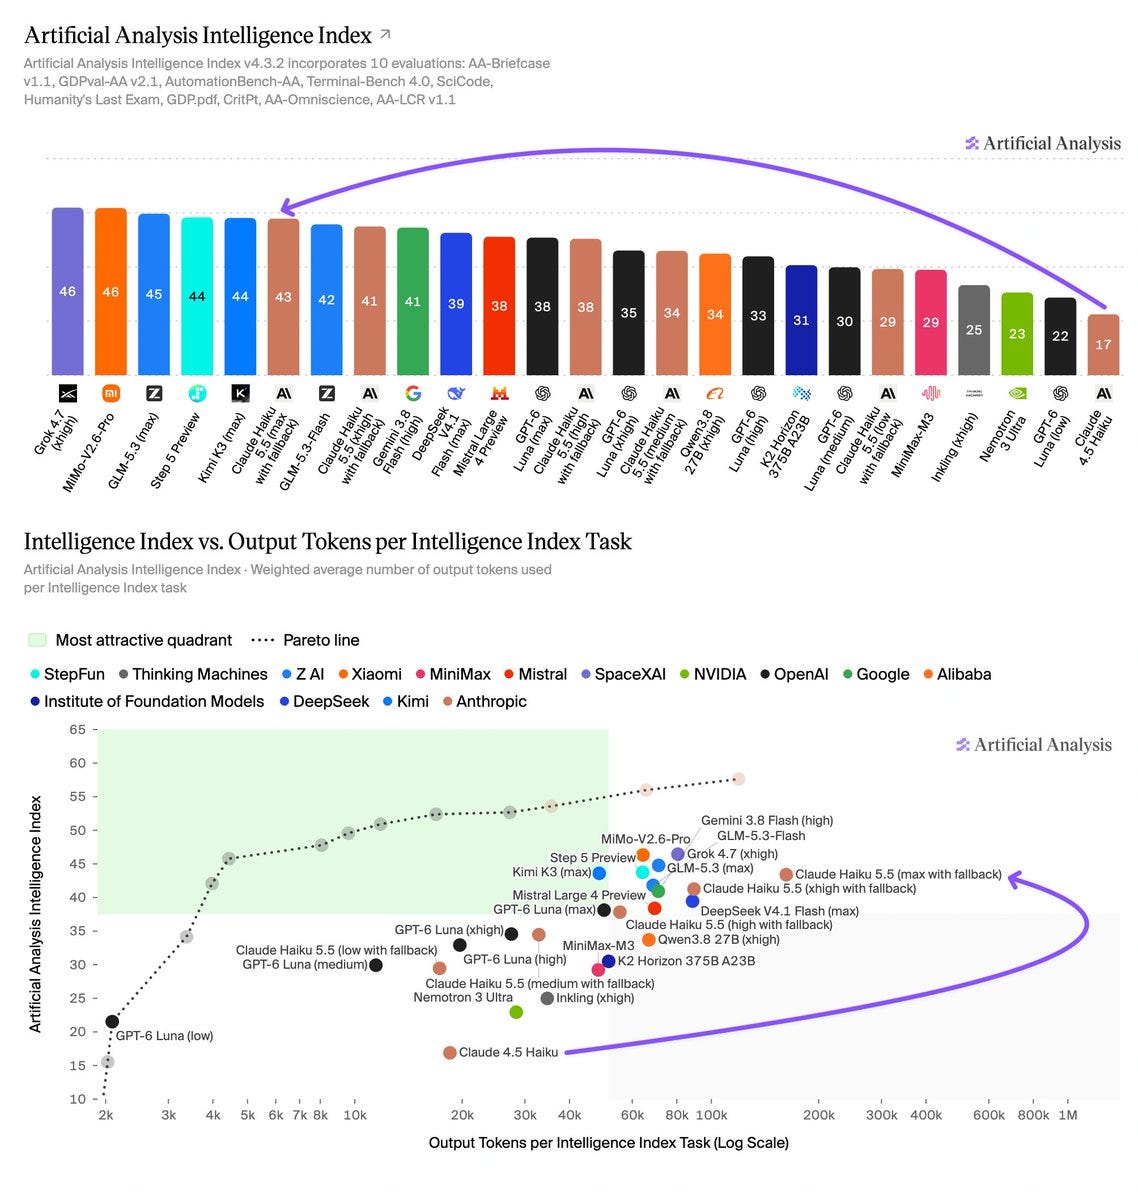
[AINews] Claude Haiku 5.5 — better than GPT-6 Luna at the same pricing
It’s been about a year since Anthropic shipped Haiku 4.5, and with successive launches of Sonnet and Opus and Fable up to 5.5 it was seeming a little forgotten, especially as OpenAI launched Luna 6 alongside Astra and Sol 6.
ConwayResearch/Underdog-Saluki-27B-1.0
ConwayResearch published the model Underdog-Saluki-27B-1.0 on Hugging Face.

Introducing Clef-omni with full multimodality, plus a faster Clef and a cheaper Clef-flash
Today, we’re releasing Clef-omni, which takes in audio and video input alongside text and image.
mistralai/LIDstral-Arabic
mistralai published the model LIDstral-Arabic on Hugging Face.
[AINews] Reflection Beam - 501B-A23B American Open Model
It’s been over a year since Reflection launched with us with big goals on coding (and hinted about their RL approach):
Memento 3: Model-Based Recursive Self-Improvement through Reflective Rulebooks
We introduce Memento 3, building on the Memento series to enable frozen LLM agents to continually learn explicit world models through external memory.
 Paper
Beyond Imitation: A Framework and Benchmark for LLM-Assisted Peer Review
Here, we introduce a verification-centric perspective on LLM-assisted peer review, emphasizing error detection as a critical and resource-intensive task.

OrcaRouter Releases OrcaCyber Zero 1.5 Cybersecurity Model With 1M Context
OrcaRouter has released OrcaCyber Zero 1.5, a model for authorized vulnerability research.
Expanding the Cyber Verification Program
We’re launching a new, expanded version of our Cyber Verification Program (CVP), which makes advanced cyber capabilities and reduced blocking classifiers available to qualifying security professionals.
langchain-ai/langchain langchain-openai==1.7.0
chore(deps): bump langgraph-sdk from 0.4.4 to 0.4.6 in /libs/partners/openai (#41096)
 Video
Teaching Agents to Search with NVIDIA Data Designer — Dhruv Nathawani, NVIDIA
Dhruv Nathawani uses that funnel to explain how NVIDIA builds synthetic data that teaches a model to search, rather than answer from memory.
 Video
Microsoft Joins the Local AI Push
Microsoft is clearly going all in on local AI running on your machine and working with cloud models only when it needs to use them.
Introducing GLM 5.3 on Amazon Bedrock
GLM 5.3 from Z.ai (Zhipu AI) is now available on Amazon Bedrock.
huggingface/transformers v5.19.0: Release v5.19.0
EmbeddingGemma 2 is a multimodal embedding model from Google built on the Gemma 4 architecture.
 Paper
RISED: Rubrics for Agentic Multi-Environment Selection and Self-Distillation
RISED: Rubrics for Agentic Multi-Environment Selection and Self-Distillation
Introducing Falcon ASR
We’re introducing Falcon-ASR, our 1.6 billion parameter speech recognition model for Arabic, with a particular focus on the Emirati dialect.
Text is so 2023
Hark (from Brett Adcock - Figure robots) launched which suggests tasks as one-tap action buttons.
unslothai/unsloth v0.1.905-beta: Sandboxing is here!
We're introducing Windows, Mac and Linux sandboxing in Unsloth!
Claude-shaped science
Features on AI-assisted discoveries, practical workflows, and field notes across the sciences.
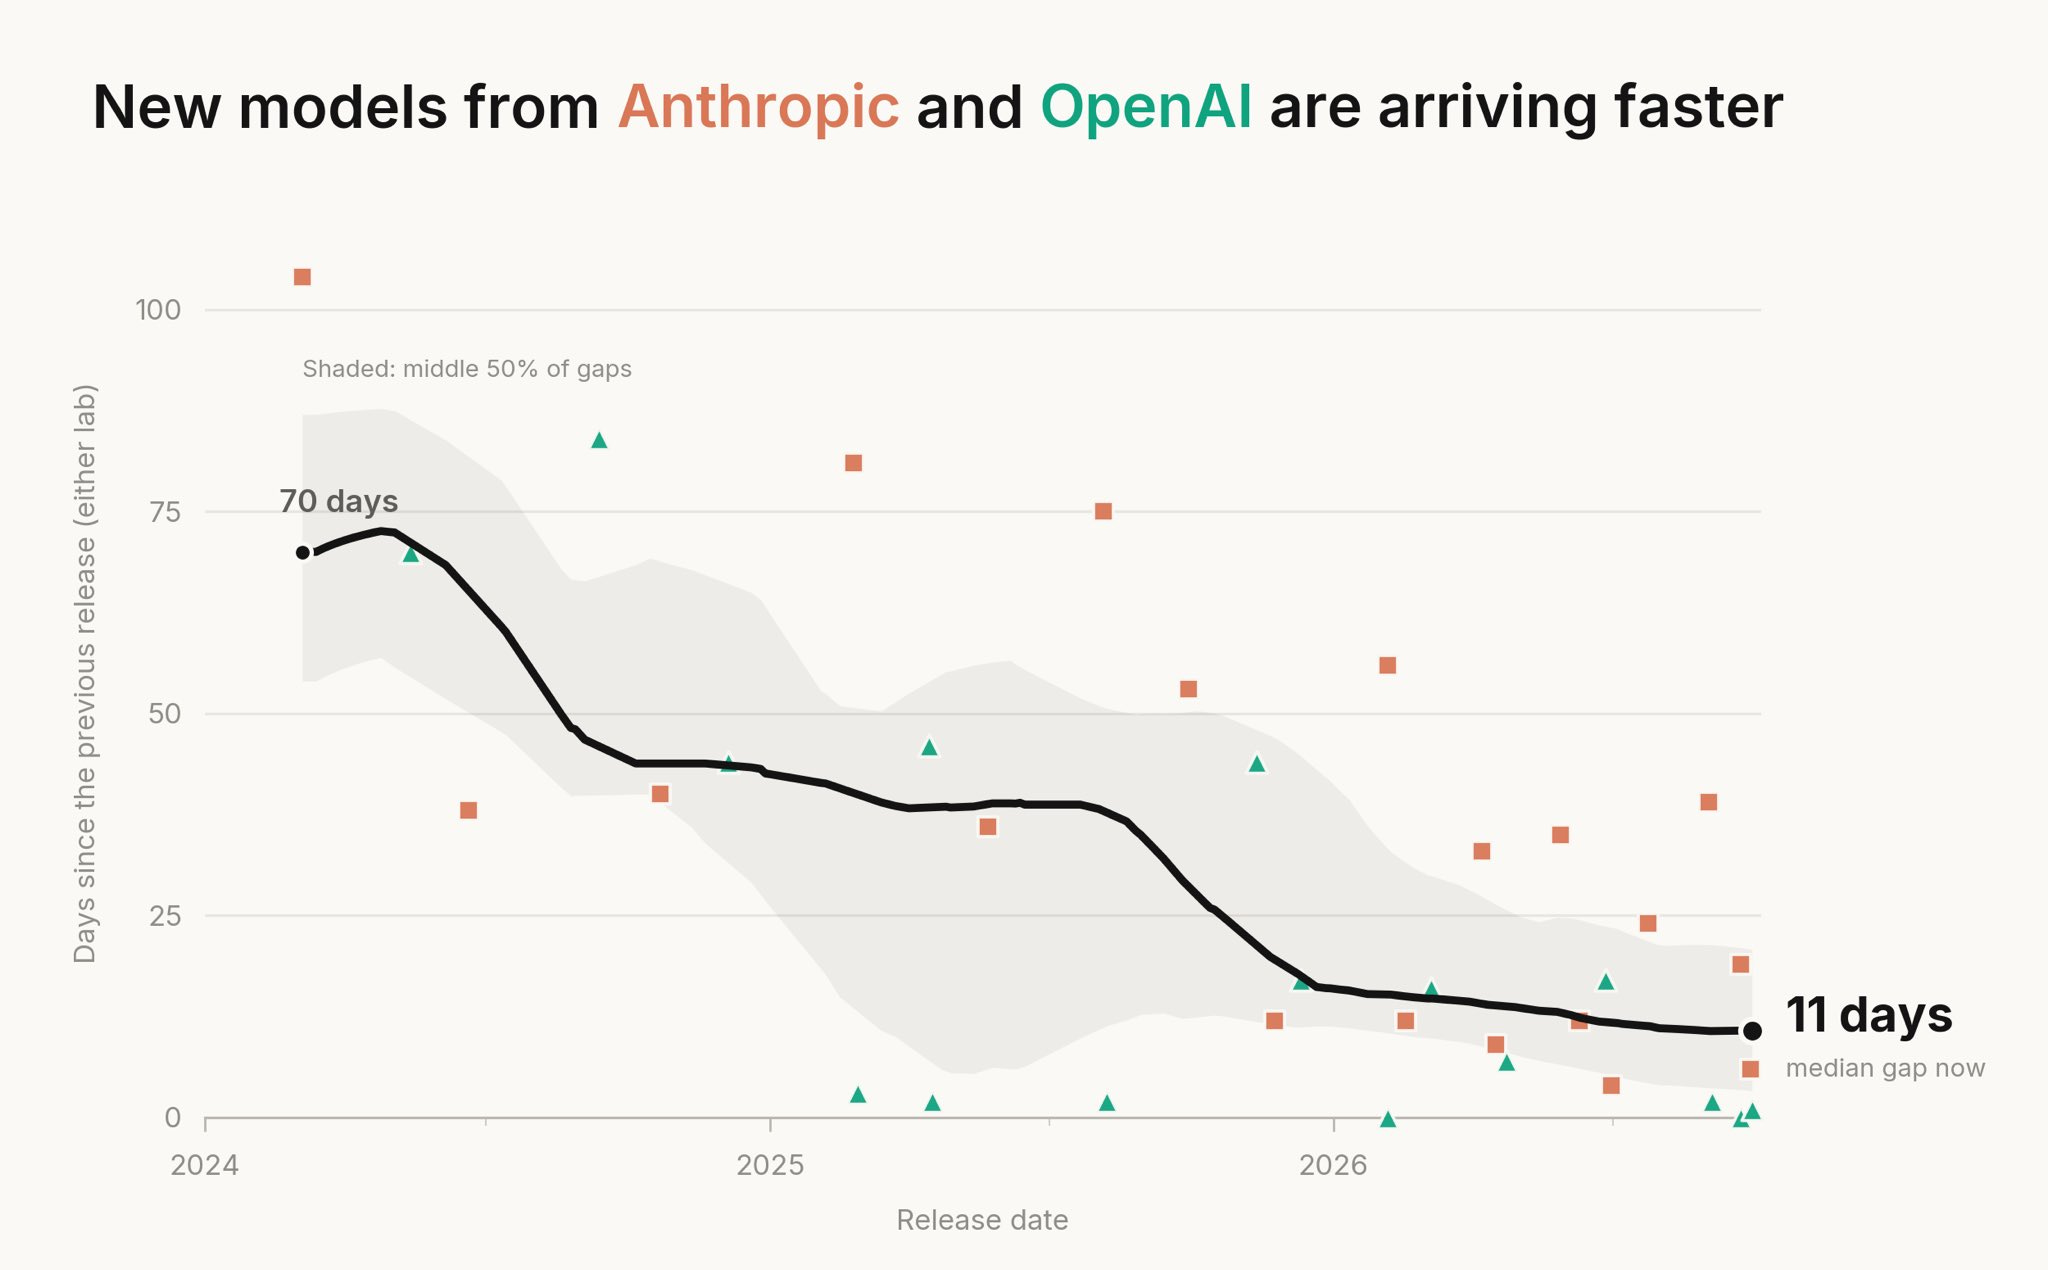
Last Week in AI #345 - 5 new models, 9 misalignment incidents, some Dots
Anthropic and OpenAI race to release smarter and cheaper models
huggingface/trl v1.14.2
Patch release fixing two cases of silently wrong training and three crashes.
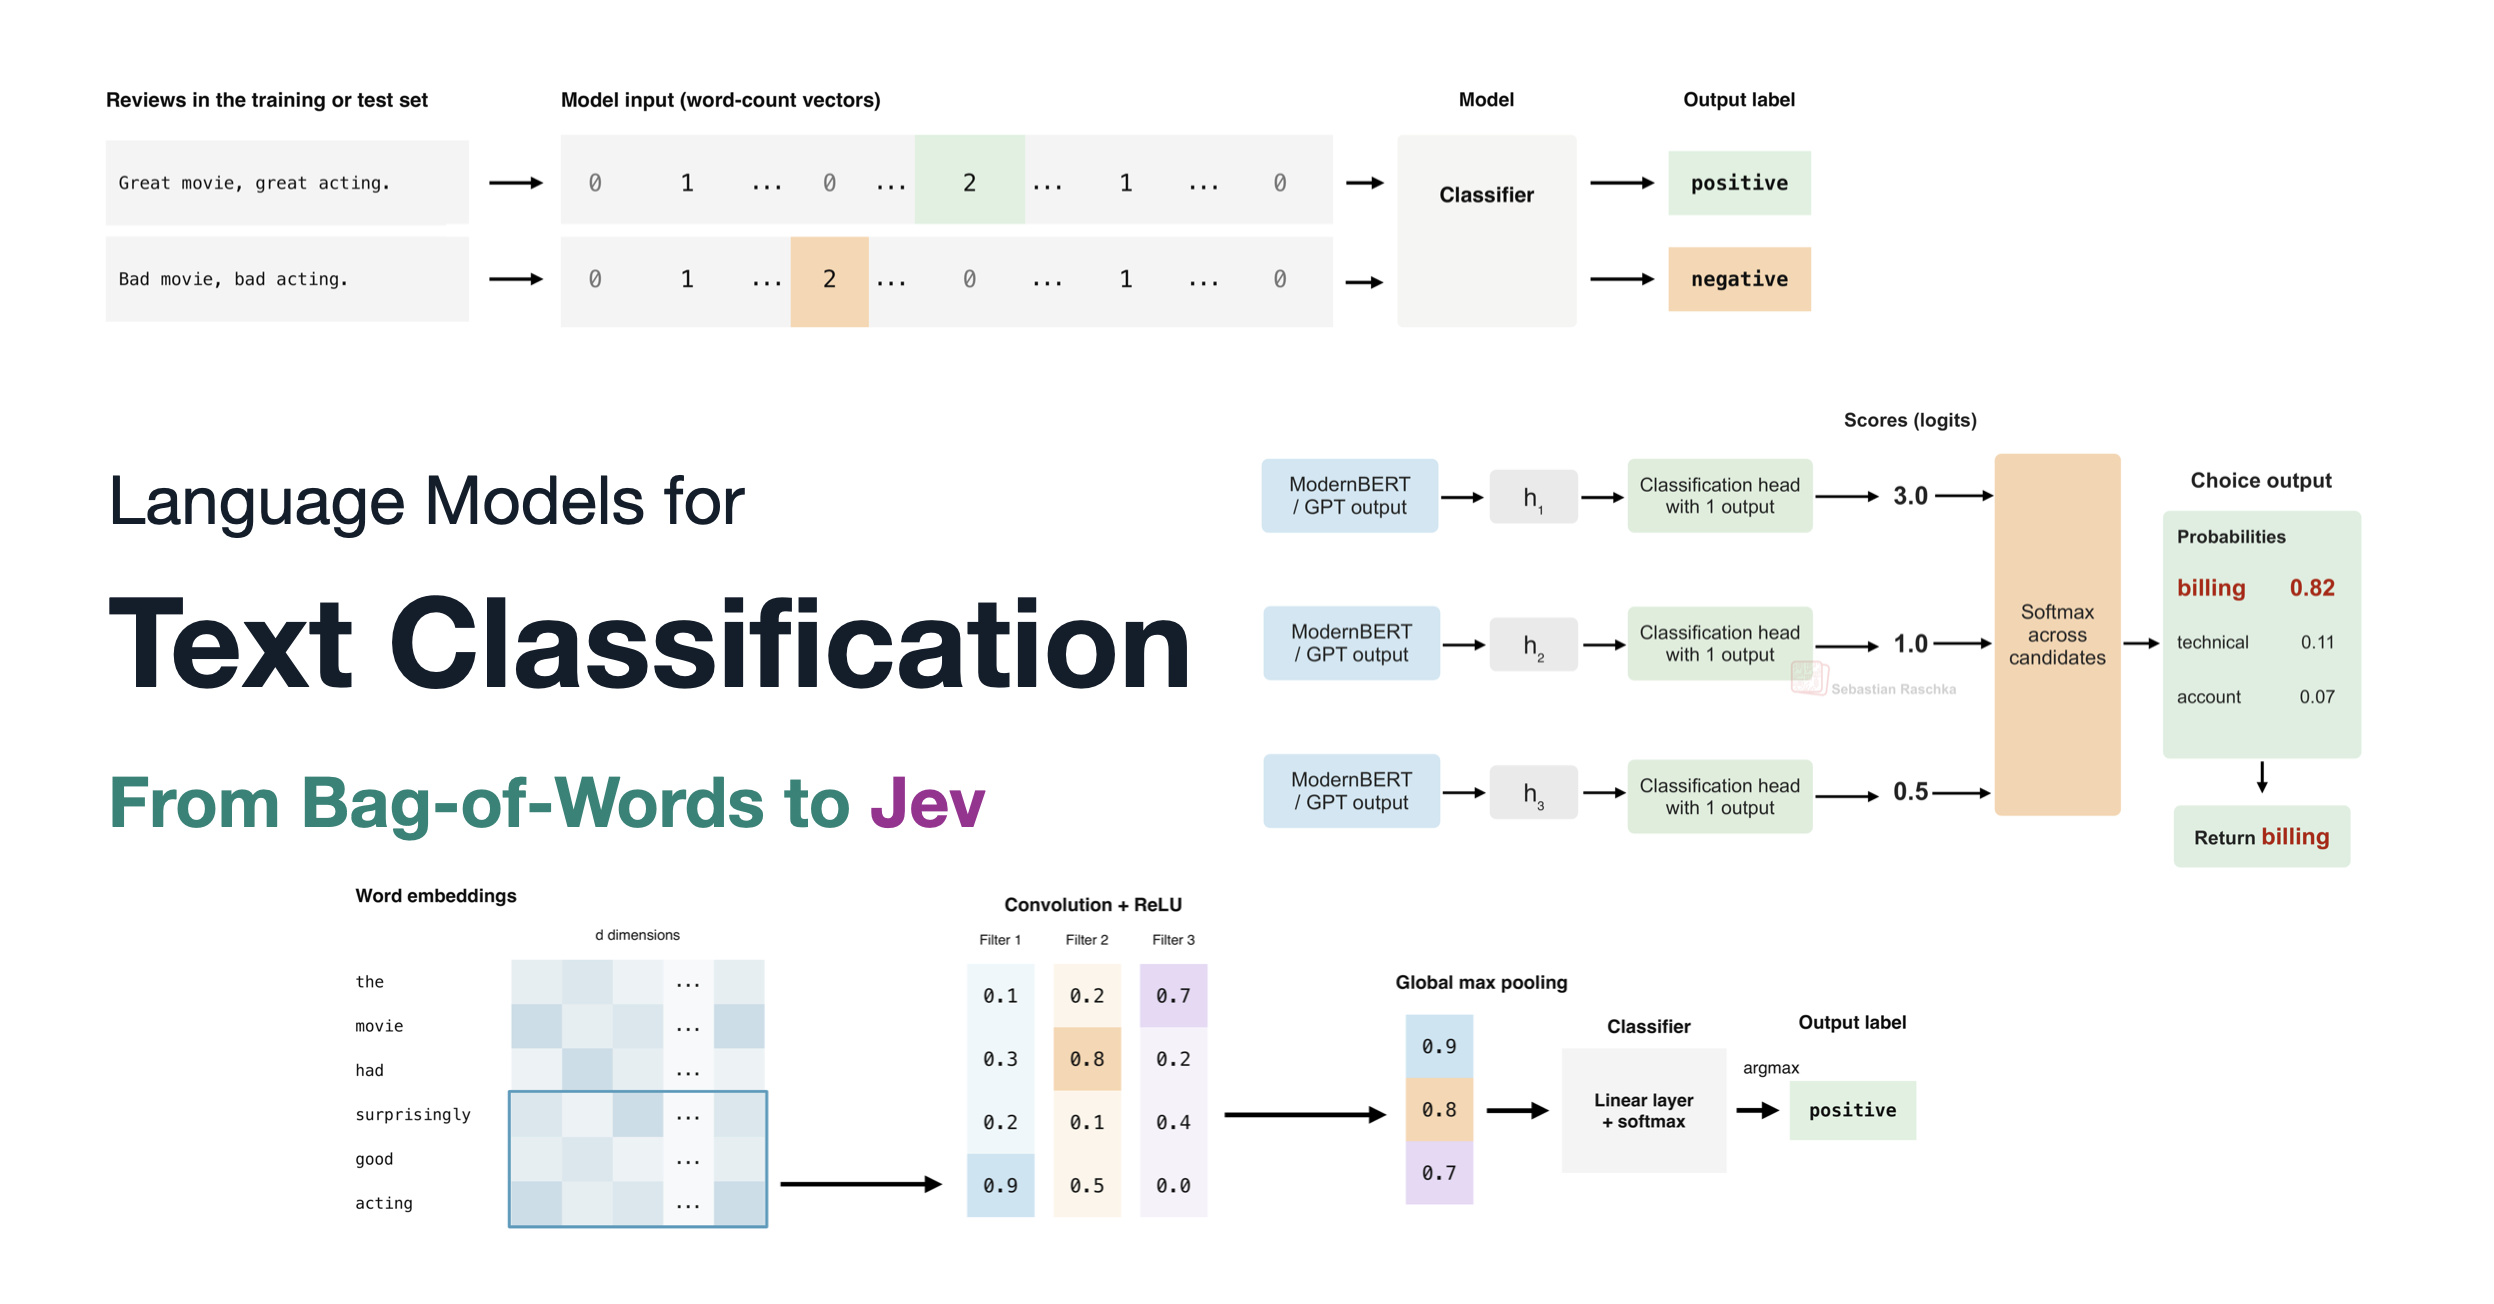
Language Models for Text Classification: From Bag-of-Words to Jev
The recently released Jev AI model has been quite a cultural phenomenon in technical communities in the past 2 weeks.
microsoft/AesCode-32B
microsoft published the model AesCode-32B on Hugging Face.
ibm-granite/ensemble-forecasting-with-ibm-granite-time-series
ibm-granite published the model ensemble-forecasting-with-ibm-granite-time-series on Hugging Face.
 Video
OpenAI Security: Controlling Models is Now ‘Hell’
A cracked cipher, an OpenAI security warning, Gemini 4 Argon, RSI paper (co-authored by a who’s who of AI), Lab White House commitments, new hacks emerging, ‘deep personas’, biology Kasparov competitions, and so much more, ending with an epic Opus outro.
Show HN: Made an open-source Lego AI generator
So, the idea I had was: if I manage for maybe ChatGPT or Claude to generate high-quality LDraw source files... then, they would actually be generating high-quality LEGO CAD models, right?
sgl-project/sglang v0.5.21
| Model | Type | Cookbook |
huggingface/peft v0.21.2
This is a PEFT release fixes an issue that prevented encoder-decoder models to work when using Transformers ≥ 5.18.0.
axolotl-ai-cloud/axolotl v0.20.0
We have added a bunch of features including GGUF export, Ringmaster context parallelism, native NVFP4 LoRA, and expert parallelism without DeepEP.
ollama/ollama v0.35.0
Decision models return choices, probabilities, and scores instead of text.
Gemini 3.8 text-to-speech says hello
Today, we’re introducing two new text-to-speech models to the Gemini family, transforming voice generation from static presets into a dynamic creative studio.
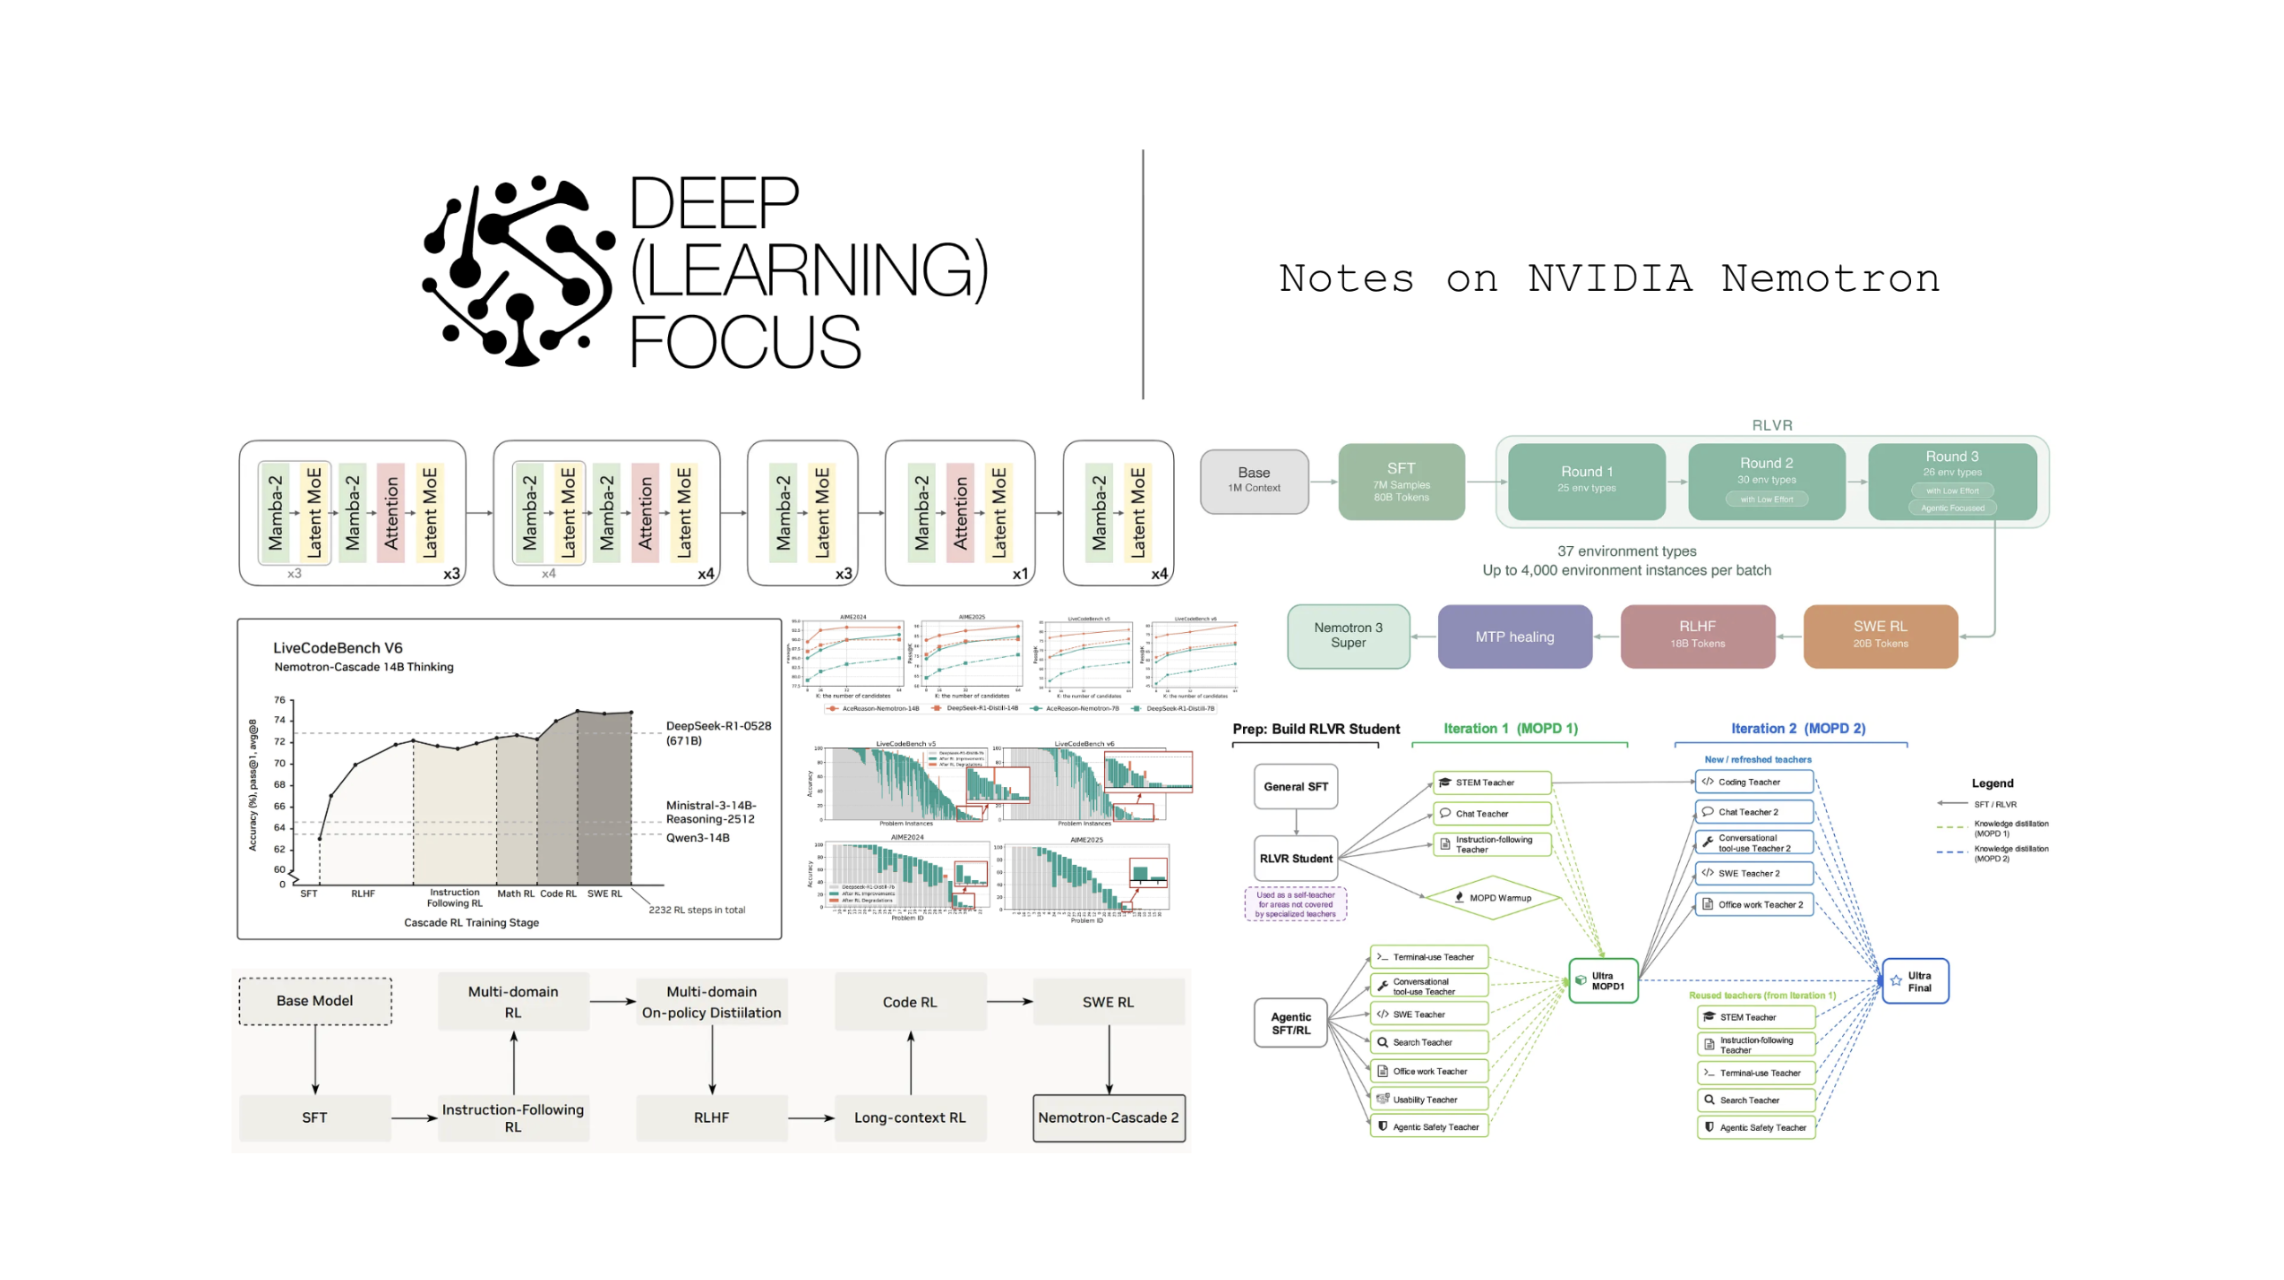
Notes on NVIDIA Nemotron
Today, many key details of frontier large language models (LLMs) remain proprietary, but open-weights model families—such as DeepSeek, Kimi, and MiMo—continue to provide a valuable window into the development process for modern LLMs. Among these resources, the NVIDIA Nemotron model series is especially useful due to its transparency.
GPT-6 and Intelligent UI for everyone
GPT‐6 is rolling out globally in ChatGPT with Intelligent UI, delivering faster responses with visuals and interactive experiences you can explore and use directly.
llm-openai-decisions 0.1a0
OpenAI released their new Jev-style Decisions API, as previously announced at last week's DevDay.

Our approach to EU text provenance rules
How OpenAI is approaching text watermarking under EU rules.
SparseDecoding: Decoding-Aware Pruning for Accurate and Efficient LLM Inference
The memory-bound nature of the decoding stage of large language model (LLM) inference incurs significant latency.
nerkyor/Qwen3.8-27B-Coder390-EfficientThink-Opus5.5-GPT6Astra-Grok4.7-DSV4Pro-K3-SFT-RLOO-MTP-DFlash2
nerkyor published the model Qwen3.8-27B-Coder390-EfficientThink-Opus5.5-GPT6Astra-Grok4.7-DSV4Pro-K3-SFT-RLOO-MTP-DFlash2 on Hugging Face.
REMORY: Learning Residual Memory for Context Compaction
We introduce REMORY, a neural memory network that supplements the summary with a bounded sequence of soft memory tokens.
VibeEdit: Image Editing with Canvas Instructions
We introduce a new image editing interface that lets users place spatial marks and optional short notes directly on the image.
alesha-pro/Qwen3.8-Flash-Next-abliterated-GSQ-RCO-Strata-GGUF
alesha-pro published the model Qwen3.8-Flash-Next-abliterated-GSQ-RCO-Strata-GGUF on Hugging Face.
SpatialOPSD: Self-Distilling Spatial Intelligence from Verified Coding Agent Traces
Spatial coding agents significantly improve spatial reasoning in Multimodal Large Language Models (MLLMs) by using external tools to generate verified execution traces.
LiquidAI/d1-omni-600M
LiquidAI published the model d1-omni-600M on Hugging Face.
MIMESIS: Learning User Simulators as Training Environments for Interactive Agents
We introduce MIMESIS, a purpose-built user simulator trained on human conversations with explicit reasoning supervision and 13 realistic behavioral patterns derived from real user interactions.
perplexity-ai/pplx-decider-v1.1-27b
perplexity-ai published the model pplx-decider-v1.1-27b on Hugging Face.
V-CoLA: Vision Token Compression with Linear Attention
To this end, we propose V-CoLA, an efficient training-free token compression framework specifically designed for linear attention.
Real Long-Term Memory for AI: A 50-Million-Token Window That Is Faster and Cheaper Than Recompute
We test a memory layer, the public package galahad-kv, that saves the KV state of each block of about 16,000 tokens to encrypted local NVMe disk and loads it back later, byte-exact, without recomputing it.
Scaling to Tens of Thousands of Test-Time Iterations with Loop-Native Attention Residuals
In this paper, we introduce InfiLoop, a loop-native residual connection that learns which past computations to retain and how much to accept from each new update.