Explore
Everything AION read, in seven sections. Pick one, a topic or a time window.
 Paper
Sharing AI progress in mathematics
OpenAI publishes new results on open problems in mathematics from an internal frontier model and shares Lean proof formalizations and research details on GitHub.
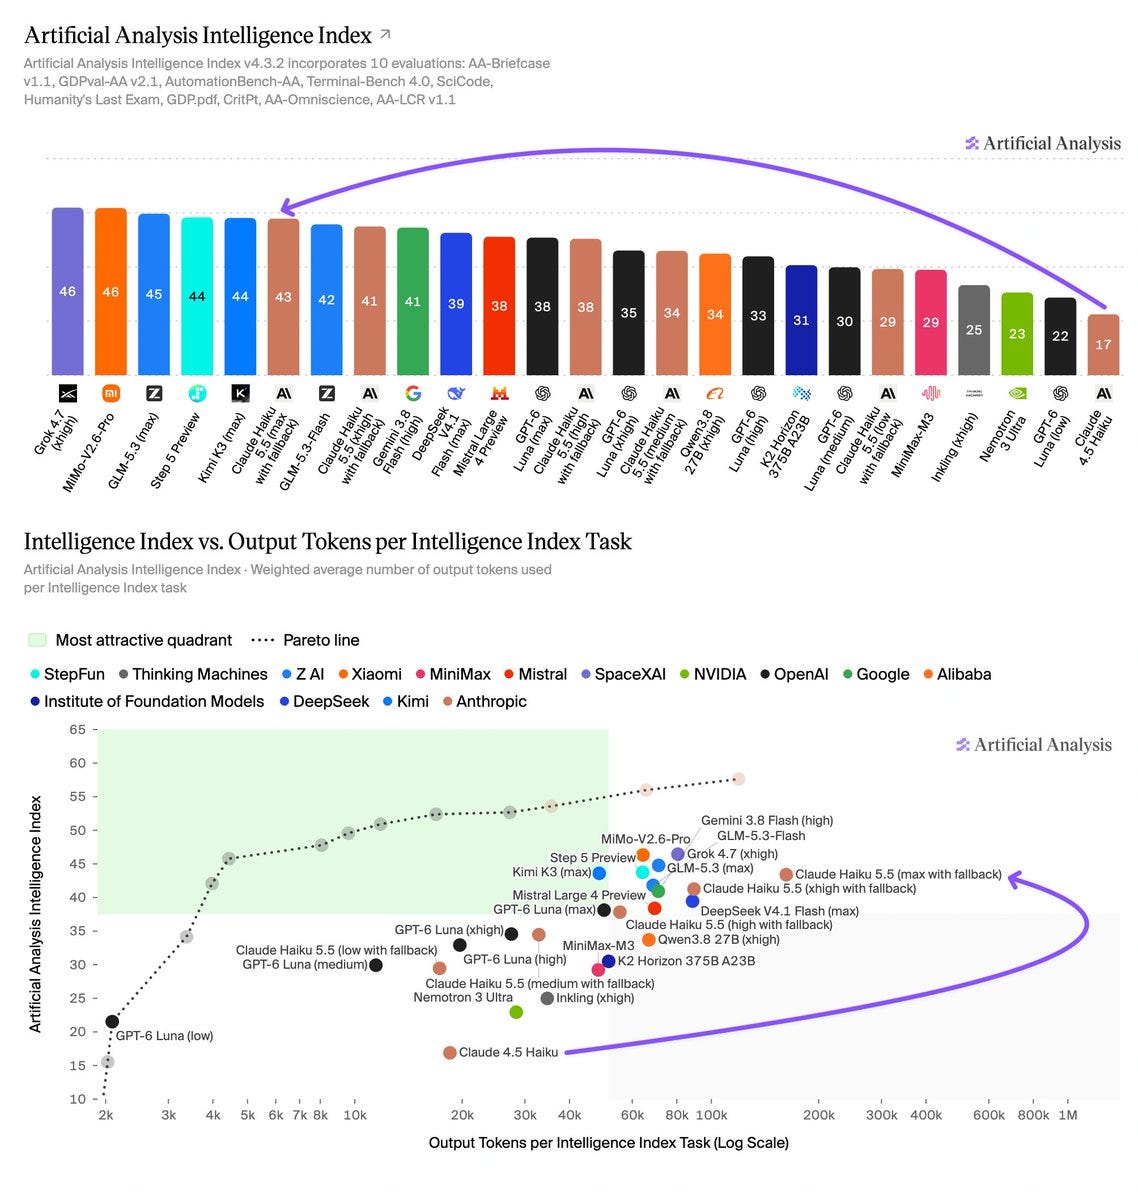
[AINews] Claude Haiku 5.5 — better than GPT-6 Luna at the same pricing
It’s been about a year since Anthropic shipped Haiku 4.5, and with successive launches of Sonnet and Opus and Fable up to 5.5 it was seeming a little forgotten, especially as OpenAI launched Luna 6 alongside Astra and Sol 6.

Introducing Clef-omni with full multimodality, plus a faster Clef and a cheaper Clef-flash
Today, we’re releasing Clef-omni, which takes in audio and video input alongside text and image.
ConwayResearch/Underdog-Saluki-27B-1.0
ConwayResearch published the model Underdog-Saluki-27B-1.0 on Hugging Face.
 Paper
Beyond Imitation: A Framework and Benchmark for LLM-Assisted Peer Review
Here, we introduce a verification-centric perspective on LLM-assisted peer review, emphasizing error detection as a critical and resource-intensive task.

OrcaRouter Releases OrcaCyber Zero 1.5 Cybersecurity Model With 1M Context
OrcaRouter has released OrcaCyber Zero 1.5, a model for authorized vulnerability research.
 Video
Teaching Agents to Search with NVIDIA Data Designer — Dhruv Nathawani, NVIDIA
Dhruv Nathawani uses that funnel to explain how NVIDIA builds synthetic data that teaches a model to search, rather than answer from memory.
Qwen 3.8 27B Q5 vs Qwen 3.8 Next Q3_S for document analysis
So far I've been using Qwen 3.8 27B Q5 with a 150K context window, but I'm wondering whether I should switch to Qwen 3.8 Next Q3S, since it has much more knowledge and could extract data much better than the 27B.
[P] Pecision models that score every allowed label from the logits: Jebadiah v2.1 (27B, 9B), open weights and self-run benchmark results [P]
I've been building open models that treat a decision as a closed-set scoring problem rather than text generation.
mistralai/LIDstral-Arabic
mistralai published the model LIDstral-Arabic on Hugging Face.
Byte Language Models: Scaling, Emergent Abstractions, and Information Allocation
The paper challenges the assumption that language models need explicit tokenizers to be efficient demonstrating that standard flat Transformers can process raw byte sequences and actually outperform traditional subword models as parameter sizes scale.
Why AlphaFold Didn't Solve Protein Folding — Pushmeet Kohli, Google DeepMind & Sal Candido, Biohub
From the Bitter Lesson of AI scaling to the unsolved mysteries of protein folding, Google DeepMind’s Pushmeet Kohli and Biohub’s Sal Candido are rethinking what it takes to build AI that truly understands biology.
Memento 3: Model-Based Recursive Self-Improvement through Reflective Rulebooks
We introduce Memento 3, building on the Memento series to enable frozen LLM agents to continually learn explicit world models through external memory.
langchain-ai/langchain langchain-openai==1.7.0
chore(deps): bump langgraph-sdk from 0.4.4 to 0.4.6 in /libs/partners/openai (#41096)
 Video
Microsoft Joins the Local AI Push
Microsoft is clearly going all in on local AI running on your machine and working with cloud models only when it needs to use them.
unslothai/unsloth v0.1.905-beta: Sandboxing is here!
We're introducing Windows, Mac and Linux sandboxing in Unsloth!
Text is so 2023
Hark (from Brett Adcock - Figure robots) launched which suggests tasks as one-tap action buttons.
Introducing Falcon ASR
We’re introducing Falcon-ASR, our 1.6 billion parameter speech recognition model for Arabic, with a particular focus on the Emirati dialect.
Expanding the Cyber Verification Program
We’re launching a new, expanded version of our Cyber Verification Program (CVP), which makes advanced cyber capabilities and reduced blocking classifiers available to qualifying security professionals.
 Paper
RISED: Rubrics for Agentic Multi-Environment Selection and Self-Distillation
RISED: Rubrics for Agentic Multi-Environment Selection and Self-Distillation
huggingface/transformers v5.19.0: Release v5.19.0
EmbeddingGemma 2 is a multimodal embedding model from Google built on the Gemma 4 architecture.
Introducing GLM 5.3 on Amazon Bedrock
GLM 5.3 from Z.ai (Zhipu AI) is now available on Amazon Bedrock.
huggingface/trl v1.14.2
Patch release fixing two cases of silently wrong training and three crashes.
MCP for agent-to-agent comms may be the riskiest protocol you've never heard of
The adoption of AI agents in millions of organizations is creating new opportunities for attackers to make them take malicious actions, such as exfiltrating database contents and sensitive business and personal information.
langchain-ai/langgraph 1.2.13: langgraph==1.2.13
fix(langgraph): fork before replaying an update checkpoint the thread moved past (#9170)
llm-openai-decisions 0.1a0
OpenAI released their new Jev-style Decisions API, as previously announced at last week's DevDay.
Converting dense models into Mixture-of-Experts
For the past few weeks I've been trying out converting existing dense models to sparse Mixture-of-Experts models, with no pretraining from scratch.
Running Next Flash IQ3_XXS at ~70 tok/s with 100k context or 2 instances of Qwen 3.6 35B A3B IQ4 at ~145 tok/s with 256k all on $500 of ex mining BC-250 boards
This will be my third update on the bc-250 cluster and for my first forray into local ai I have been having a blast.
GPT-6 and Intelligent UI for everyone
GPT‐6 is rolling out globally in ChatGPT with Intelligent UI, delivering faster responses with visuals and interactive experiences you can explore and use directly.
OMG! If you have a Mac with 64GB, try Qwen3.8-Flash-Next-oQ4e-mtp with oMLX!
I was able to run Qwen3.8-Flash-Next-oQ4e-mtp on M3Max 64GB with oMLX!
Benefits of using bigger models than Qwen 3.8 flash next?
Qwen 3.8 27b was the first model I tried on Ninfer at NVFP4 and then shifted to Flash next after seeing issues with 27b such as not willing to yield to instructions set in AGENTS.md or agent skills.
Engineer / developer observations of Gemma4-31B, Qwen3.8-27B, and 6.1-Sol for software engineering work
Models: Gemma4-31B vs Qwen3.8-27B at the same quantization (an Unsloth flavor of Q4).
Is anyone running Qwen3.8 Flash Next with a 1M context?
So, while doing a search to read the model card again, and because I didn't memorize the huggingface URL, I saw an AI "answer" at the top of the search, stating that while it natively supports a ~244k context, it could go to 1M using YaRN.
SparseDecoding: Decoding-Aware Pruning for Accurate and Efficient LLM Inference
The memory-bound nature of the decoding stage of large language model (LLM) inference incurs significant latency.
VibeEdit: Image Editing with Canvas Instructions
We introduce a new image editing interface that lets users place spatial marks and optional short notes directly on the image.
[AINews] Reflection Beam - 501B-A23B American Open Model
It’s been over a year since Reflection launched with us with big goals on coding (and hinted about their RL approach):
Asana cuts model costs 76x in browser tests with GPT-6.1 Sol
Using GPT-6 Astra in Codex, Asana made its browser agent 76x cheaper and 5x faster in tests to offer customers more capable models.
REMORY: Learning Residual Memory for Context Compaction
We introduce REMORY, a neural memory network that supplements the summary with a bounded sequence of soft memory tokens.
SpatialOPSD: Self-Distilling Spatial Intelligence from Verified Coding Agent Traces
Spatial coding agents significantly improve spatial reasoning in Multimodal Large Language Models (MLLMs) by using external tools to generate verified execution traces.
V-CoLA: Vision Token Compression with Linear Attention
To this end, we propose V-CoLA, an efficient training-free token compression framework specifically designed for linear attention.
ttok 1.0
I released ttok 0.4, ran uv tool upgrade ttok, piped a file into the new version... and realized that it was defaulting to the GPT-4 tokenizer when it should very clearly default to GPT-5/GPT-6 instead!
Scaling to Tens of Thousands of Test-Time Iterations with Loop-Native Attention Residuals
In this paper, we introduce InfiLoop, a loop-native residual connection that learns which past computations to retain and how much to accept from each new update.
From Prompting to Composing: A Spatial Canvas Interface for Poster Generation
We introduce a Spatial Canvas Interface that enables users to directly compose generation intent in space through four complementary binding types: semantic, identity, text, and pixel, together with Text Specifications for individual elements and global appearance.
How Oracle turns days of work into minutes with ChatGPT and Codex
Across recruiting, engineering, and operations, Oracle turns specialist knowledge into fast, repeatable workflows with ChatGPT Work and Codex.

Our approach to EU text provenance rules
How OpenAI is approaching text watermarking under EU rules.
Real Long-Term Memory for AI: A 50-Million-Token Window That Is Faster and Cheaper Than Recompute
We test a memory layer, the public package galahad-kv, that saves the KV state of each block of about 16,000 tokens to encrypted local NVMe disk and loads it back later, byte-exact, without recomputing it.
The Lattice of Transition Laws
Diffusion and autoregression (AR) have long been seen as different categories of generative models, with diffusion specialising in continuous fields and AR specialising in discrete tokens.
MIMESIS: Learning User Simulators as Training Environments for Interactive Agents
We introduce MIMESIS, a purpose-built user simulator trained on human conversations with explicit reasoning supervision and 13 realistic behavioral patterns derived from real user interactions.