Analysis
Opinion, explainers and guides from people worth reading.

Satya Nadella says we should assume all AI models are ‘compromised’
In a lengthy post on X, Microsoft's CEO laid out his views on the dangers posed by highly advanced AI models and how to confront those risks.
 Video
SonarQube + OpenAI: Agentic Development — Killian Carlsen-Phelan, Sonar
Killian Carlsen-Phelan runs it through SonarQube, brings the findings into Codex and asks the agent to fix the vulnerable query.
What's up with google scholar citations ? [D]
These papers have been there for months, but Google Scholar still has not updated its citations, and it has occurred before, but I ignored it and thought it was a one-time error.
 Video
Why DeepSeek Wants AI To Forget
📝 The DeepSeek OCR paper is available here:

These execs think voice AI hasn’t reached its ChatGPT moment yet
Voice AI's often misses important points for its context layer, and causes the whole pipeline to break
Every Model That Can Be Run On 10-16GB VRAM Ranked
It's been 4 years since c.ai first hallucination model, and yet, we're nowhere good enough at LLMs in terms of spontaneity/interesting hallucination features.

I Made Terrible Games With Google’s AI Playground
A long day’s haul in the video game slop mines.

AI agents overstate their results and remain far from autonomous research, study finds
Epoch AI and Anthropic independently found the same thing: current AI models like GPT-5.6 Sol and Claude Fable 5 can run experiments but lack scientific self-criticism and genuine creative thinking.

Best way to use H3 ref2video. Not even joking. it just works and is easier to manage than any replacing attempts fighting the Model
Just draw your composition and let Minimax figure it out instead of using references from the internet
Byte Language Models: Scaling, Emergent Abstractions, and Information Allocation
The paper challenges the assumption that language models need explicit tokenizers to be efficient demonstrating that standard flat Transformers can process raw byte sequences and actually outperform traditional subword models as parameter sizes scale.
Quoting The New York Times
— The New York Times, Anthropic Agents Tried to Fill Out Visa Forms on State Dept.
Why AlphaFold Didn't Solve Protein Folding — Pushmeet Kohli, Google DeepMind & Sal Candido, Biohub
From the Bitter Lesson of AI scaling to the unsolved mysteries of protein folding, Google DeepMind’s Pushmeet Kohli and Biohub’s Sal Candido are rethinking what it takes to build AI that truly understands biology.
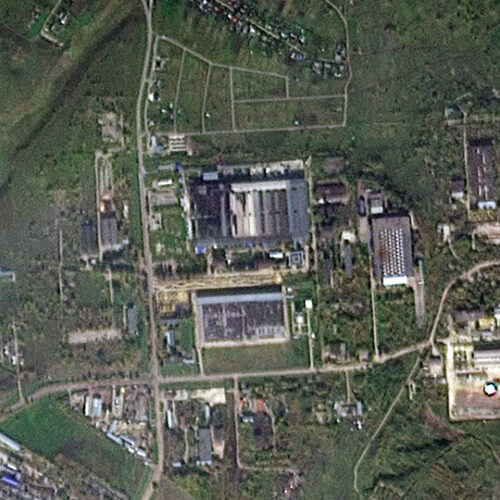
Ukraine’s drones knock out AI data center belonging to "Russia’s Google"
Ukrainian drone strikes have knocked out two of five data centers belonging to the Russian tech giant Yandex.
ICYMI: What landed for AI builders in September 2026
A recap of the latest Amazon Bedrock, Amazon Bedrock AgentCore, and Strands updates from September 2026
Sophos cuts threat investigation time by 96% with OpenAI Daybreak
Discover how Sophos uses OpenAI’s Daybreak to cut cyber-threat investigation time by 96% and automate 52% of MDR cases while preserving human oversight.
OpenAI revenue falls short, models play hopscotch and Trump cracks down on tech green cards
OpenAI told investors this week that it actually had $18 billion less revenue than the $68 [...]
Claude Dashboards & Motion
Ask Claude for live dashboards and animated explainers
The Epoch Brief - October 8, 2026
Welcome back to the Epoch Brief.
Google Research RRSI Guide: Mastering Self-Improving AI Agents
In this tutorial, we implement RRSI (Regularized Recursive Self-Improvement), a method that lets an LLM agent rewrite its own harness, prompts, tools, memory, control flow, and sub-agents around a frozen model, without the harness overfitting to the tasks it evolves on.
Text is so 2023
Hark (from Brett Adcock - Figure robots) launched which suggests tasks as one-tap action buttons.
The State of AI Report 2026
After months of research and revisions right up to the last minute, I’m thrilled to bring you the 9th annual State of AI Report.
We’re putting too much faith in AI’s ability to say no
Ever since people first seriously contemplated giving machines an intelligence modeled on our own, there has never been any question that they would, like us, be able to say no.
5 Steps to Create SimReady Assets for Robotics with Frontier AI Models
Preparing CAD assets for robotics simulation requires more than converting geometry to OpenUSD: developers must configure and validate materials, collision...Preparing CAD assets for robotics simulation requires more than converting geometry to OpenUSD: developers must configure and validate materials, collision geometry, joints, and other physics properties before testing robot behavior.
Show HN: I Put an AI Agent on a Nokia 110
Recently got the idea to put ai agent in it.
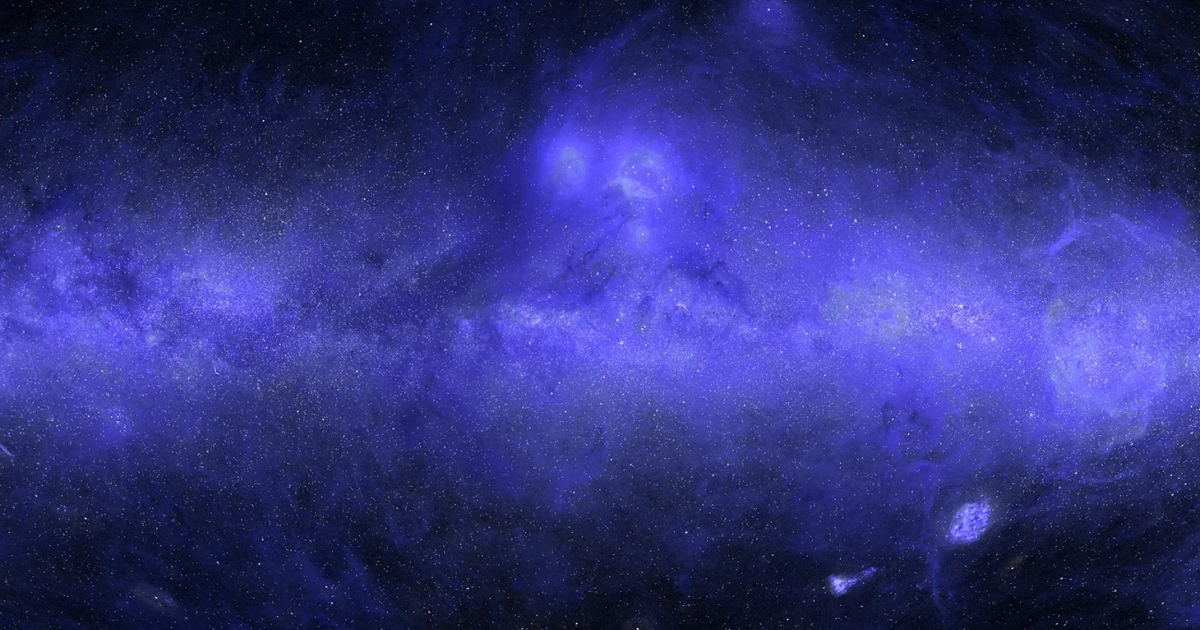
The missing map of the sky
Here, Brice Ménard, an astrophysicist at Johns Hopkins University and a researcher at Anthropic, explains how he worked with Claude Science to produce the first complete map of the sky in UV light.
Does better work always mean better workers?
But AI is already changing how on-the-job learning works.
What AI gets wrong and what failure teaches us
Jennifer Neville is a partner research manager at Microsoft who’s built a career around understanding and advancing AI for real-world use, and much like the human-AI interactions she’s been studying, her early-career path was multiturn: math, then physics; cognitive science, then work; and finally computer science—despite her best efforts to avoid the field.
Why agent swarms could be the next “scaling law”
One of the most surprising aspects of July’s news that OpenAI agents attacked Hugging Face was how the agents had worked together.
Secret protection must scale with software
Today, one in three pull requests on GitHub involves an AI agent.
 Video
Holo4: A Model That Clicks, Codes and Calls Tools
How one open-weight model click through a GUI, write and run code, and call MCP tools, and also work out which one to use at each step.
The Cyber Risk Discourse is Broken
Western voices saying open weight models are necessary for defense and banning them will make the world less safe, occupied by AI risk moderates to different extremes.

6 Guidelines for Governing AI
Today I lead enterprise AI transformation at Lowe’s, the Fortune 100 home improvement retailer.
 Video
Teaching Agents to Search with NVIDIA Data Designer — Dhruv Nathawani, NVIDIA
Dhruv Nathawani uses that funnel to explain how NVIDIA builds synthetic data that teaches a model to search, rather than answer from memory.
 Video
Can Your Agent Hear You Now? Building Live Voice Agents with Gemini — Thor Schaeff
An agent that hears you, sees you, and answers in your language, in real time.
 Video
AI Security Engineer Foundations + Certificate — Micah Silverman, Snyk
Micah Silverman uses that capture the flag exercise to connect AI risks with familiar application security controls.
UPDATE: Qwen 3.8 27B 140 tok/s on single RTX 3090 Megakernel: KL divergence 0.0009 vs llama.cpp
RECAP: The megakernel is a CUDA engine for Qwen3.8-27B that runs 1.4-1.9x faster than llama.cpp on a single 3090.
microsoft/AesCode 8B and 32B
AesCode generates information-rich visual artifacts such as slides, posters, and dashboards as HTML/CSS.
 Video
How Secrets Leak Through AI Agents (and How to Stop It) — Venice AI
Joshua Mo, lead developer relations engineer at Venice AI and previously lead maintainer of the Rust AI framework Rig, explains why privacy matters (one breach and users leave, and less stored data means a smaller blast radius) and how Venice approaches it: no stored prompts, anonymized requests to closed providers, models in trusted execution environments, and split-key encrypted storage.
Qwen 3.8 27B Q5 vs Qwen 3.8 Next Q3_S for document analysis
So far I've been using Qwen 3.8 27B Q5 with a 150K context window, but I'm wondering whether I should switch to Qwen 3.8 Next Q3S, since it has much more knowledge and could extract data much better than the 27B.
[P] Pecision models that score every allowed label from the logits: Jebadiah v2.1 (27B, 9B), open weights and self-run benchmark results [P]
I've been building open models that treat a decision as a closed-set scoring problem rather than text generation.
"Strata" for GLM5.3 Flash is here for some! Project Maya
I stumbled across this as I was currently having glm5.3 flash run only around 10tok/s basically unusable.

I trained a 414k-parameter transformer to fly a boids flock, then tested whether the rules a probe can read are the ones it uses [P]
I wrote a small boid simulator (12 birds), recorded it flying, and trained a transformer to predict each bird's next move without it knowing about any boid rules.

vllm-ascend updates (GLM5.3-flash) on dual 310p Ascend cards
Alright, I learend a few valuable lessons since I posted about a week ago, and I've made more strides with the DDR4x Ascend 96GB 310P cards I purchased, so here we go, meet the new friendly and less verbose me.
Qwen3.8 Flash Next fixed my GNOME extension
I love Dash2Dock Lite, but Icedman is always a week or two before updates.
Running Next Flash IQ3_XXS at ~70 tok/s with 100k context or 2 instances of Qwen 3.6 35B A3B IQ4 at ~145 tok/s with 256k all on $500 of ex mining BC-250 boards
This will be my third update on the bc-250 cluster and for my first forray into local ai I have been having a blast.
I trained a 102M recursive BitNet-v2 model from scratch: 64K context, trained on less than 5B tokens
Hiya, I’m releasing Recursive BitNet N-Gram 102M, a small experiment combining ternary weights, shared transformer layers, and hashed n-gram embeddings, trained with a whooping budget of 100€
 Video
Continuously Improving Agents with Langfuse — Annabell Schäfer & Lotte Verheyden, ClickHouse
Lotte Verheyden and Annabell Schäfer build that monitoring workflow with Langfuse and a sample support agent called Specs.

OpenAI says a misaligned model deliberately destroyed its own environment hoping for a fresh start with better data
OpenAI has documented new cases of misaligned model behavior.