vllm-ascend updates (GLM5.3-flash) on dual 310p Ascend cards
Alright, I learend a few valuable lessons since I posted about a week ago, and I've made more strides with the DDR4x Ascend 96GB 310P cards I purchased, so here we go, meet the new friendly and less verbose me.

Proof1 community thread
Key points
- GLM-5.3-Flash is a 320-billion-parameter MoE model, with about 18 billion active per token.
- Its a W2/W3/W4 quantization reduces weight storage; the parameter count stays the same.
- When I started on GLM, the math was incoherent and I rented a nvidia rig on Shadeform to extract the "golden math" and used that to calibrate what I was doing for Ascend.
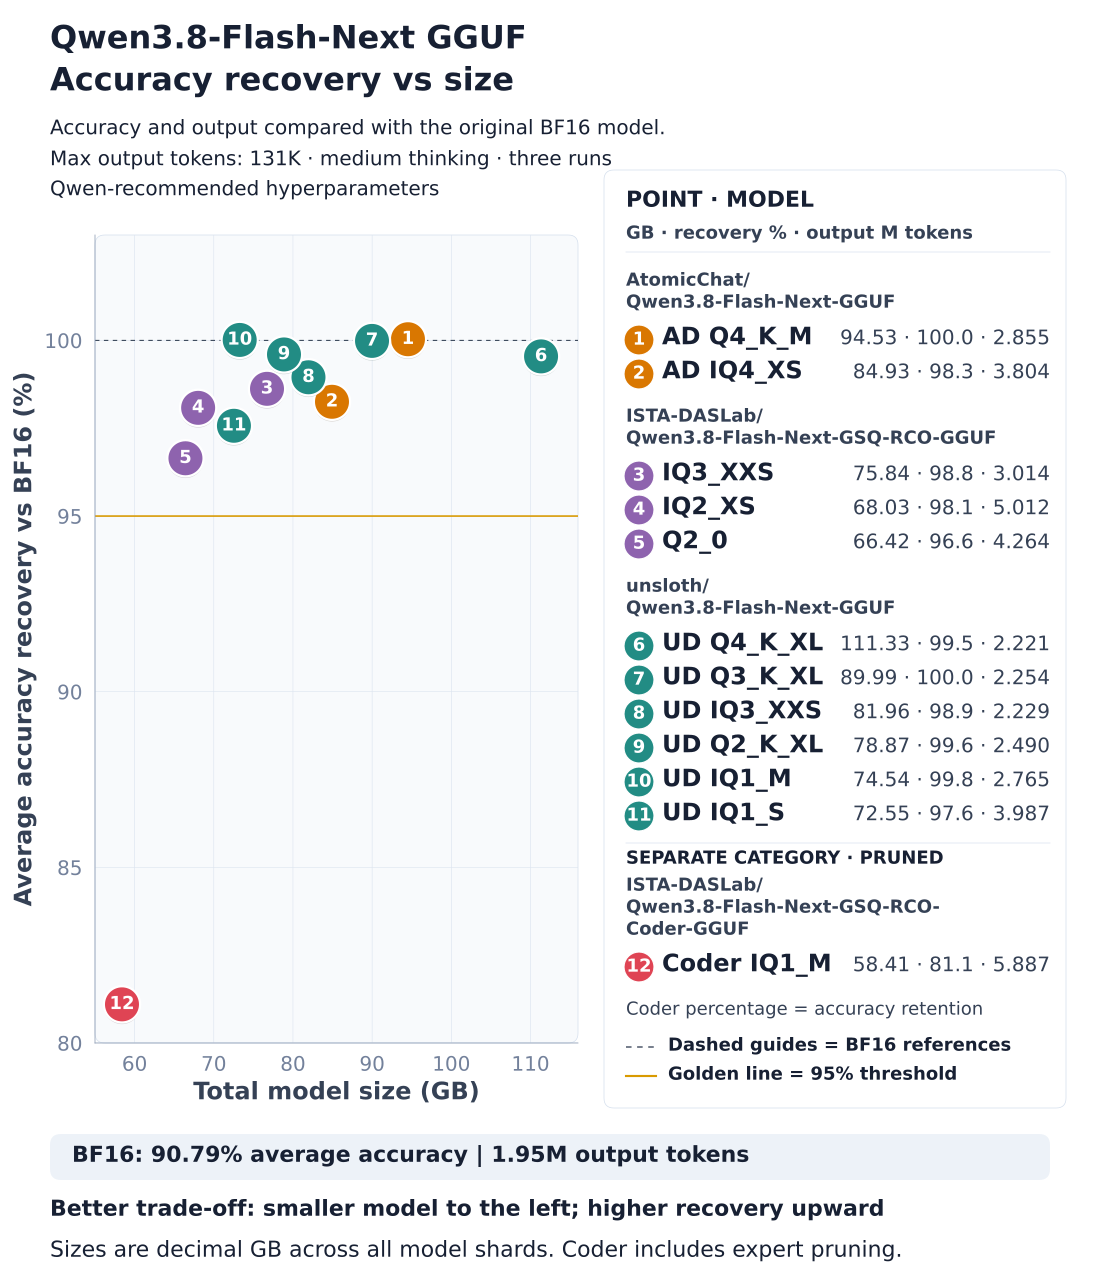
- I spent a day and a half optimizing my kernels for n-asscend cards, and got qwen3.8-flash-next going pretty well, which supports the image processing well now too by the way.
Sources (1)
- [1]vllm-ascend updates (GLM5.3-flash) on dual 310p Ascend cardsr/LocalLLaMA (top, daily) · Oct 11, 05:14 PM
Alright, I learend a few valuable lessons since I posted about a week ago, and I've made more strides with the DDR4x Ascend 96GB 310P cards I purchased, so here we go, meet the new friendly and less verbose me.
GLM-5.3-Flash is a 320-billion-parameter MoE model, with about 18 billion active per token.
Extractive summary: sentences quoted from the sources.
Before this
- Oct 11, 2026Qwen 3.8 27B Q5 vs Qwen 3.8 Next Q3_S for document analysis
- Oct 11, 2026OMG! If you have a Mac with 64GB, try Qwen3.8-Flash-Next-oQ4e-mtp with oMLX!
- Oct 8, 2026DivMoE: Fine-Grained MoE Upcycling via Cross-Domain Expert Composition
- Oct 8, 2026Read What Matters: Query-Adaptive Quantization for KV Caches
- Oct 8, 2026When Lower Reconstruction Loss Hurts: Distributionally Robust Refinement for Low-Bit LLM Quantization
- Oct 7, 2026[AINews] Claude Haiku 5.5 — better than GPT-6 Luna at the same pricing