Specialized Decision Models vs. General-Purpose LLMs: Benchmarking Jev Across Knowledge, Reasoning, and Multilingual Tasks
We study how such a specialized decision model compares with general-purpose large language models (LLMs).
Key points
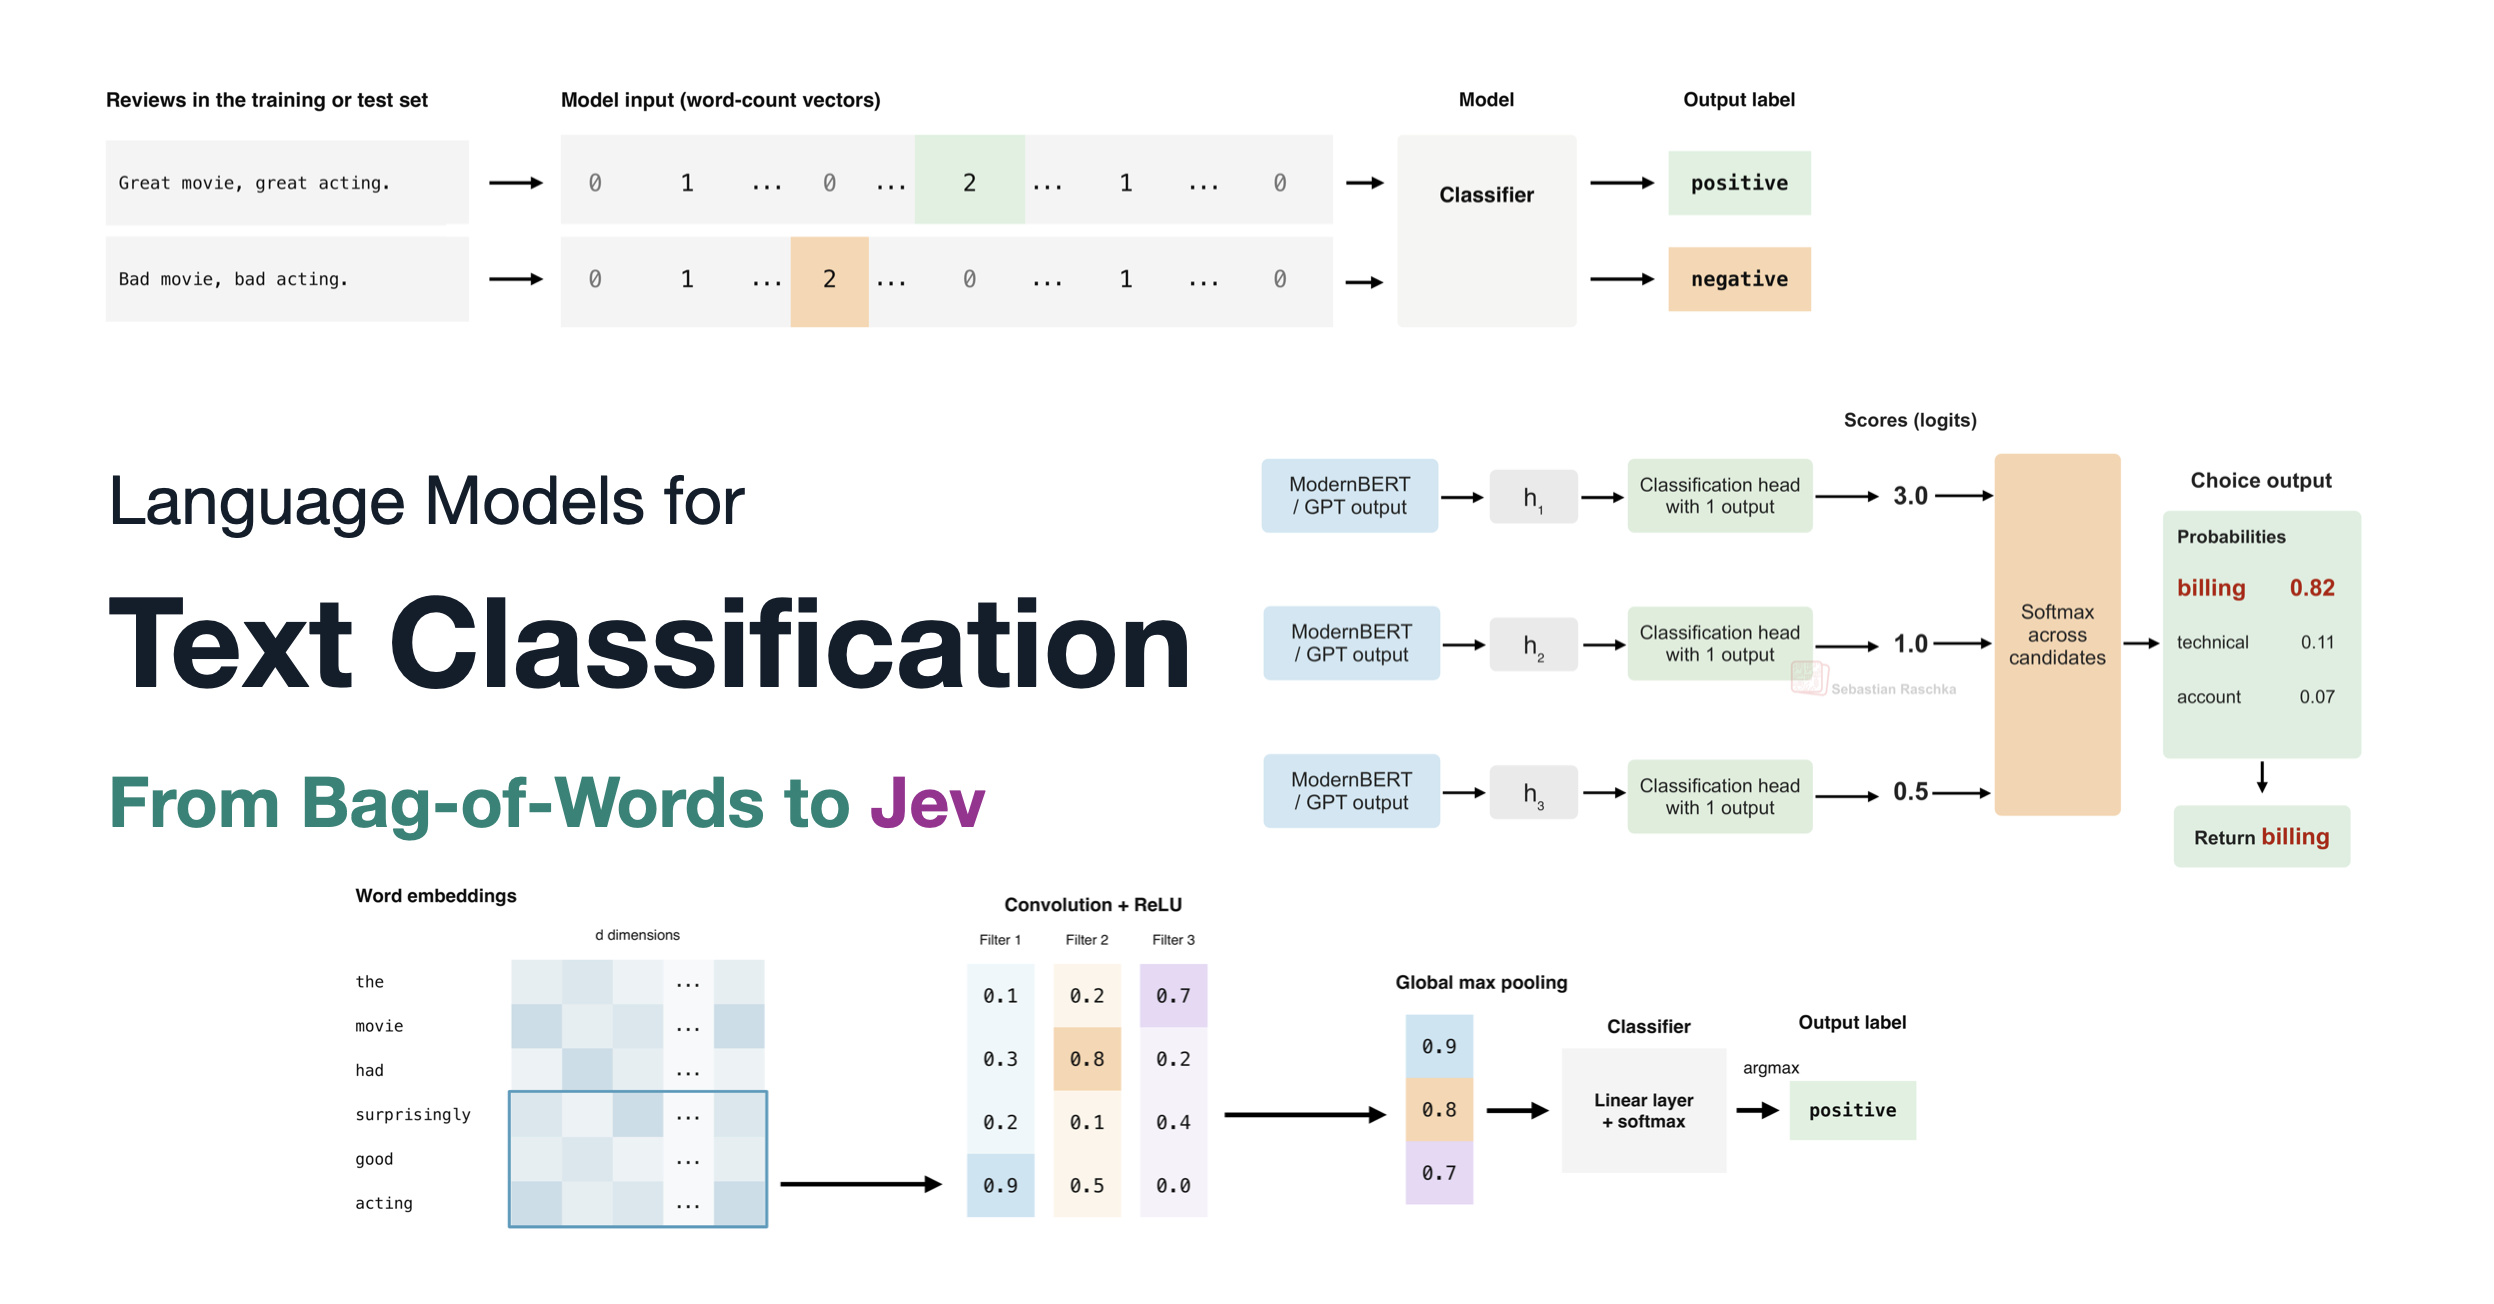
- Jev is a "System One" model that returns a choice among given options instead of generating text.
- We evaluate Jev on 13 multiple-choice benchmarks covering knowledge, reasoning, and multilingual understanding, and compare it with 19 LLMs in three tiers: frontier, representative, and small.
- Jev is competitive with frontier LLMs on knowledge and commonsense benchmarks and obtains the best score on MMLU-Redux and ARC-Challenge.
Sources (1)
- [1]Specialized Decision Models vs. General-Purpose LLMs: Benchmarking Jev Across Knowledge, Reasoning, and Multilingual TasksarXiv (AI, ML, NLP, CV, robotics, multi-agent) · Oct 8, 01:52 PM
We study how such a specialized decision model compares with general-purpose large language models (LLMs).
Jev is a "System One" model that returns a choice among given options instead of generating text.
Extractive summary: sentences quoted from the sources.