Explore
Everything AION read, in seven sections. Pick one, a topic or a time window.
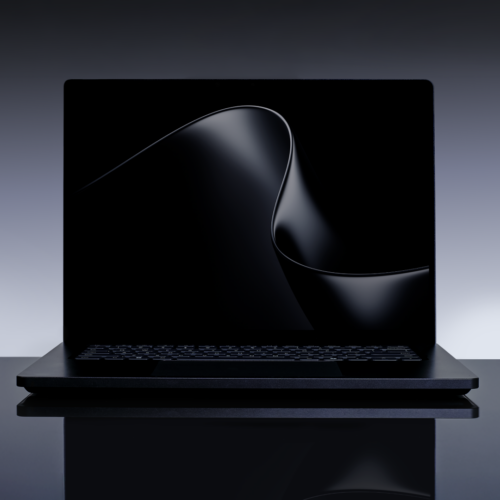
Microsoft event debuts new AI-friendly hardware and Windows changes
In its first live event in two years, Microsoft today announced its newest Surface laptop, outlined a host of changes coming to Windows 11, and shared a vision of how local-AI and agentic workflows could reshape personal computing for those in the dev community as well as home enthusiasts.
Scaling Decision Optimization to 100 Million Variables and Beyond with mPDLP in NVIDIA cuOpt
NVIDIA cuOpt GPU-accelerated decision optimization can already deliver speedups of more than 10x over CPU...
Expanding our enterprise inference capacity with IBM Cloud and NVIDIA
Enterprises can now run open models at production scale on a dedicated B300 inference cluster, built by Together AI, IBM Cloud, and NVIDIA
 Video
Why DeepSeek Wants AI To Forget
📝 The DeepSeek OCR paper is available here:
Qwen3.8 Flash Next fixed my GNOME extension
I love Dash2Dock Lite, but Icedman is always a week or two before updates.
The Epoch Brief - October 8, 2026
Welcome back to the Epoch Brief.
 Video
AI Apps in a Flash: Ship to GPUs Without Docker — Dean Quiñanola, Runpod
Dean Quiñanola, staff engineer at Runpod, introduces Runpod Flash, which lets you run Python on cloud GPUs as if the GPU were local, with no Dockerfiles, image builds or registry pushes.

Updated ComfyUI-SeedVR2-VideoUpscaler-with-TensorRT v1.6.6 - Native ConvRot W4A8 Support & DisTorch2 Scope
The other day, when I published information about v1.5.7, I received a request in the comments regarding support for w4a8.
Democratizing MoE inference on commodity GPUs with CoMoE
We present CoMoE, a communication-efficient MoE inference system that resolves this mismatch through novel host-centric routing.
Impactful scheduling for GPU clusters
On the AI Infrastructure team at Ai2, we’re responsible for providing the institute’s GPU compute capacity, specifically targeting large, distributed training workloads.
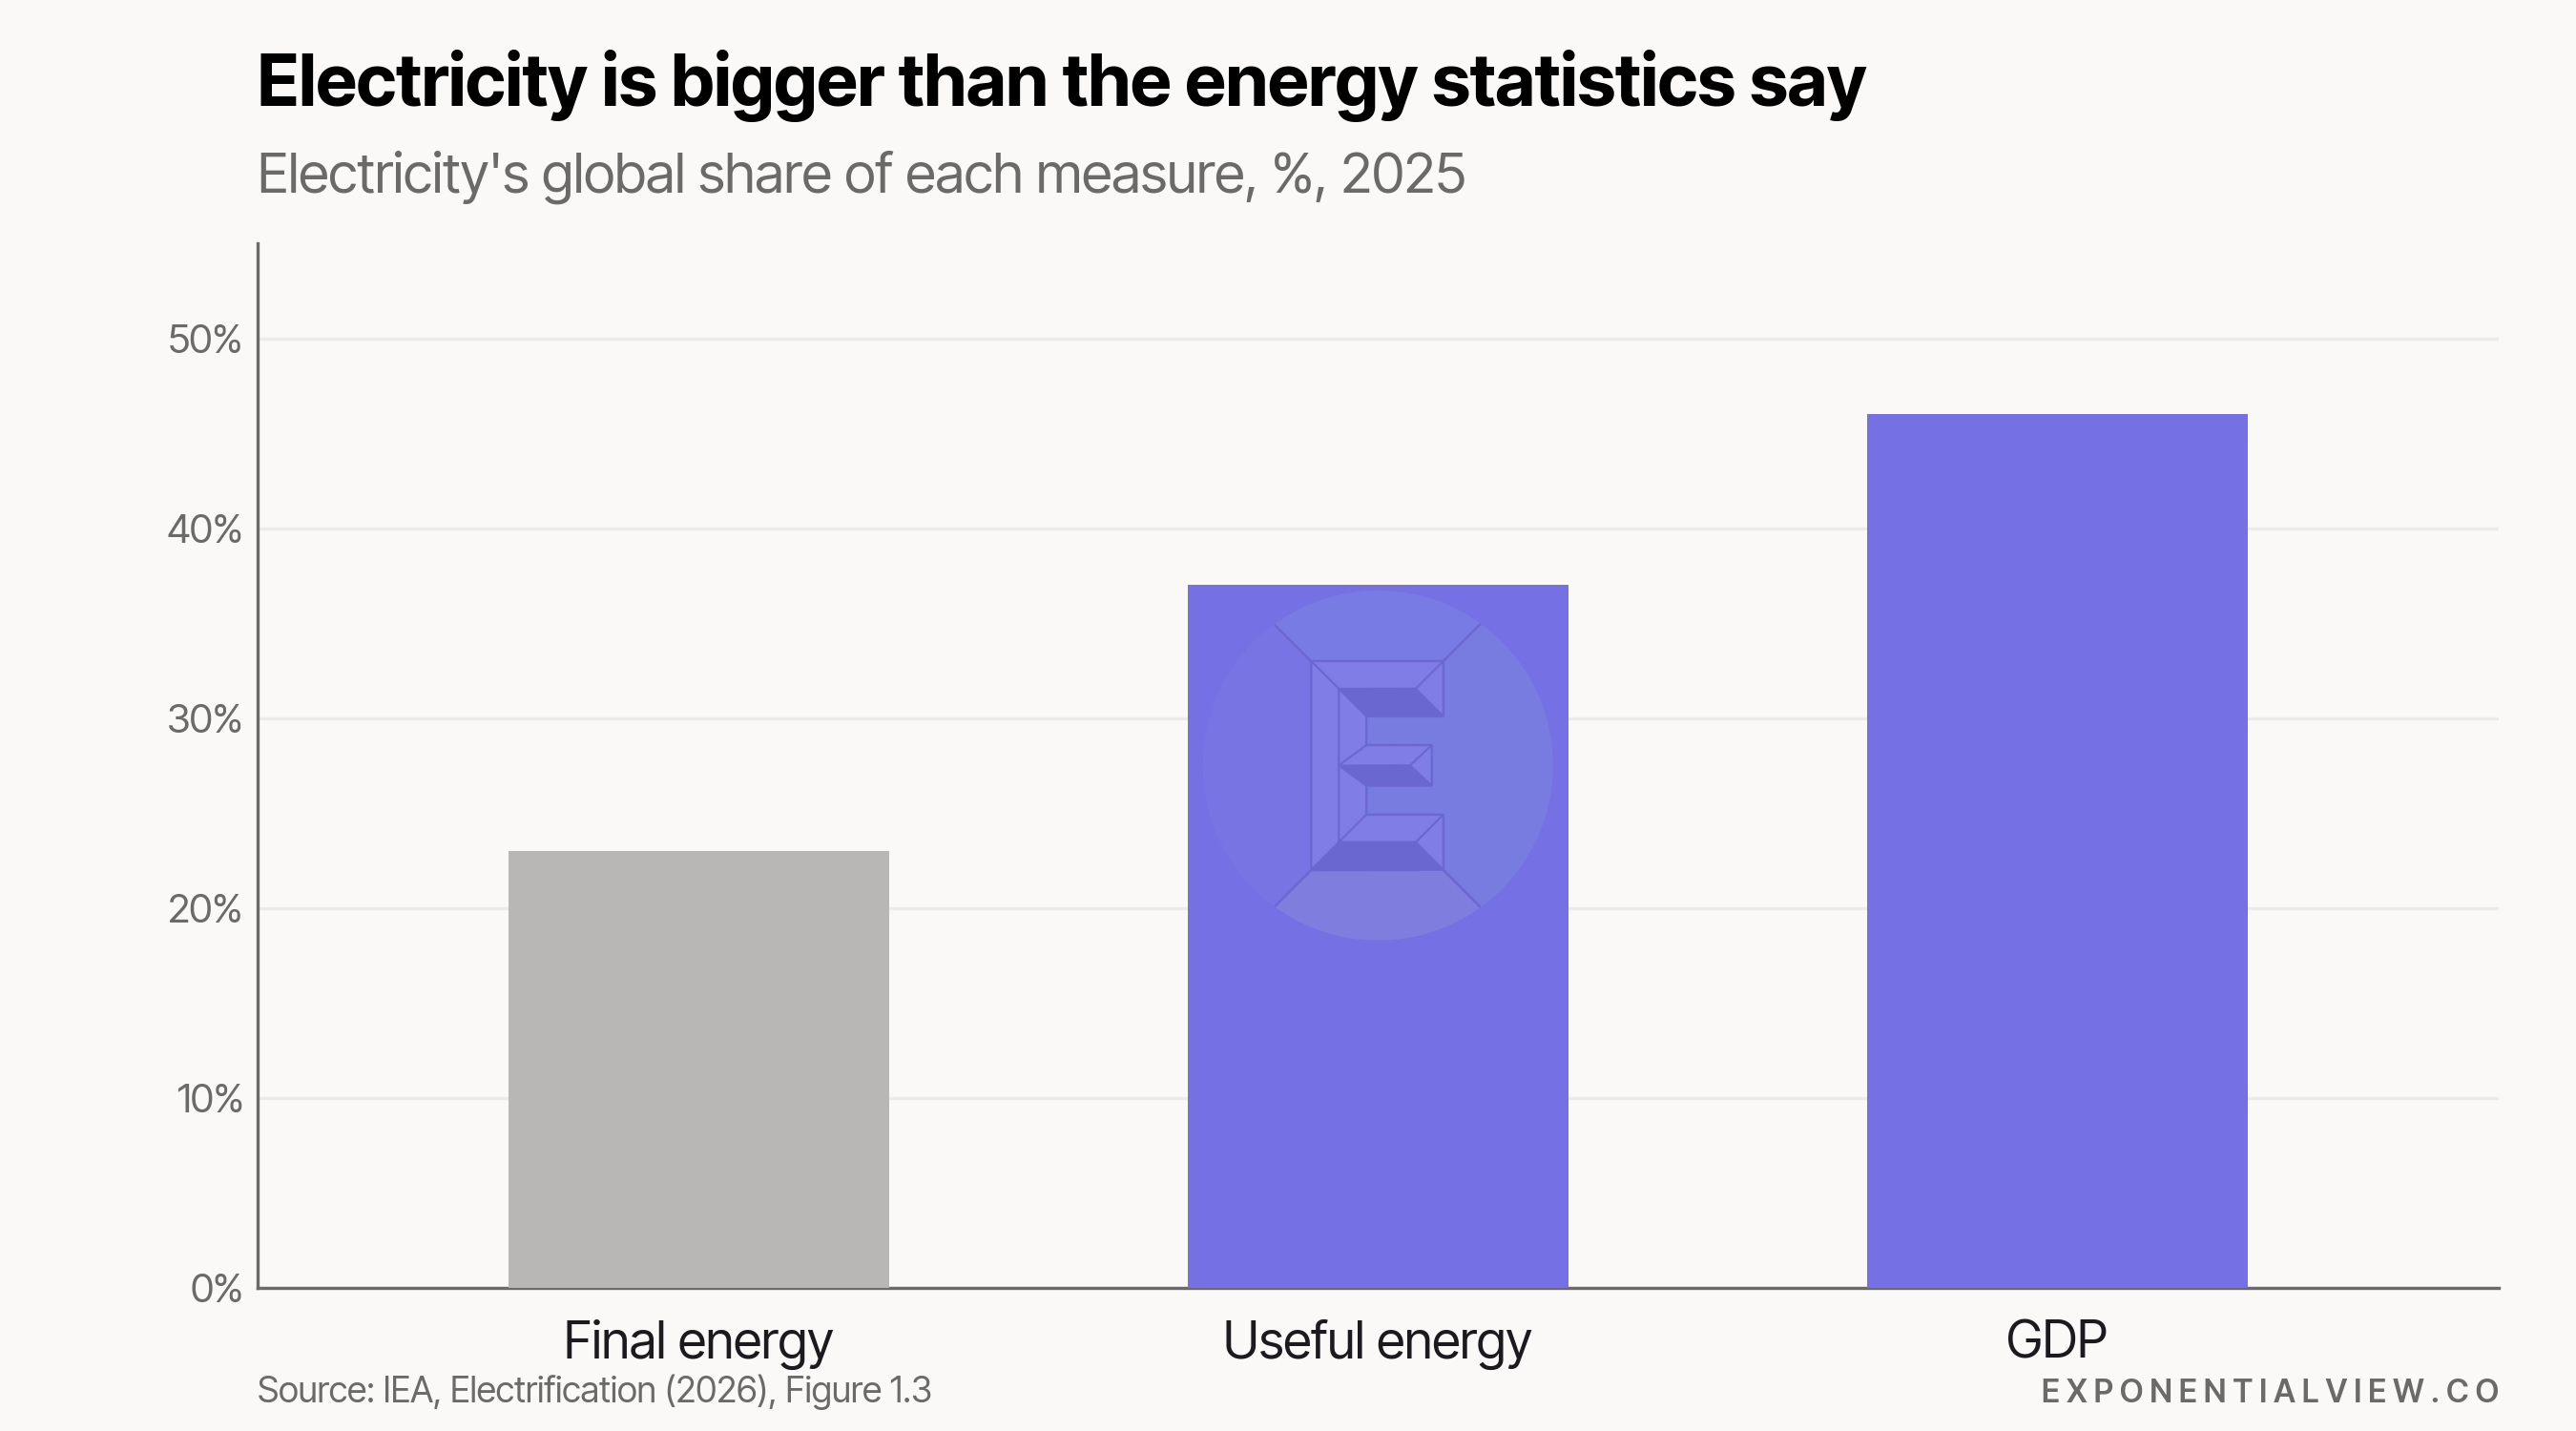
🔮 The transition is hiding in plain sight #604
We are continuing to push hard on untangling this data and more over at our AI Investment Brief by Exponential View.
Help With Choosing Hardware [P]
I am going to fine-tune a satire model, with the base model being Qwen3.5-14B-Base.

Cheaper AI tokens are driving more demand, and that's Jensen Huang's best-case scenario
Data from a16z shows a Jevons paradox in the AI market: token prices keep falling, but H100 GPU rental prices hold steady or climb.
ray-project/ray ray-2.59.0: Ray-2.59.0
Ray Data LLM & Ray Serve LLM are GA/Stable: the LLM APIs graduate to general availability this release (\#65194), alongside an upgrade to vLLM 0.27.0 (\#65351).

48 hours to TechCrunch Disrupt 2026 — hear directly from the people building what’s next
Less than 48 hours, TechCrunch Disrupt 2026 starts in San Francisco’s Moscone West.
What to expect during the AI Data Pipeline Forum: Join theCUBE Oct. 13
The post What to expect during the AI Data Pipeline Forum: Join theCUBE Oct.
sergqwer/strata-nvfp4: Strata fork: Qwen3.8-Flash-Next 125B MoE in NVFP4 on one RTX 20-50 card (12 GB+) and 64 GB of RAM or more. Setup installs our GPTQ quants (h
Strata fork: Qwen3.8-Flash-Next 125B MoE in NVFP4 on one RTX 20-50 card (12 GB+) and 64 GB of RAM or more.
Rex's Dino Store
Located just before the turnstiles in the Grand Army Plaza subway station at the north end of Brooklyn's Prospect Park is this former newsstand which is now operated by a dinosaur.
The Computer Game
Build the best computer, from stone tools to your own chips

Master AI Chip Principles With New IEEE Design Program
Today’s engineers face an unprecedented acceleration in AI hardware complexity, as explained in the recent research article “Revisiting Edge AI: Opportunities and Challenges.” The article examines the rapid growth of edge AI and the challenges it creates, including resource constraints, model architecture limitations, and network demands across edge-AI deployments.
Advancing Private AI Compute with secure, server-side memory
A technical update on our Private AI Compute architecture, which will enable persistent, cross-device AI memory with on-device privacy standards.
Watch astronaut Christina Koch and Google’s James Manyika discuss space, technology, and discovery.
Christina Koch sits down with James Manyika, Google’s Senior Vice President of Research, Labs, Technology & Society.
Running Next Flash IQ3_XXS at ~70 tok/s with 100k context or 2 instances of Qwen 3.6 35B A3B IQ4 at ~145 tok/s with 256k all on $500 of ex mining BC-250 boards
This will be my third update on the bc-250 cluster and for my first forray into local ai I have been having a blast.
Building a 4x R9700 setup for a 10 person startup
Just wanted to share a build I am doing for a client.
Strata with Qwen3.8 Flash Next UD-Q4_K_XL
Most of the benchmarks I've seen are using IQ2 or IQ3 quants, so I wanted to see how Unsloth's UD-Q4KXL performs instead.
Faster Scientific Image Analysis with NVIDIA cuPhoton
Observatories and telescopes, lasers and X-ray light sources, and other high-throughput instruments generate image data faster than CPU-bound pipelines can...Observatories and telescopes, lasers and X-ray light sources, and other high-throughput instruments generate image data faster than CPU-bound pipelines can process it to support timely decisions.
AMD Reportedly Raises GDDR6 Prices for Board Partners
Is an AMD price incoming as well?
How DOCA GPUNetIO Unifies GPU-Initiated Networking Across the NVIDIA Software Stack
GPU applications increasingly need networking and data movement to behave like first-class GPU-controlled operations rather than host-driven services.

vllm-ascend updates (GLM5.3-flash) on dual 310p Ascend cards
Alright, I learend a few valuable lessons since I posted about a week ago, and I've made more strides with the DDR4x Ascend 96GB 310P cards I purchased, so here we go, meet the new friendly and less verbose me.
Is there a better option than llama.cpp for 4GB VRAM for Higher tokens/sec?
I want something that utilizes my system resources more efficiently—for instance, by managing my RTX with 4GB VRAM more intelligently—and delivers higher tokens-per-second, all without the burden of heavy dependencies like PyTorch.
 Video
Taming the AI Hardware Cambrian Explosion — Abdul Dakkak, Modular
Abdul Dakkak, chief scientist at Modular, explains why today's AI software stack is a mess, with vLLM, SGLang, TensorRT-LLM and llama.cpp each patching around different hardware, and how Modular rebuilt the stack from the ground up.
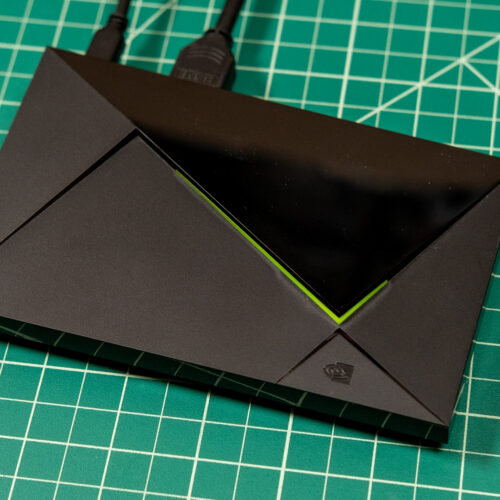
The 7-year-old Nvidia Shield TV is now $100 more expensive due to AI
Nvidia has just announced that the Shield TV Pro is getting $100 more expensive, effective immediately.
Validate AI Factory Changes with Digital Twins and AI Agents
AI factories are some of the most complex operations in the world, combining GPUs, CPUs, switches, DPUs, and SuperNICs alongside schedulers, orchestration...AI factories are some of the most complex operations in the world, combining GPUs, CPUs, switches, DPUs, and SuperNICs alongside schedulers, orchestration services, security controls, and a rapidly changing software stack.
The Machines that Make the Machines
However, the process of assembling GB300 trays requires skilled physical labor in factories across the world.
Expanding AI Storage Access with NVIDIA cuObject and the NVIDIA SCADA Server SDK
AI infrastructure engineers, storage developers, and cloud service providers need fast and secure access to high-capacity file and object storage to support AI...AI infrastructure engineers, storage developers, and cloud service providers need fast and secure access to high-capacity file and object storage to support AI workloads.
Building Reliable Data Analytics Agents: Lessons from the KDD Cup
The NVIDIA KGMON team placed second in the KDD Cup 2026 Data Agents competition with a system built around a simple idea of making an agent's harness smaller,...The NVIDIA KGMON team placed second in the KDD Cup 2026 Data Agents competition with a system built around a simple idea of making an agent’s harness smaller, clearer, and easier to verify.
Expert Coupling in MoE Pretraining: Reducing All-to-All Overhead with Correlated Placement and Token Shuffling
Mixture-of-Experts (MoE) layers replace the feed-forward block of a Transformer with E expert networks, and each token is routed to k of these experts.
GLIO2: A GPU-Parallelized Tightly-Coupled LiDAR-Inertial-GNSS System for Robust and Real-Time Global Localization and Mapping
We propose GLIO2, a tightly-coupled LiDAR-Inertial-GNSS system whose GPU-parallel front-end jointly optimizes scan-to-multiscan LiDAR, IMU pre-integration, and raw GNSS measurements in a single sliding-window factor graph, sustaining real-time operation on edge hardware.
No more RTX 5090
Nvidia reportedly halts GeForce RTX 5090 production in favor of AI data center and professional GPUs — impending supply drought expected to drive up prices, RTX 5080 24GB rumored as new gaming flagship
NVIDIA Open Agent Safety Platform: A Reference for Continuous In-Silicon Agent Monitoring
To understand where agentic AI stands today, consider the last seismic shift in technology: the rise of the internet in the 90s.
How NVIDIA DSX MaxLPS Maximizes AI Factory Throughput and Efficiency
AI factories are typically provisioned for the unlikely moment when every GPU reaches peak power, creating a...Every unused watt is capacity left on the table.
US arrests tech CEO accused of smuggling $300M in Nvidia chips into China
The US has arrested another suspect accused of smuggling high-end computer servers containing export-controlled Nvidia chips into China.
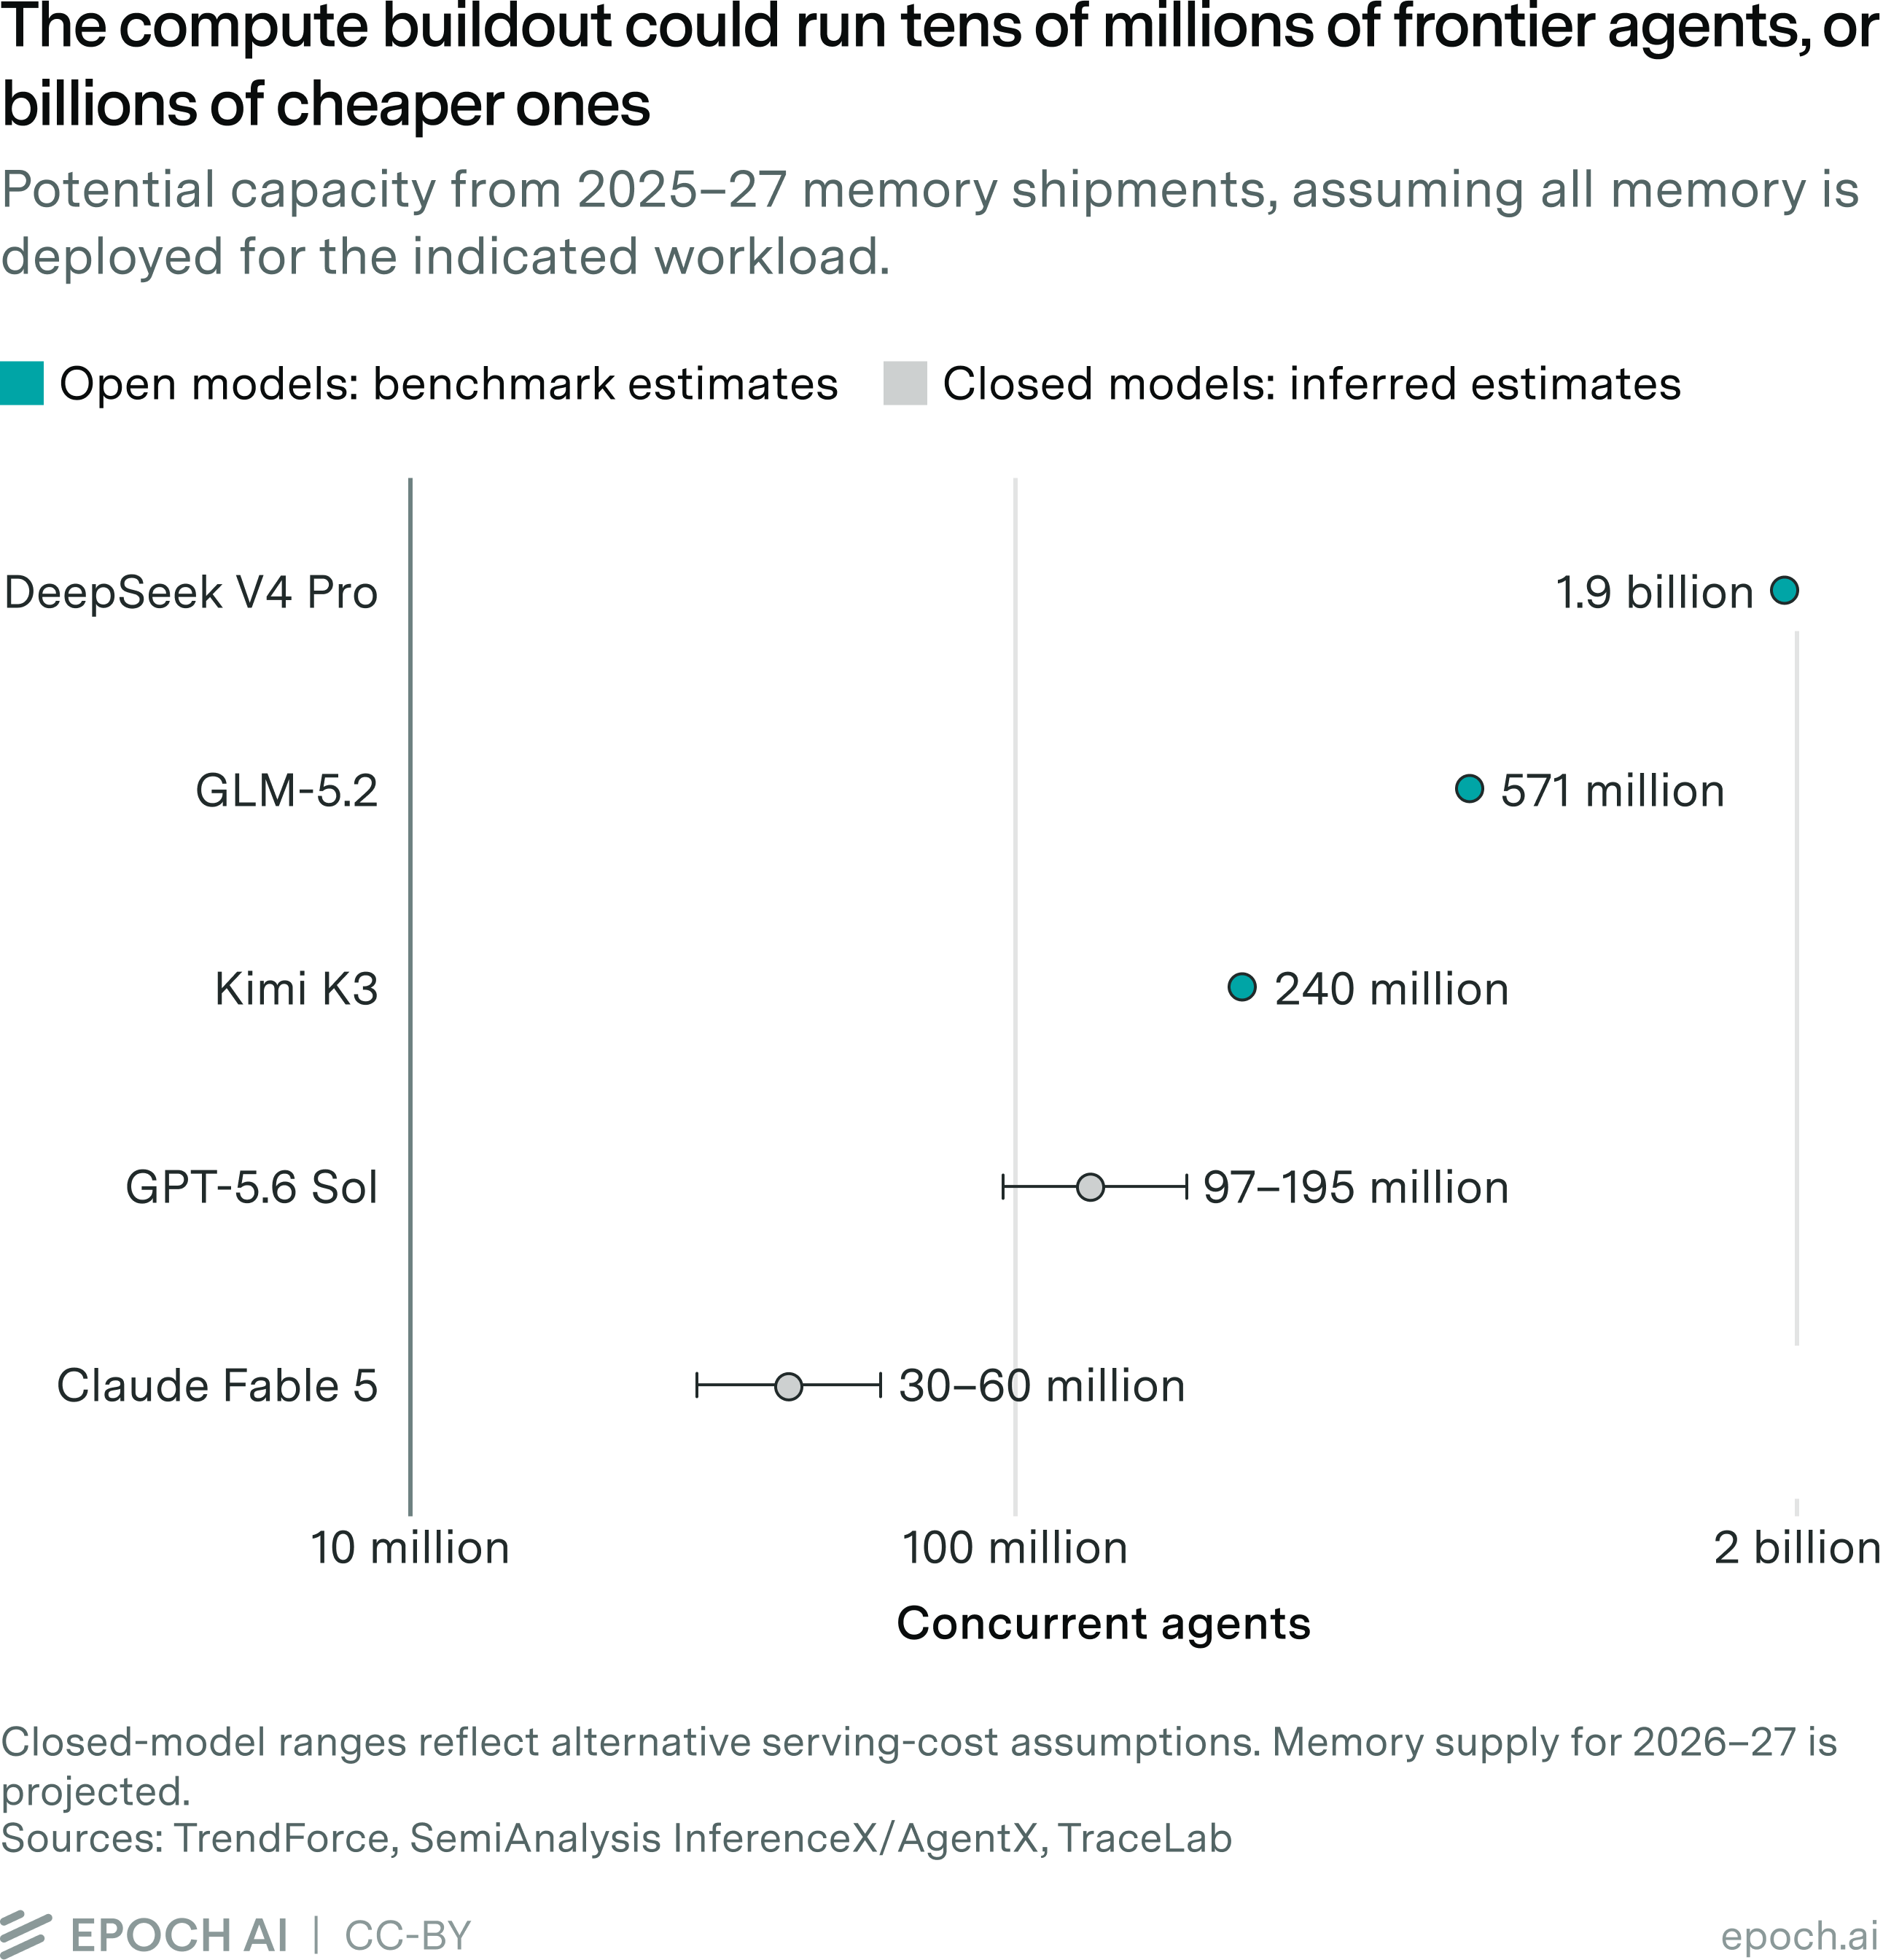
Hundreds of millions of AI agents are coming. Is there work for them?
AI companies are shelling out hundreds of billions of dollars each year on chips and data centers, betting that the massive compute buildouts will run AI agents capable of doing work that people do today.
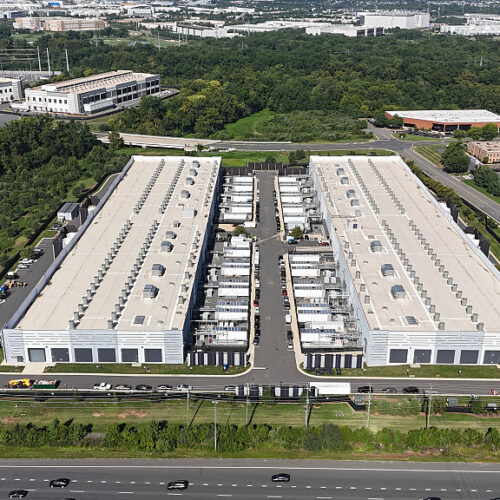
Amazon’s $1B plan to combat data center backlash draws more backlash
On Friday, Amazon committed to donating more than $1 billion over the next five years to communities neighboring data centers.
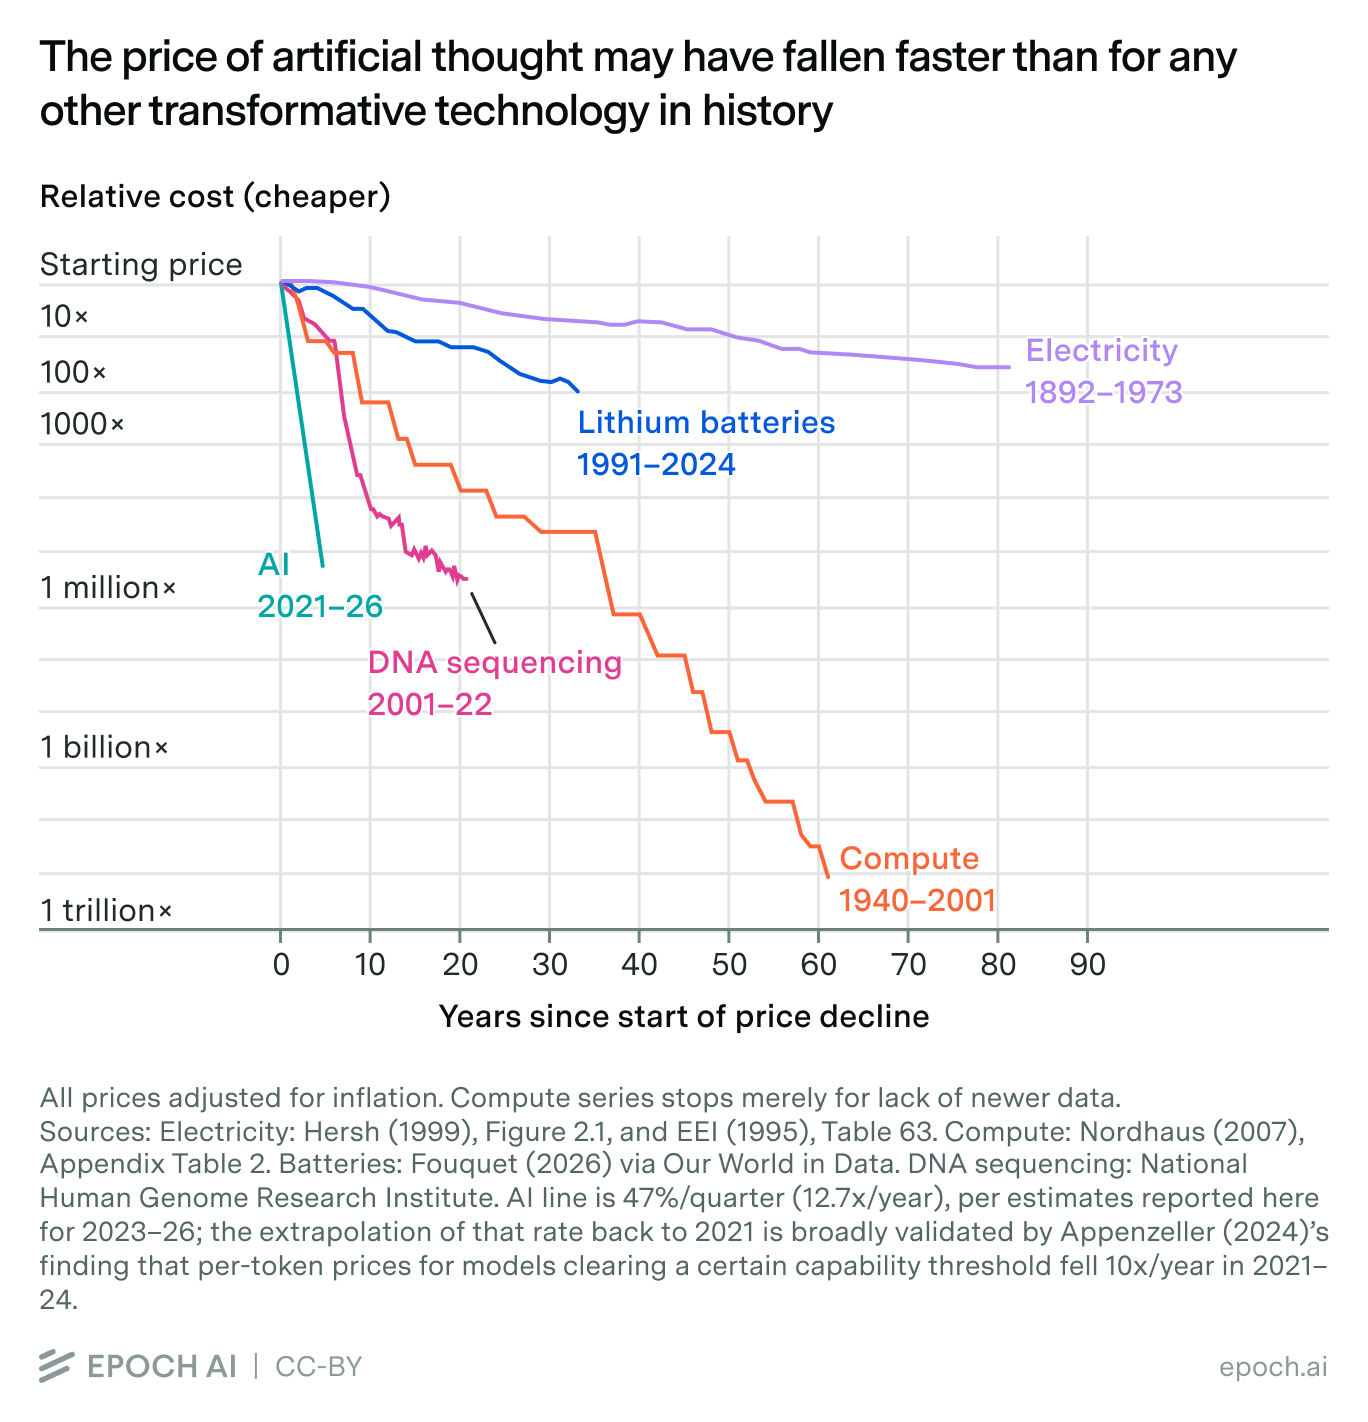
AI is getting cheaper faster than any other transformative technology
Because that’s how fast AI is getting cheaper.

3 days to TechCrunch Disrupt 2026: Meet the startups before they hit mainstream
TechCrunch Disrupt 2026 takes place October 13-15 in San Francisco.
4090 VS 5090 MINIMAX H3 SPEED
To those who used to have a 4090, what percentage of speed improvement have you noticed after upgrading to a 5090?
M5 Ultra 256GB or 2x DGX Spark? Which one?
Currently contemplating adding either M5 Ultra 256GB or dual DGX Spark in addition to existing 5090.