Explore
Everything AION read, in seven sections. Pick one, a topic or a time window.
 Video
Why DeepSeek Wants AI To Forget
📝 The DeepSeek OCR paper is available here:

vllm-ascend updates (GLM5.3-flash) on dual 310p Ascend cards
Alright, I learend a few valuable lessons since I posted about a week ago, and I've made more strides with the DDR4x Ascend 96GB 310P cards I purchased, so here we go, meet the new friendly and less verbose me.
 Video
AI Apps in a Flash: Ship to GPUs Without Docker — Dean Quiñanola, Runpod
Dean Quiñanola, staff engineer at Runpod, introduces Runpod Flash, which lets you run Python on cloud GPUs as if the GPU were local, with no Dockerfiles, image builds or registry pushes.

Updated ComfyUI-SeedVR2-VideoUpscaler-with-TensorRT v1.6.6 - Native ConvRot W4A8 Support & DisTorch2 Scope
The other day, when I published information about v1.5.7, I received a request in the comments regarding support for w4a8.
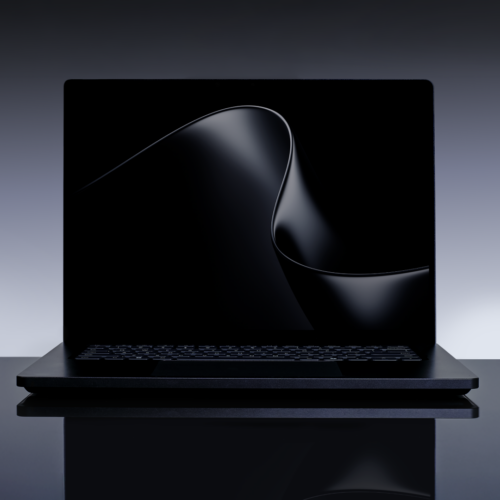
Microsoft event debuts new AI-friendly hardware and Windows changes
In its first live event in two years, Microsoft today announced its newest Surface laptop, outlined a host of changes coming to Windows 11, and shared a vision of how local-AI and agentic workflows could reshape personal computing for those in the dev community as well as home enthusiasts.

Cheaper AI tokens are driving more demand, and that's Jensen Huang's best-case scenario
Data from a16z shows a Jevons paradox in the AI market: token prices keep falling, but H100 GPU rental prices hold steady or climb.
Scaling Decision Optimization to 100 Million Variables and Beyond with mPDLP in NVIDIA cuOpt
NVIDIA cuOpt GPU-accelerated decision optimization can already deliver speedups of more than 10x over CPU...

48 hours to TechCrunch Disrupt 2026 — hear directly from the people building what’s next
Less than 48 hours, TechCrunch Disrupt 2026 starts in San Francisco’s Moscone West.
Help With Choosing Hardware [P]
I am going to fine-tune a satire model, with the base model being Qwen3.5-14B-Base.
The Epoch Brief - October 8, 2026
Welcome back to the Epoch Brief.
Impactful scheduling for GPU clusters
On the AI Infrastructure team at Ai2, we’re responsible for providing the institute’s GPU compute capacity, specifically targeting large, distributed training workloads.
GLIO2: A GPU-Parallelized Tightly-Coupled LiDAR-Inertial-GNSS System for Robust and Real-Time Global Localization and Mapping
We propose GLIO2, a tightly-coupled LiDAR-Inertial-GNSS system whose GPU-parallel front-end jointly optimizes scan-to-multiscan LiDAR, IMU pre-integration, and raw GNSS measurements in a single sliding-window factor graph, sustaining real-time operation on edge hardware.
What to expect during the AI Data Pipeline Forum: Join theCUBE Oct. 13
The post What to expect during the AI Data Pipeline Forum: Join theCUBE Oct.
Expanding our enterprise inference capacity with IBM Cloud and NVIDIA
Enterprises can now run open models at production scale on a dedicated B300 inference cluster, built by Together AI, IBM Cloud, and NVIDIA
The Computer Game
Build the best computer, from stone tools to your own chips

Master AI Chip Principles With New IEEE Design Program
Today’s engineers face an unprecedented acceleration in AI hardware complexity, as explained in the recent research article “Revisiting Edge AI: Opportunities and Challenges.” The article examines the rapid growth of edge AI and the challenges it creates, including resource constraints, model architecture limitations, and network demands across edge-AI deployments.
Qwen3.8 Flash Next fixed my GNOME extension
I love Dash2Dock Lite, but Icedman is always a week or two before updates.
Running Next Flash IQ3_XXS at ~70 tok/s with 100k context or 2 instances of Qwen 3.6 35B A3B IQ4 at ~145 tok/s with 256k all on $500 of ex mining BC-250 boards
This will be my third update on the bc-250 cluster and for my first forray into local ai I have been having a blast.
Building a 4x R9700 setup for a 10 person startup
Just wanted to share a build I am doing for a client.
AMD Reportedly Raises GDDR6 Prices for Board Partners
Is an AMD price incoming as well?
Strata with Qwen3.8 Flash Next UD-Q4_K_XL
Most of the benchmarks I've seen are using IQ2 or IQ3 quants, so I wanted to see how Unsloth's UD-Q4KXL performs instead.
Is there a better option than llama.cpp for 4GB VRAM for Higher tokens/sec?
I want something that utilizes my system resources more efficiently—for instance, by managing my RTX with 4GB VRAM more intelligently—and delivers higher tokens-per-second, all without the burden of heavy dependencies like PyTorch.
No more RTX 5090
Nvidia reportedly halts GeForce RTX 5090 production in favor of AI data center and professional GPUs — impending supply drought expected to drive up prices, RTX 5080 24GB rumored as new gaming flagship
4090 VS 5090 MINIMAX H3 SPEED
To those who used to have a 4090, what percentage of speed improvement have you noticed after upgrading to a 5090?
M5 Ultra 256GB or 2x DGX Spark? Which one?
Currently contemplating adding either M5 Ultra 256GB or dual DGX Spark in addition to existing 5090.
Be careful fam - New RTX 4090 fakes hit the market, with GPUs and memory almost indistinguishable from real chips
Be careful out there of deals now.
M5 Ultra Mac 256GB Studio - 64 core vs. 80 core version, is the inference speed difference worth the extra 10 weeks wait time?
I’m seeing 6-7 week delivery wait time for M5 Ultra Mac Studio 64 core version versus 15-17 weeks for 80 core version.
Building Reliable Data Analytics Agents: Lessons from the KDD Cup
The NVIDIA KGMON team placed second in the KDD Cup 2026 Data Agents competition with a system built around a simple idea of making an agent's harness smaller,...The NVIDIA KGMON team placed second in the KDD Cup 2026 Data Agents competition with a system built around a simple idea of making an agent’s harness smaller, clearer, and easier to verify.
Faster Scientific Image Analysis with NVIDIA cuPhoton
Observatories and telescopes, lasers and X-ray light sources, and other high-throughput instruments generate image data faster than CPU-bound pipelines can...Observatories and telescopes, lasers and X-ray light sources, and other high-throughput instruments generate image data faster than CPU-bound pipelines can process it to support timely decisions.

3 days to TechCrunch Disrupt 2026: Meet the startups before they hit mainstream
TechCrunch Disrupt 2026 takes place October 13-15 in San Francisco.
Validate AI Factory Changes with Digital Twins and AI Agents
AI factories are some of the most complex operations in the world, combining GPUs, CPUs, switches, DPUs, and SuperNICs alongside schedulers, orchestration...AI factories are some of the most complex operations in the world, combining GPUs, CPUs, switches, DPUs, and SuperNICs alongside schedulers, orchestration services, security controls, and a rapidly changing software stack.
The Machines that Make the Machines
However, the process of assembling GB300 trays requires skilled physical labor in factories across the world.
big or small?
what size do you want? tell them on X:
How DOCA GPUNetIO Unifies GPU-Initiated Networking Across the NVIDIA Software Stack
GPU applications increasingly need networking and data movement to behave like first-class GPU-controlled operations rather than host-driven services.
Democratizing MoE inference on commodity GPUs with CoMoE
We present CoMoE, a communication-efficient MoE inference system that resolves this mismatch through novel host-centric routing.
TechCrunch Disrupt 2026 starts in 4 days — lock in your pass savings of up to $100 before prices rise
Four days until TechCrunch Disrupt 2026 starts, when 10,000 founders, investors, and tech leaders gather in San Francisco's Moscone West on October 13-15.
Expert Coupling in MoE Pretraining: Reducing All-to-All Overhead with Correlated Placement and Token Shuffling
Mixture-of-Experts (MoE) layers replace the feed-forward block of a Transformer with E expert networks, and each token is routed to k of these experts.
Cova-PINN: Cross-Domain Conservation Physics-Informed Neural Network for Fluid-Solid Conjugate Heat Transfer in Complex Geometries
Multi-domain physics-informed neural networks (PINNs) flexibly model medium-specific representations to solve fluid--solid conjugate heat transfer (CHT).
CPU-Auth: Device Fingerprinting for Authentication via DVFS Side-Channel
This work explores CPU-Auth, a novel authentication mechanism based on unique variations in the physical characteristics of the CPU of a computing device.
PoreML: A Data-Driven Framework for Learning Multiphase Flow in Porous Media
Multiphase flow in porous microstructures is central to CO$2$ storage, fuel-cell operation, and flip-chip packaging.
iwant
Find available GPUs and host open models in one command
Embedded Evaluation of Task Admission Coalescing in Decentralized Multi-Robot Systems
Multi-robot task allocators in dynamic missions commonly admit newly released tasks immediately, potentially invoking allocation for each new arrival.
AICR v1.0: Open, stable, and verifiable GPU cluster configuration
GPU-accelerated Kubernetes clusters depend on compatible versions across dozens of components, each on its own release cycle: host kernels, GPU drivers,...GPU-accelerated Kubernetes clusters depend on compatible versions across dozens of components, each on its own release cycle: host kernels, GPU drivers, container runtimes, networking, storage, operators, and workload frameworks.
Control How Your GPU Shares Work with Green Contexts
Controlling how GPU resources are shared between them remains difficult.
Pine Computer
A cloud computer built for AI to get jobs done
X-OPM: Explainable Automatic Digital On-Chip Power Modeling for Enhanced Robustness
Grounded in the design principles of synchronous digital VLSI circuits, X-OPM introduces a robust feature engineering framework that uses tree-based models to capture feature interactions and linear models for prediction.
Accelerating the Development of PLGA In Situ Forming Depots Through AI-Driven Multi-Objective Optimization
Developing long-acting injectable formulations requires the simultaneous optimization of drug loading, release kinetics, viscosity, injectability, stability and other objectives.
HeyPi
Build and ship anything live, in-meetings