Explore
Everything AION read, in seven sections. Pick one, a topic or a time window.
Multi-Agent Egocentric World Model with Fine-Grained Embodied Interaction
We propose Multi-agent Egocentric World Model (ME-World), which jointly denoises multiple ego streams in a shared token sequence, conditions each stream on all agents' target-view poses, and grounds generation with shared environment memory.

Odyssey-3 is a new generative world model that you can try for free
Odyssey is making its world model Odyssey-3 available as a public research preview.
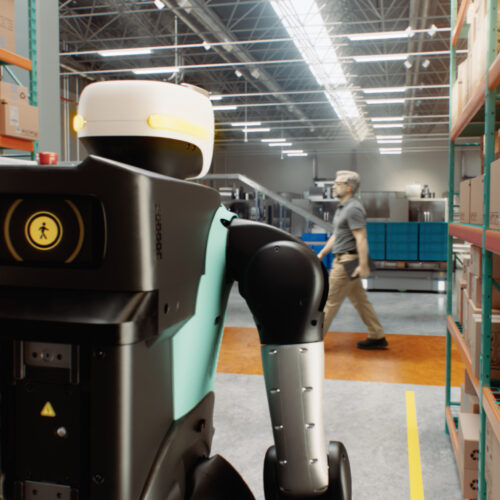
Nvidia's big bet on physical AI aims for safer robotaxis, humanoid robots
“Now the AI models are getting capable, the robot hardware is getting capable, and a thing we thought is going to be the next bottleneck is safety,” Amit Goel, head of robotics ecosystem and edge computing at Nvidia, told Ars. “So that's why we launched our Halos for Robotics to unlock the capability of these systems.”
Building AI for Reliable Execution: Lessons From Industrial Robotics
Standard Bots claims to be “America’s largest AI-native industrial robot manufacturer.” It recently raised $200 million at a $1 billion valuation, in a series C round led by General Catalyst and RoboStrategy, a fund focused on robotics.
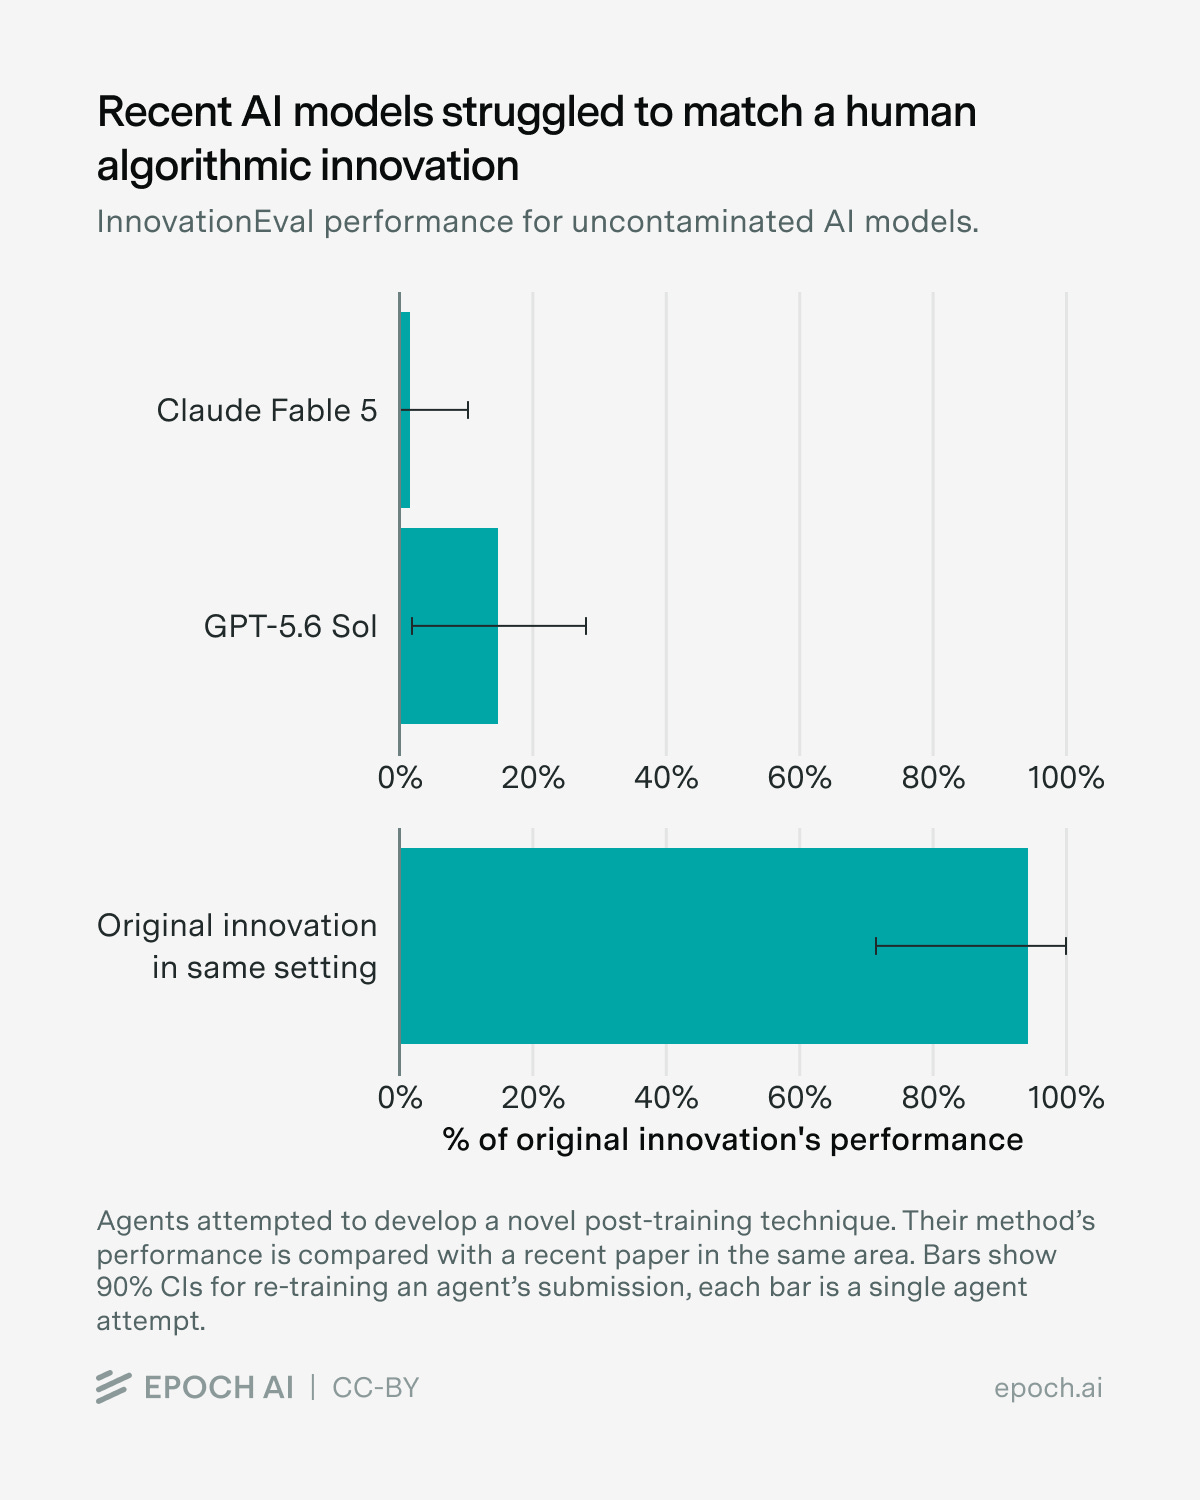
Can AI automate AI R&D yet?
Existing evidence shows that AI can perform software engineering tasks relevant to AI research, dataset creation, open-ended optimization of defined metrics (autoresearch), and more.
FearCaut-Qwen: Affective Steering in a Vision-Language Model Shifts the Decision Criterion for Hazard Assessment
Vision-language models (VLMs) show great potential for damage assessment after a disaster, but a recurring deficiency is that they are reluctant to declare a hazard; that is, recall is low even when overall accuracy appears adequate.

She Designed Meta’s New AI Logo. Then Came the Hate
Jessica Hische knew working for Meta might upset some people.
Claude Dashboards & Motion
Ask Claude for live dashboards and animated explainers
The Machines that Make the Machines
However, the process of assembling GB300 trays requires skilled physical labor in factories across the world.
Introducing Dan Kagan-Kans
We just published the first post by our newest writer, Dan Kagan-Kans.

Attempts to Keep Humans in the AI Loop May Actually Push Them Out
A crucial safeguard against AI agents going rogue—keeping humans in the loop to review and approve their decisions—will fail unless designers and users change their current practices, a trio of leading AI ethics researchers argue.
LWiAI Podcast #258 - Opus 5.5, Sol and Luna, Muse, DeepSeek-V4.1-Flash, Xi
Our 258th episode with a summary and discussion of last week’s big AI news!
Bringing predictive analytics to the agentic AI era
In 2026, the question for enterprise AI is no longer whether predictive models can outperform statistical forecasts—that argument is settled.
Show HN: Made an open-source Lego AI generator
So, the idea I had was: if I manage for maybe ChatGPT or Claude to generate high-quality LDraw source files... then, they would actually be generating high-quality LEGO CAD models, right?
huggingface/peft v0.21.2
This is a PEFT release fixes an issue that prevented encoder-decoder models to work when using Transformers ≥ 5.18.0.
What work can robots do?
We present a robot exposure index based on how well robots can perform job tasks today.

How Much of a Harness Does a Strong Agent Need for Autonomous ML Engineering?
In this paper we find that, under an equal time budget and the same frontier LLM backbone, open-source state-of-the-art harnesses provide no advantages over a single session of a minimal-harness coding agent baseline, pointing to the backbone as the primary driver for performance.
Import AI 474: Platonic mindspace; TPUs in space; Zhipu starts an outer RSI loop
Are minds patterns from a Platonic space, with bodies and machines as their interfaces, Michael Levin asks:
Team Bots: shared AI teammates that learn as they work
Today we’re launching Team Bots, Grok Bots that work and learn alongside your team.
DreamTrue: Action-Faithful Robot World Model with Counterfactual Post-Training
We present DreamTrue, a multi-view, cross-embodiment robot world model for action-faithful and physically plausible video prediction.
SuperNav: An Agentic Navigation System for Any Task in Any Scene
General-purpose service robots need navigation systems that can handle diverse human requests in unfamiliar environments, combining task generality with scene generality.
Embodied Turing Machines: Stateful Code for Robot Recursive Self-Improvement
We propose a different view: the embodied world is an Embodied Turing Machine, whose tape is the robot and environment state and rules are the policy.
Q-Learning with Scalar Adjoint Matching
Adjoint matching offers a principled way to update the flow model itself by propagating value information from the final action back to each flow step, but it requires a vector--Jacobian product through the policy at every step, a cost that grows with the number of flow steps and the policy size.
AgentGarten: Code Worlds for Evolving Agents
We introduce AgentGarten, a framework that couples simulators and game engines with a shared neural renderer to build real-time interactive environments.
SpatialOPSD: Self-Distilling Spatial Intelligence from Verified Coding Agent Traces
Spatial coding agents significantly improve spatial reasoning in Multimodal Large Language Models (MLLMs) by using external tools to generate verified execution traces.
MIMESIS: Learning User Simulators as Training Environments for Interactive Agents
We introduce MIMESIS, a purpose-built user simulator trained on human conversations with explicit reasoning supervision and 13 realistic behavioral patterns derived from real user interactions.
CADFather Reconstructs Parametric CAD Programs Using Coordinated Tools
CADFather is an autonomous agentic system that coordinates complementary tools and a vision-language assistant to reconstruct parametric CAD models from 3D meshes without additional training.
ViSkill: Reinforcing VLM Agents with Evolving Visual-Native Skills
We propose ViSkill, a visual-native skill learning framework that encodes successful interactions as composite visual skill cards directly accessible to VLM agents.
RoboJEPA: Scaling Laws for Multi-Embodiment Robotic Latent World Models
Researchers introduced RoboJEPA, an 8B-parameter multi-embodiment latent world model that establishes compute scaling laws and enables zero-shot real-robot planning toward goal images.
Beyond Spatio-Temporal Priors: A Generalizable Approach for Dense Correspondence Matching
To establish identity-preserving correspondence across such transformations, we introduce FreeMatching, a generalizable framework combining generative and semantic foundation representations with heterogeneous supervision from classical datasets, tracked videos, and synthetic scenes.
SPW-Nav Streams Language-Guided Panoramic Video in Real Time
Researchers introduced SPW-Nav, a panoramic world model that interprets language movement instructions to stream one minute of real-time 2K 360-degree video from a single panorama.
CARE: Certifying Acceleration for Vision-Language-Action Inference
Prior work accelerates VLA inference using techniques like action chunking and visual-token pruning, typically evaluating based on latency and average task success.
USDCraft: Geometrically Grounded Programmatic Modeling of Articulated 3D Assets for Simulation
To address these limitations, we formulate articulated asset reconstruction as programmatic modeling grounded in partial geometric evidence and introduce USDCraft, a framework in which a pretrained LLM writes and revises executable programs for simulation-ready articulated assets without task-specific training.
UniSkill: Learning Actor-Aligned Skill Proposals for an Evolving Policy
In this paper, we introduce UniSkill, which uses a shared policy to interact with the environment and propose skillbank edits (Add, Update, or No Edit) from the resulting trajectories.
From Prompting to Composing: A Spatial Canvas Interface for Poster Generation
We introduce a Spatial Canvas Interface that enables users to directly compose generation intent in space through four complementary binding types: semantic, identity, text, and pixel, together with Text Specifications for individual elements and global appearance.
BrickBench: Evaluating Agentic Brick Design
We propose BrickBench, a benchmark for agentic text-conditioned LEGO-set design.
System Switch: When Should a Fast Decision Model Stop and Think?
Dual-process agents pair a fast policy with a slow deliberative model.
Predicting Cable Dynamics with Physical Attention Bias
Learned simulators for deformable linear objects (DLOs) such as cables have to predict the motion of cables they were not trained on and stay stable over long rollouts.

AI agents overstate their results and remain far from autonomous research, study finds
Epoch AI and Anthropic independently found the same thing: current AI models like GPT-5.6 Sol and Claude Fable 5 can run experiments but lack scientific self-criticism and genuine creative thinking.
A Stevens's Power Law Check-up of GPT-5.5's Implicit Reading of Visual Encoding
We adapt Stevens's power law to measure the implicit ability of AI models to read visualizations, which can reveal the built-in perceptual mechanisms of algorithmic models.
Spatial Latent Reasoning for Embodied Reference Understanding
We propose Spatial Latent Reasoning (SLR), a framework that structures this supervision around an ordered sequence of geometric and visual states.
MetaLearnNCA: Few-Shot Offline Meta-Learning via Interacting Neural Cellular Automata
In this work, we propose METALEARNNCA, a decentralized framework that achieves few-shot adapta- tion through the dynamical interaction of coupled Neural Cellular Automata (NCAs) without computing analytical gradients during inference.
Evaluating the Transfer of Co-Evolved Communication from 2D to 3D Simulation
This work examines the transfer of a co-evolved communication mechanism between two robotic agents from a discrete two-dimensional (2D) simulator to a three-dimensional simulator with real physics (3D).
Learning from Revision Consequences: Hindsight Meta-Experience Distillation for Self-Improving Agents
We introduce HMED (Hindsight Meta-Experience Distillation), a mechanism for constructing Meta-Experience for self-improving agents.
Rewiring Semantics, Dynamics, and Control: A Simple yet Effective Action-Centric Tri-Stream Transformer
Vision-Language-Action (VLA) models have emerged as a prominent framework for complex robotic manipulation, building on the strong semantic understanding of pretrained Vision-Language Models (VLMs).
Deflating the Hessian: Rank-4 W4A4 Quantization for Multimodal Diffusion Transformers
In diffusion transformers, low-rank branches can mitigate 4-bit weight--activation (W4A4) post-training quantization (PTQ) loss by decomposing each weight into a low-bit residual and a high-precision low-rank component.
Design of a Fully Actuated 4-DOF Robotic Finger With Joint-Specific Hybrid Remote Actuation
This paper presents a fully actuated 4-DOF robotic finger using a joint-specific hybrid remote-actuation architecture.
RFChipAgent: Multi-Agentic AI Flow for Analog/RF Chip Design
We present RFChipAgent, a first-of-its-kind multi-agent flow of large language model (LLM) agents for end-to-end analog/RF circuit design automation, in which AI agents collaboratively orchestrate the complete design flow under human supervision.