Explore
Everything AION read, in seven sections. Pick one, a topic or a time window.
Qwen/Qwen-Image-2.1-Turbo
Qwen published the model Qwen-Image-2.1-Turbo on Hugging Face.

Odyssey-3 is a new generative world model that you can try for free
Odyssey is making its world model Odyssey-3 available as a public research preview.
Understanding Jev, the new model everyone is talking about
On September 15, the startup TypeSafe AI came out of stealth and released a new AI model.
microsoft/AesCode 8B and 32B
AesCode generates information-rich visual artifacts such as slides, posters, and dashboards as HTML/CSS.
Multi-Agent Egocentric World Model with Fine-Grained Embodied Interaction
We propose Multi-agent Egocentric World Model (ME-World), which jointly denoises multiple ego streams in a shared token sequence, conditions each stream on all agents' target-view poses, and grounds generation with shared environment memory.

Best way to use H3 ref2video. Not even joking. it just works and is easier to manage than any replacing attempts fighting the Model
Just draw your composition and let Minimax figure it out instead of using references from the internet
Introducing Playground: Create and play custom games
Playground is a new experimental gaming platform that lets you create, play, and share custom games.
openai/codex rust-v0.162.1: 0.162.1
Fixed a TUI crash when asynchronous questions contain multiple lines, preserving line breaks and complete hyperlink destinations. (#51866)
anthropics/claude-code v2.1.296
Added a code key to the Claude apps gateway's managed.policies[]: the same settings as cli, also applied in Claude Desktop's Code tab; beside desktop, it turns on Claude Desktop's gateway mode
AI disqualification yields new Nikon Small World in Motion winner
Last month we covered the winner of Nikon's Small World in Motion video: Ning Xu of Tsinghua University in China, whose video captured tiny cilia beating in the airways of a child with a rare respiratory disorder.
Introducing Mistral Large 4
Today, we’re launching a public preview of Mistral Large 4.
Claude Dashboards & Motion
Ask Claude for live dashboards and animated explainers
WorldCast: Distributed Multiplayer World Models
We present WorldCast, a distributed multiplayer world model in which each player runs a local client comprising a video generator and a state model.
 Paper
Normalizing Trajectory Models
We introduce Normalizing Trajectory Models (NTM), which models each reverse step as an expressive conditional normalizing flow with exact likelihood training.
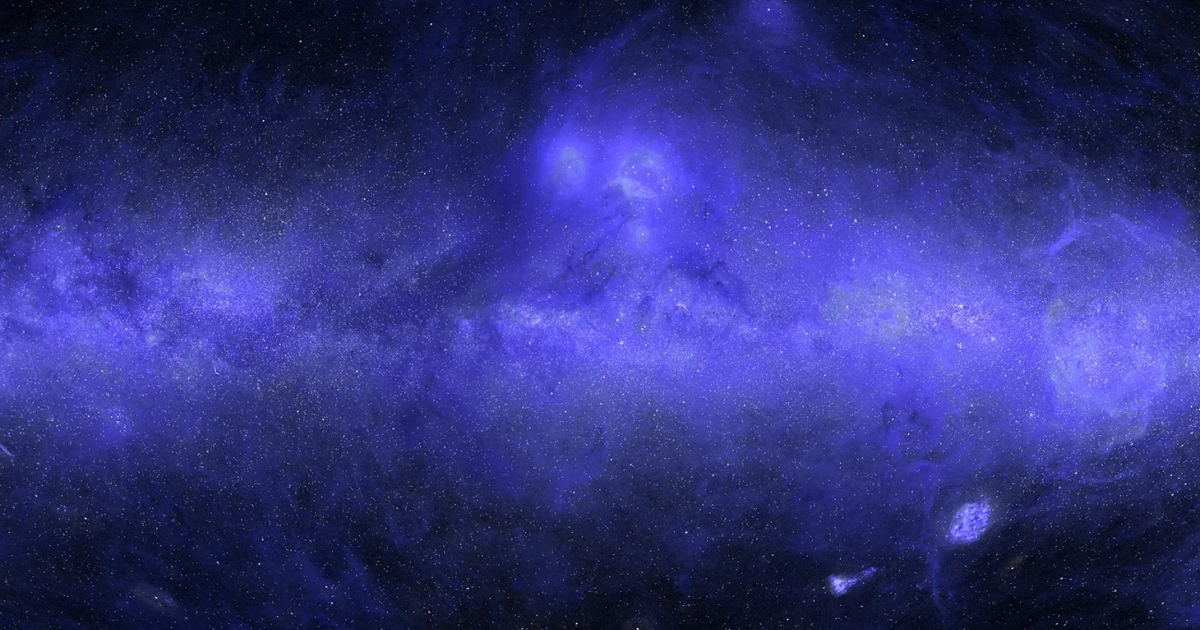
The missing map of the sky
Here, Brice Ménard, an astrophysicist at Johns Hopkins University and a researcher at Anthropic, explains how he worked with Claude Science to produce the first complete map of the sky in UV light.
langchain-ai/langgraph cli==0.4.33: langgraph-cli==0.4.33
feat(cli): add 'langgraph deploy listeners list' (#9221)
huggingface/diffusers v0.41.0: Diffusers 0.41.0: QwenImage 2.1 pipeline and more
> This release brings Qwen-Image 2.1 to Diffusers, with text-to-image generation, image editing, native transparency, and LoRA training.
Quoting Ben Affleck
And a tensor, you use a convolutional neural network to identify patterns in that that would reveal what's called edge detection or feature extraction, which is just identifying patterns enough to know like this is where the window ledge is, so we can more easily take the green screen image out and replace it with something.
speridlabs/iris-3b
speridlabs published the model iris-3b on Hugging Face.
How to pick the right models and dramatically speed up image and video generation speeds & What I wish I knew when starting on AMD hardware with ComfyUI
For the below I’ll be referring mostly to ComfyUI workflow and model efficiency (using examples for Radeon AI PRO R9700 (32GB) which has a bandwidth of 680GB/sec.
LEGO: A Lifting-Free Approach for Exocentric-to-Egocentric Video Generation
Generating an egocentric video from a single exocentric recording is a challenging case of novel view synthesis, as the two cameras share little overlap and much of the target view is unobserved.

Updated ComfyUI-SeedVR2-VideoUpscaler-with-TensorRT v1.6.6 - Native ConvRot W4A8 Support & DisTorch2 Scope
The other day, when I published information about v1.5.7, I received a request in the comments regarding support for w4a8.

Long Shot Studio v0.6.13 (degradation test)
After more back and forth with Claude for optimization and UI change, here is the latest update of Long Shot Studio.
Reasoning-Informed Visual Editing
To study this gap, we introduce RISEBench, the first benchmark for evaluating Reasoning-Informed viSual Editing (RISE), and extend it to RISEBench++, a more comprehensive and fine-grained benchmark for this emerging task.
OuroWorld: Bringing Any 3D World Alive as Diverse, Endlessly Looping 3D Cinemagraphs
OuroWorld is a mask-free framework that turns any static 3D Gaussian Splatting scene into a 3D cinemagraph: a dynamic scene with vivid, diverse motion looping seamlessly from any viewpoint.
WorldGuide: Goal-Directed Video World Model for Procedural Task Execution
We formulate procedural video generation as closed-loop task execution in visual world space and introduce WorldGuide.
[Model] Support MiniCPM-V 4.7 by tc-mb · Pull Request #29416 · ggml-org/llama.cpp
Let me remind you that MiniCPM-V-4.7-35B-A3B was spotted on r/LocalLLaMA a few days ago (but the model was later hidden on HF).
VibeEdit: Image Editing with Canvas Instructions
We introduce a new image editing interface that lets users place spatial marks and optional short notes directly on the image.
AgentGarten: Code Worlds for Evolving Agents
We introduce AgentGarten, a framework that couples simulators and game engines with a shared neural renderer to build real-time interactive environments.
Google rolls out improved SynthID AI content detector, now available globally
Every piece of AI content from Google's Gemini models has a hidden SynthID label, which makes it very difficult to pass the content off as authentic.

Krea2 Turbo Distill 2 step LoRA - FINAL checkpoint released (chk51195)
Krea 2 Turbo — 2-Step Distillation LoRA (FINAL Version)

TensorSharp now supports Qwen Image 2.1 Turbo + LoRA — Here's a quick image editing demo
I've been working on adding more image generation and editing capabilities to TensorSharp, and I'm happy to share that it now supports Qwen Image 2.1 Turbo and LoRA!
Beyond Spatio-Temporal Priors: A Generalizable Approach for Dense Correspondence Matching
To establish identity-preserving correspondence across such transformations, we introduce FreeMatching, a generalizable framework combining generative and semantic foundation representations with heterogeneous supervision from classical datasets, tracked videos, and synthetic scenes.
openai/codex rust-v0.162.0: 0.162.0
Add tools for creating and listing managed Git worktrees from trusted local projects when the worktrees feature is enabled. (#50148)
Pumpire: Unified Benchmark for Metric Distance Estimation
We present Pumpire, a unified benchmark for evaluating metric point-pair distance estimation capability of both image- and video-level 3D foundation models, with or without depth priors.
Q-Learning with Scalar Adjoint Matching
Adjoint matching offers a principled way to update the flow model itself by propagating value information from the final action back to each flow step, but it requires a vector--Jacobian product through the policy at every step, a cost that grows with the number of flow steps and the policy size.
anthropics/claude-code v2.1.295
Added onFailure: "block" for command and HTTP hooks: a hook that can't start, times out, or exits with an unexpected code blocks the action instead of letting it through
From Prompting to Composing: A Spatial Canvas Interface for Poster Generation
We introduce a Spatial Canvas Interface that enables users to directly compose generation intent in space through four complementary binding types: semantic, identity, text, and pixel, together with Text Specifications for individual elements and global appearance.
SpaceFlow: Locally Controllable 3D Generation
We present SpaceFlow, a training-free pipeline for locally controllable 3D generation from text descriptions and a collection of geometric primitives.
The Lattice of Transition Laws
Diffusion and autoregression (AR) have long been seen as different categories of generative models, with diffusion specialising in continuous fields and AR specialising in discrete tokens.
Iris-3B: Going Beyond the Latent with Pixel-Space Diffusion Training, Conversion and Fine-Tuning
Pixel-space diffusion models avoid the lossy VAE of latent models, which suggests an advantage on downstream tasks where fine-grained detail matters.
CADFather Reconstructs Parametric CAD Programs Using Coordinated Tools
CADFather is an autonomous agentic system that coordinates complementary tools and a vision-language assistant to reconstruct parametric CAD models from 3D meshes without additional training.
anthropics/claude-code v2.1.293
Added Claude Haiku 5.5 (claude-haiku-5-5), now the default Haiku model on the Anthropic API — 1M context, $0.10/$0.50 per Mtok ($0.50/$2.50 for prompts over 100K)
MIRA: A Musical Intent Refinement Agent for Aligning Text-to-Music Generation with User Intent
To bridge this gap, we formulate text-to-music intent alignment as satisfying a per-request rubric of independently verifiable items covering both a request's explicit requirements and its implied musical intent.
SPW-Nav Streams Language-Guided Panoramic Video in Real Time
Researchers introduced SPW-Nav, a panoramic world model that interprets language movement instructions to stream one minute of real-time 2K 360-degree video from a single panorama.
Deflating the Hessian: Rank-4 W4A4 Quantization for Multimodal Diffusion Transformers
In diffusion transformers, low-rank branches can mitigate 4-bit weight--activation (W4A4) post-training quantization (PTQ) loss by decomposing each weight into a low-bit residual and a high-precision low-rank component.
From Video Clips to Creation Trajectory: Sora100K for AI-Native Video Creation
In this paper, we introduce Sora100K, a dataset that represents the AI-Native video creation workflow as a structured video creation trajectory.
Rubric-CEPR: Self-Evolving Image Editing via Reward-Verified Self-Distillation
To this end, we propose a self-evolving framework, named Rubric-CEPR, that verifies the editor's own samples with its internal representations through a rubric-augmented Contrastive Edit-Preservation Reward (CEPR).